 DottaandClaude Opus 5.5
89f486cdab
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work > - The heartbeat queue starts an agent's queued runs. Each trigger (a run finishes, a wake arrives, a sweep runs) asks for one dispatch pass of that agent > - An agent could run more runs than its `maxConcurrentRuns`, dispatch passes could stack up without a limit, and every pass offered the same unclaimable runs again > - On hosted staging (e23549cd9c), one agent with limit 20 had 20–35 runs `running` and 170–270 queued. The logs showed 375 "offered a free slot but could not be claimed" lines and 117 "claim was rejected" lines in 10 minutes > - This pull request runs one pass per agent at a time, folds triggers into one follow-up pass, backs off refused claims, enforces the limit in the claim transaction, and reads only the columns the pass needs > - The benefit is that an agent never runs past its limit (also across two servers during a deploy), and a burst of triggers costs one or two passes, not one pass per trigger ## Linked Issues or Issue Description Refs #21391, #21242, #21234, #21277, #21324, #21349 **What happened?** On hosted staging (Coree23549cd9c), one agent ("Codie", `maxConcurrentRuns` 20) had 170–270 queued runs and 20–35 runs `running`, so it was over its limit. The logs showed a refused claim offered again on every pass. This pull request is about correctness and load. It is not the cause of the staging out-of-memory crashes: a separate leak (`sessionToolAuthorityEpochs` in `native-session-executor.ts`, about 3 MB per finished native run) explains those, and another change fixes it. Live again at 17:02Z on staging (Core04f12fd2be, which includes #21391): the same agent had 52 runs `running` against `maxConcurrentRuns` 40. All 52 started between 16:55Z and 17:02Z, right after a deploy released the backlog, with 112 runs still queued. So overlapping passes exceed the limit with claimable runs, not only with unclaimable ones. **Why did it happen?** 1. `withAgentStartLock` chained each trigger behind the previous one and measured its 30 s stale limit from when the predecessor was chained, not from when it started. When triggers arrived faster than one per pass, every trigger after about 30 s of backlog started its own pass next to the others. 2. Each pass counted free slots by itself, outside any lock that other passes or another server see. Overlapping passes and two servers during a deploy swap each claimed up to the limit. 3. Each pass read every queued run with `select *`, including the large `contextSnapshot`, and offered every refused run again with no backoff. A local reproduction of the staging shape by another session (250 unclaimable queued runs with 8 KB snapshots, one trigger per second, one23549cd9cand again on mastere7e28ba241): passes that run at the same time went 1 → 12 → 39 → 79 → 139 at t = 30/45/75/116/178 s, only 4 passes finished in 178 s, and post-GC heap grew by about 2.8 MB per stacked pass (519 MB → 1,061 MB at 190 passes, mostly the parsed `heartbeat_runs` rows and the dispatcher facts each pass holds). 242 s after the triggers stopped, 216 passes were still outstanding. **Expected behavior** At most one dispatch pass per agent runs at a time. Triggers that arrive during a pass cause one follow-up pass. The `running` count never goes above `maxConcurrentRuns`. A refused run is offered again after a bounded wait, and no queued run is stranded. **Steps to reproduce** 1. Give an agent a limit of 4, 12 aged queued runs that the chat-control gate refuses, and 12 claimable runs. 2. Start a pass. While its first claim waits, send 40 triggers, each after more than 30 s of the old lock's clock. 3. Count the passes, the refused offers, and the highest `running` count. ## What Changed - `server/src/services/agent-start-lock.ts`: replaces the stale-bypass lock with `dispatchForAgent`. One pass runs per agent. Triggers during a pass merge into one follow-up pass that all their callers share. A trigger from inside the agent's own pass does not wait on itself. A pass has a 60 s deadline on a monotonic clock, measured from when the pass started (not from when a waiter was chained). At the deadline the pass stops claiming (an abort signal) and the follow-up may start. A trigger that arrives after the deadline also ends the pass, so a stalled timer cannot keep an agent blocked. Post-pass effects run after the agent is free, as before. - `server/src/services/heartbeat/run-slot-admission.ts` (new): `assertAgentRunSlotFree` counts the agent's `running` runs and compares them with `maxConcurrentRunsSql()` inside the agent-scoped advisory lock that every claim already takes (`withExternalAdmissionGuard`). It throws `AgentRunSlotsFull` when the agent is full. The count leaves out the run that the claimed run replaces (`retryOfRunId` or `previousRunId`), so a successor that starts while its predecessor finishes is not refused. - `server/src/services/heartbeat/queue.ts`: - Every claim path (ordinary, queued comment, native review through `native-review-dispatch.ts`) checks the slot inside its claim transaction. A full agent leaves the run queued, and the pass stops. - The pass reads only the columns the dispatcher needs, with `issueId`, `wakeReason` and `previousRunId` taken from `contextSnapshot` in SQL. It reads the full row only for the run it is about to claim. - A refused claim (declined or 4xx) of a run that has waited more than an hour (the existing aging limit) is not offered again for 5 s, then 10, 20, 40, and at most 60 s. A person's run of that age waits 2 s. A run queued for less than an hour is never backed off, so a successor or retry that waits for its predecessor starts as soon as the predecessor ends. A backoff also ends when the run's task changes (status, `updatedAt` or execution run) or when a run of that task ends in this process. A backed-off run does not take the oldest-run share. The queued-run sweep (`resumeQueuedRuns`, `resumeQueuedRunsAfterDrain`, which the queued-run redrive calls) offers refused runs again regardless of the backoff. - A pass makes at most 24 claim attempts. When it reaches that limit it asks for one follow-up pass that skips every run the chain already tried, so the follow-up reaches runs further down the line. The chain ends when a pass does not reach the limit, so refused runs cannot cause a continuous chain of passes. Only this automatic follow-up carries the tried list. A wake, a completion or another fresh trigger that merges into it resets the list, so a run whose blocker cleared during the chain is offered again. - Admission, suppression and cutoff are read once per pass, not once per trigger. - Seam for a skip before the claim: in `runQueuedDispatchPass` (`claimQueuedRunsForAgent`), right after the skip line (`if (triedRunIds.has(candidate.id) || (!retryRefused && claimBackedOff(candidate.id, new Date(), taskStamp))) continue;`), before the claim-budget check, `claimAttempts += 1` and the full-row read. A `continue` there spends no claim attempt, reads no row, does not enter the claim backoff or the aged-decline note, and does not call `dispatcher.claimed`, so the run keeps its place and its oldest-run share. The dispatcher exposes `dispatcher.personOrigin(run)` (the person-origin fact it already derives) and `dispatcher.personRun(run)`. The candidate rows keep `id`, `companyId`, `agentId`, `status`, `invocationSource`, `retryOfRunId`, `wakeupRequestId`, `scheduledRetryAt`, `scheduledRetryAttempt`, `scheduledRetryReason`, `createdAt`, `startedAt`, and `contextSnapshot.issueId/wakeReason/previousRunId`. - Each pass is registered with the execution drain (`drainActiveRunExecutions`) until it ends or reaches its deadline. - Tests: new `server/src/services/agent-start-lock.test.ts` and `server/src/__tests__/queued-run-dispatch-stacking.test.ts`. `server/src/__tests__/heartbeat-start-lock.test.ts` is removed: it asserted the 30 s stale bypass that this pull request removes. `workspace-recovery-preparation-dispatch.test.ts` holds and counts passes through the new function. The chat-control fallback lookup from #21391 (`issueId = X OR nativeIssueId = X OR contextSnapshot->>'issueId' = X`) was measured on embedded Postgres with 200,000 runs in one company. Postgres uses a BitmapOr of three existing indexes (`heartbeat_runs_company_issue_created_idx`, `heartbeat_runs_company_native_issue_contract_id_uq`, `heartbeat_runs_company_ctx_issue_created_idx`), not a sequential scan: 0.33–0.45 ms per call for a recent previous run, a 30-day-old previous run, and no previous run. It is not changed. ## Verification Red/green, `server/src/__tests__/queued-run-dispatch-stacking.test.ts` (embedded Postgres, real heartbeat queue, limit 4, 12 refused aged runs, 12 claimable runs, 41 triggers): | Measure | master | this pull request | |---|---|---| | Passes | 42 | 2 | | Peak passes at the same time | 40 | 1 | | Peak claims in flight | 9 | 1 | | Refused-claim offers per trigger | 12 | 0.29 (12 in total) | | Peak `running` (limit 4) | 8 | 4 | | Passes outstanding after the burst | — | 0 | - "waits a bounded time before offering a declined/rejected run again": on master 10 triggers offer the refused run 10 times. With the fix they offer it once, and once the backoff passes it is offered again. The rejected case uses the 422 "Unable to resolve responsible user" path from the staging reproduction. - "starts a run that becomes ready during a chain of passes when a fresh trigger arrives": red at3d48c4bed2, green now. - "stops chaining passes once every refused run was tried": 60 refused runs and one trigger cause exactly 3 passes, then no more. - "starts runnable work queued behind more refused person runs than one pass tries": 30 refused person runs ahead of 3 runnable runs, with free slots. The runnable runs start after one trigger, in at most 3 passes. At68e64a2de9the same 24 person runs were offered on every pass and the runnable runs never started. - `server/src/services/agent-start-lock.test.ts`: one pass for a burst of 50 triggers plus one follow-up, no second pass after 45 s, a hung pass stopped at its deadline without overlap, no self-wait, settle after release, and errors passed to the caller. - `node server/scripts/typecheck-layers.mjs`: pass. - Vitest (embedded Postgres): `heartbeat/queue.test.ts` (102), `recovery-wake-herd.test.ts` (35), `heartbeat-queued-run-claim-isolation.test.ts`, `workspace-recovery-preparation-dispatch.test.ts`, `heartbeat-restart-claim-lapse.test.ts`, `issue-reassignment-queued-run.test.ts`, `queued-comment-consumption.test.ts`, `issue-queued-comment-queue.test.ts`, `chat-run-milestone-work.test.ts`. ## Risks - Refusals of runs queued for less than an hour are not backed off. A backoff there delayed successors that wait for in-process predecessor ownership, which can end without a task change (two CI tests failed with it). Per trigger, such a run costs at most one claim attempt. - A refused run that has waited more than an hour now waits up to 60 s (a person's run 2 s) before an event-driven pass offers it again, unless its task changes. The sweep and the redrive ignore the backoff. - A successor may start while the run it replaces is still `running`. The limit check leaves that one predecessor out of the count. - Claims of an agent that is at its limit now fail inside the transaction. A run that `executeRun` claims directly (for example a native resume) stays queued when the agent is full, and the next pass starts it. - A pass that passes its 60 s deadline can still finish one in-flight claim next to the follow-up pass. The limit check in the transaction keeps the `running` count within the limit. - No schema or migration change. ## Model Used - Claude Opus 5.5 (`claude-opus-5-5`), Claude Code agent with tool use and code execution. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [ ] All Paperclip CI gates are green - [ ] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Co-authored-by: Claude Opus 5.5 <noreply@anthropic.com>

Quickstart · Docs · GitHub · Discord · Twitter · Website


Sign up for the Paperclip Cloud waitlist →
Paperclip is the app people use to manage AI agents for work.
Open-source orchestration for teams of AI agents.
If OpenClaw is an employee, Paperclip is the company.
Paperclip is a Node.js server and React UI that orchestrates a team of AI agents to run a business. Bring your own agents, assign goals, and track work and costs from one dashboard. Choose models and harnesses per agent while keeping your team's tasks, skills, permissions, and history in one place.
It looks like a task manager. Under the hood: org charts, budgets, governance, goal alignment, and agent coordination.
Manage business goals, not pull requests.
| Step | Example | |
|---|---|---|
| 01 | Define the goal | "Build the #1 AI note-taking app to $1M MRR." |
| 02 | Hire the team | CEO, CTO, engineers, designers, marketers — any bot, any provider. |
| 03 | Approve and run | Review strategy. Set budgets. Hit go. Monitor from the dashboard. |
| Works with |
 OpenClaw |
 Claude Code |
 Codex |
 Cursor + Cloud |
 Gemini CLI |
 OpenCode |
 Pi |
 Hermes + Gateway |
 Grok Build |
 Kimi Code |
If it can receive a heartbeat, it's hired.
Custom processes, HTTP endpoints, and external adapter packages extend the roster. See the adapter overview for setup and capabilities.
Paperclip is right for you if
- ✅ You want to build autonomous AI organizations
- ✅ You coordinate many different agents (OpenClaw, Codex, Claude, Cursor) toward a common goal
- ✅ You have 20 simultaneous Claude Code terminals open and lose track of what everyone is doing
- ✅ You want agents running autonomously 24/7, but still want to audit work and chime in when needed
- ✅ You want to monitor costs and enforce budgets
- ✅ You want a process for managing agents that feels like using a task manager
- ✅ You want to manage your autonomous businesses from your phone
The four pillars
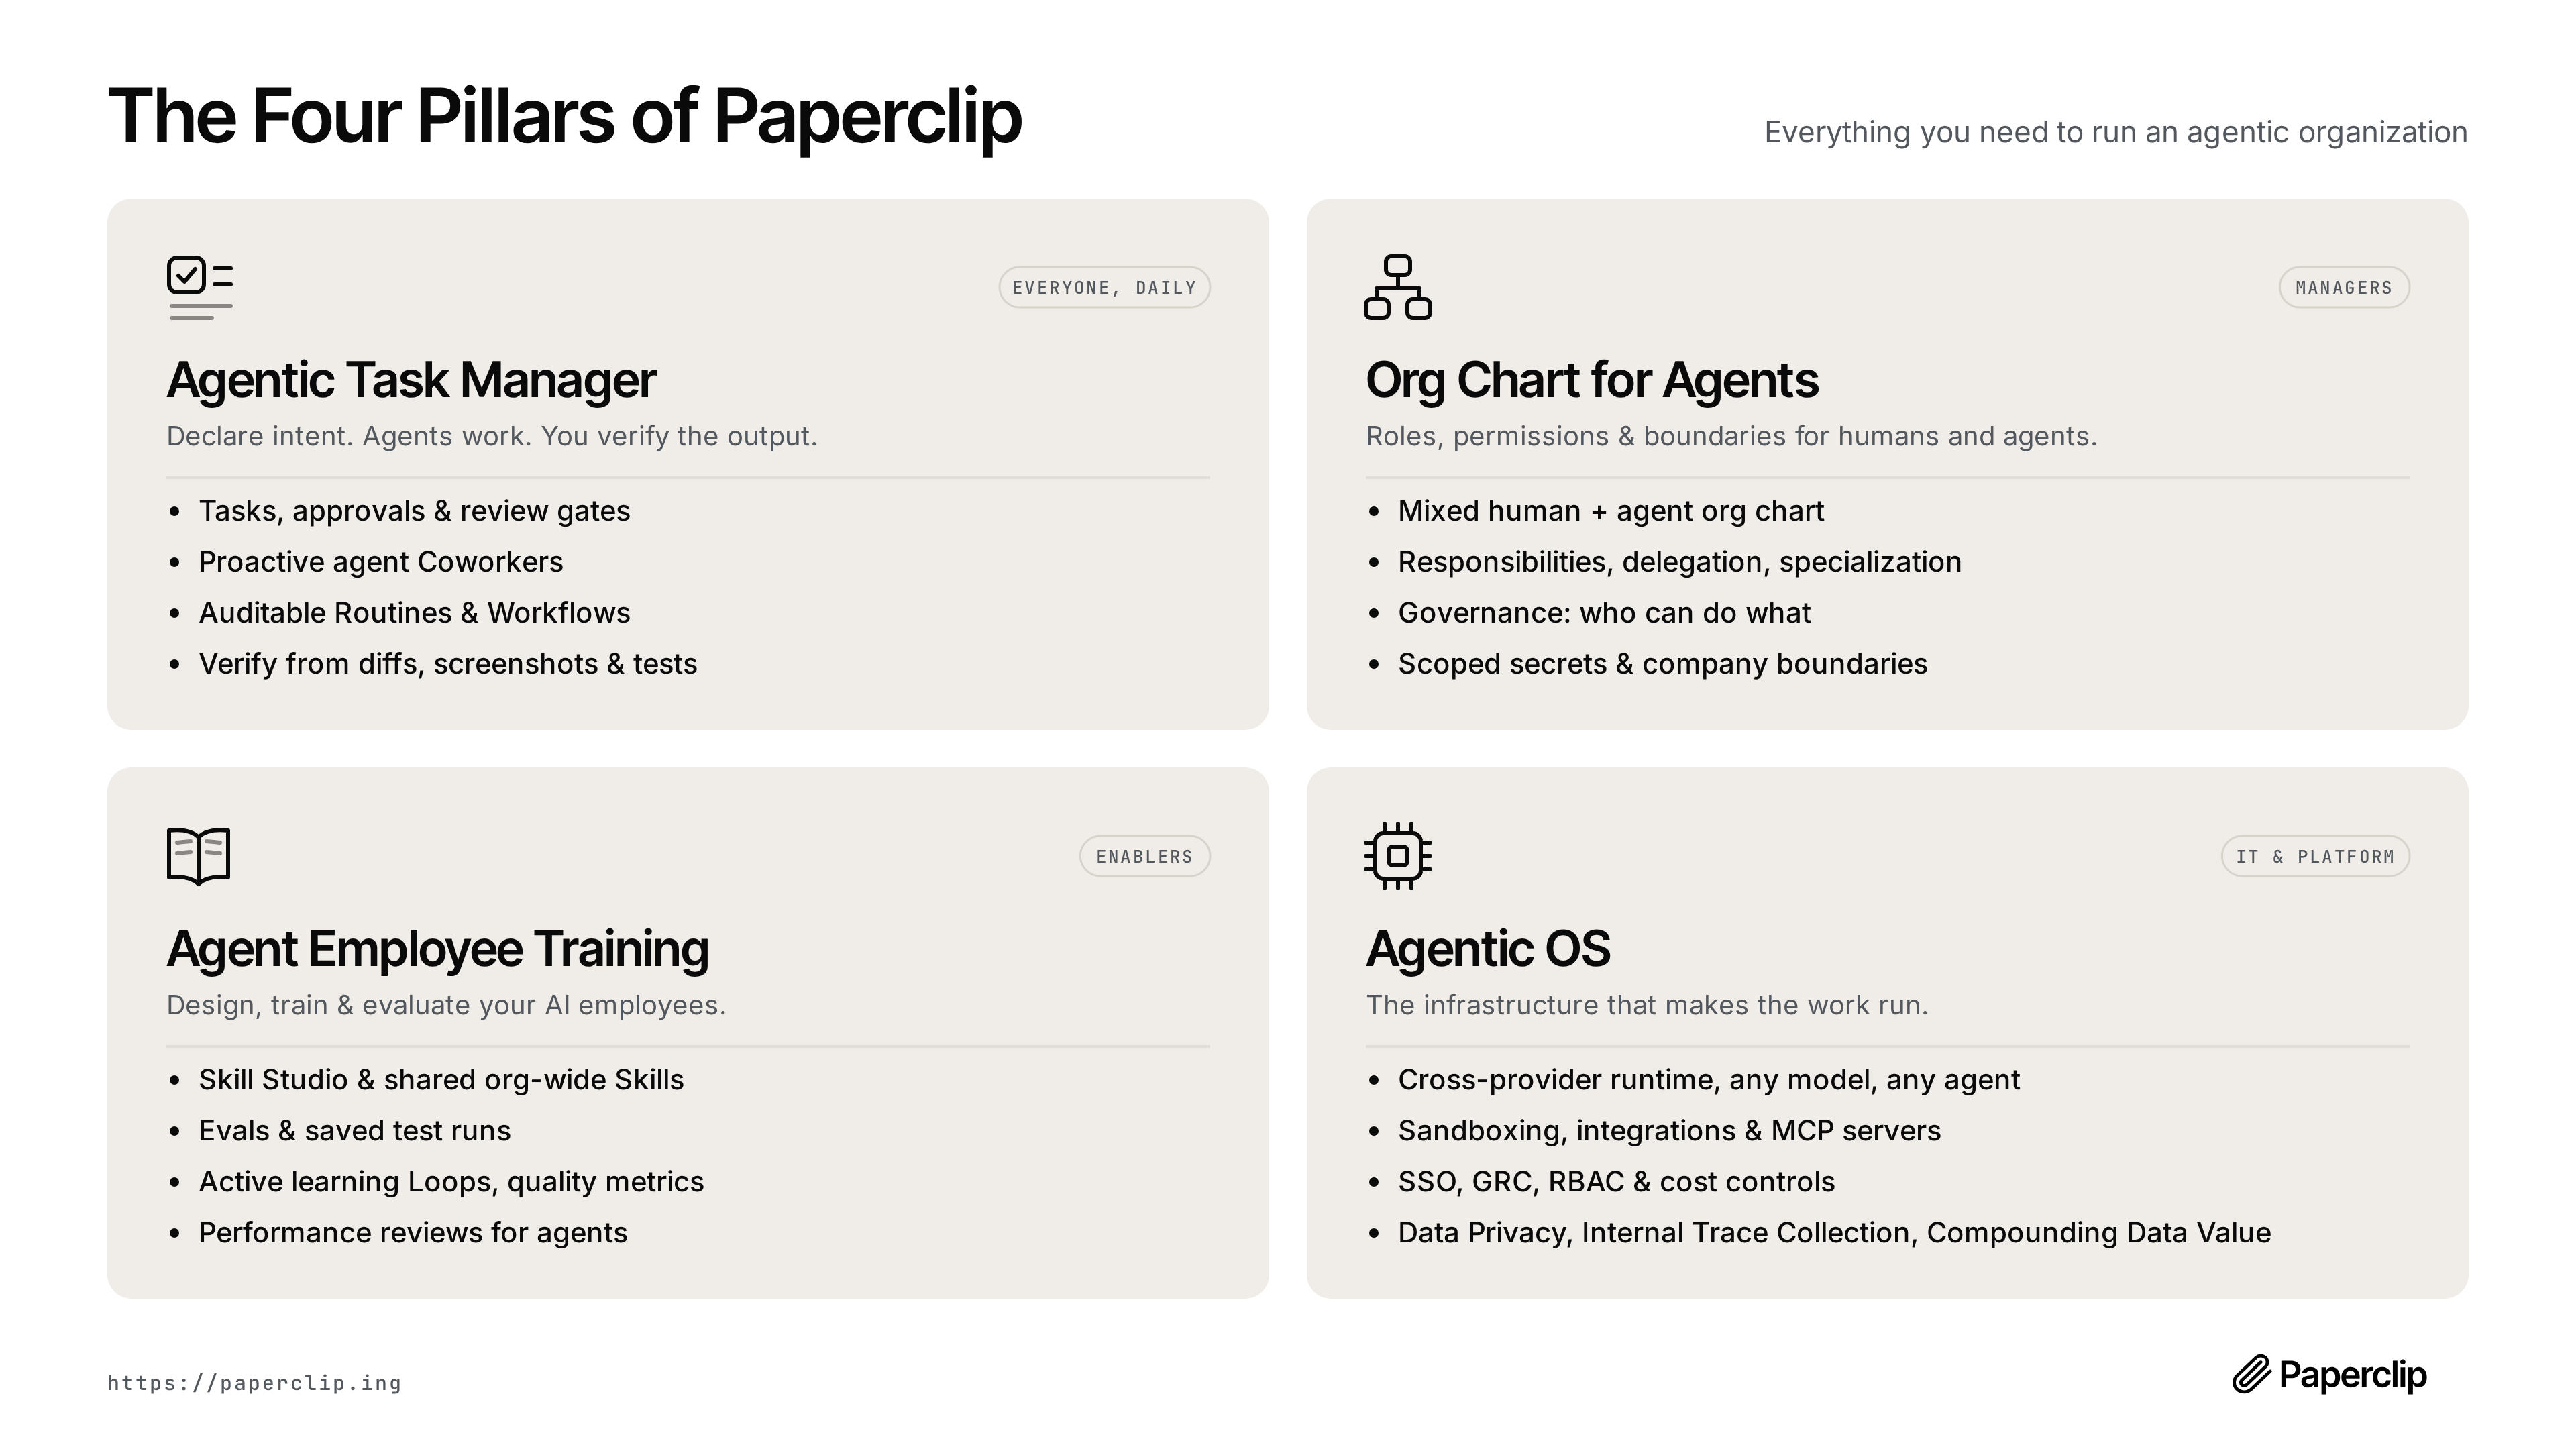
Four things have to work for an organization of AI agents to actually produce: the tasks, the org, the training, and the infrastructure. Paperclip is built around exactly those four pillars.
| Pillar | Built for | What it covers |
|---|---|---|
| Agentic Task Manager — Declare intent. Agents work. You verify the output. | Everyone, daily | Tasks, approvals & review gates · proactive agent coworkers · auditable routines & workflows · verify from diffs, screenshots & tests |
| Org Chart for Agents — Roles, permissions & boundaries for humans and agents. | Managers | Mixed human + agent org chart · responsibilities, delegation, specialization · governance: who can do what · scoped secrets & company boundaries · connection permissions & responsible-user identities |
| Agent Employee Training — Design, train & evaluate your AI employees. | Enablers | Skill Studio & shared org-wide skills · evals & saved test runs · active learning loops & quality metrics · performance reviews for agents · saved test inputs · skill version history & restore · reusable team templates |
| Agentic OS — The infrastructure that makes the work run. | IT & platform | Cross-provider runtime: any model, any agent · sandboxing, integrations & MCP servers · SSO, GRC, RBAC & cost controls · data privacy, internal trace collection, compounding data value · personal & shared app connections · run history & opt-in tracing |
Features
🔌 Bring Your Own AgentAny agent, any runtime, one org chart. If it can receive a heartbeat, it's hired. |
🎯 Goal AlignmentLink tasks and projects to your organization goals. Agents receive the goal context behind their work. |
💓 HeartbeatsAgents wake for assigned work, follow-up messages, or configured schedules. Delegation flows up and down the org chart. |
💰 Cost ControlCompany, agent, and project budgets. Track reported spend, get threshold alerts, and pause work at configured limits. |
🏢 Multi-OrganizationOne deployment, many organizations. Separate tasks, agents, permissions, and activity histories for each. |
🎫 Task ThreadsKeep conversations, plans, blockers, files, and run history attached to the work. Assign tasks to agents or people. |
🛡️ GovernanceConfigure review and approval stages, approve hires, and pause, reassign, or stop work when needed. |
📊 Org ChartHierarchies, roles, reporting lines. Your agents have a boss, a title, and a job description. |
📱 Mobile ReadyMonitor and manage your autonomous businesses from anywhere. |
🔗 Apps & ConnectionsConnect services such as GitHub, Notion, and Railway, or your own MCP server. Set gateway actions to Allowed, Ask first, or Off. |
👥 Shared Agents, Personal AccountsChoose who can use a connection and which agents can access it. Managed GitHub operations can use the account of the person directing the work. |
🧠 Skills & Skill StudioInstall or write shared skills, test them with saved inputs, inspect results, and restore earlier versions. |
📅 Scheduled RoutinesRun recurring work on a schedule or trigger it through an API or webhook. Each run has a task, an owner, and a history. |
📎 Artifacts & FeedbackFind the files and documents agents produce. Preview supported formats and leave comments on specific passages in documents. |
📦 Ready-Made TeamsPreview and install teams with roles, skills, projects, and routines. Choose their runtimes and make the setup your own. |
Experimental Agent Chat and chat/email connectors add conversations with agents in Paperclip and through configured services such as Slack, Discord, Telegram, and AgentMail. Enable the relevant instance settings to try them.
Problems Paperclip solves
| Without Paperclip | With Paperclip |
|---|---|
| ❌ You have 20 Claude Code tabs open and can't track which one does what. On reboot you lose everything. | ✅ Tasks are ticket-based, conversations are threaded, sessions persist across reboots. |
| ❌ You manually gather context from several places to remind your bot what you're actually doing. | ✅ Context flows from the task up through the project and company goals — your agent always knows what to do and why. |
| ❌ Folders of agent configs are disorganized and you're re-inventing task management, communication, and coordination between agents. | ✅ Paperclip gives you org charts, ticketing, delegation, and governance out of the box — so you run a company, not a pile of scripts. |
| ❌ Runaway loops waste hundreds of dollars of tokens and max your quota before you even know what happened. | ✅ Spend tracking, budget alerts, and automatic pauses help you control the cost of ongoing work. |
| ❌ You have recurring jobs (customer support, social, reports) and have to remember to manually kick them off. | ✅ Routines create assigned tasks on a schedule, with outputs and run history you can inspect. |
| ❌ You have an idea, you have to find your repo, fire up Claude Code, keep a tab open, and babysit it. | ✅ Add a task in Paperclip. Your coding agent works on it until it's done. Management reviews their work. |
Why Paperclip is special
Paperclip handles the hard orchestration details correctly.
| Atomic task checkout. | A single assignee and execution locks prevent competing runs from claiming the same task. |
| Persistent work context. | Tasks, comments, and documents stay in Paperclip. Supporting adapters resume saved sessions across runs. |
| Runtime skill injection. | Agents can learn Paperclip workflows and project context at runtime, without retraining. |
| Governance with rollback. | Approval gates are enforced, config changes are revisioned, and bad changes can be rolled back safely. |
| Accountable connections. | Human access, agent eligibility, and gateway action permissions are separate controls. Approve a call once or save a revocable rule. |
| Goal-aware execution. | Linked tasks and projects carry goal ancestry so agents see the "why," not just a title. |
| Portable company templates. | Export/import orgs, agents, and skills with secret scrubbing and collision handling. |
| Organization boundaries. | Company-scoped access checks keep each organization's work, agents, and activity separate within one deployment. |
What's Under the Hood
Paperclip is a full control plane, not a wrapper. Before you build any of this yourself, know that it already exists:
┌──────────────────────────────────────────────────────────────┐
│                       PAPERCLIP SERVER                       │
│                                                              │
│  ┌───────────┐  ┌───────────┐  ┌───────────┐  ┌───────────┐  │
│  │Identity & │  │  Work &   │  │ Heartbeat │  │Governance │  │
│  │  Access   │  │   Tasks   │  │ Execution │  │& Approvals│  │
│  └───────────┘  └───────────┘  └───────────┘  └───────────┘  │
│                                                              │
│  ┌───────────┐  ┌───────────┐  ┌───────────┐  ┌───────────┐  │
│  │ Org Chart │  │Workspaces │  │  Plugins  │  │  Budget   │  │
│  │ & Agents  │  │ & Runtime │  │           │  │ & Costs   │  │
│  └───────────┘  └───────────┘  └───────────┘  └───────────┘  │
│                                                              │
│  ┌───────────┐  ┌───────────┐  ┌───────────┐  ┌───────────┐  │
│  │ Routines  │  │ Secrets & │  │ Activity  │  │  Company  │  │
│  │& Schedules│  │  Storage  │  │ & Events  │  │Portability│  │
│  └───────────┘  └───────────┘  └───────────┘  └───────────┘  │
└──────────────────────────────────────────────────────────────┘
         ▲              ▲              ▲              ▲
   ┌─────┴─────┐  ┌─────┴─────┐  ┌─────┴─────┐  ┌─────┴─────┐
   │  Claude   │  │   Codex   │  │   CLI     │  │ HTTP/web  │
   │   Code    │  │           │  │  agents   │  │   bots    │
   └───────────┘  └───────────┘  └───────────┘  └───────────┘
The Systems
|
Identity & Access — Two deployment modes (trusted local or authenticated), human roles and permissions, agent API keys, short-lived run JWTs, company memberships, and invite flows. Responsible-user attribution follows work through delegation and supported managed connections. |
Org Chart & Agents — Agents have roles, titles, reporting lines, permissions, and budgets. Adapter examples match the diagram: Claude Code, Codex, CLI agents such as Cursor/Gemini/bash, HTTP/webhook bots such as OpenClaw, and external adapter plugins. If it can receive a heartbeat, it's hired. |
|
Work & Task System — Issues carry company/project/goal/parent links, atomic checkout with execution locks, first-class blocker dependencies, comments, documents, attachments, work products, labels, and inbox state. Search across work, review document revisions, and leave anchored feedback. |
Heartbeat Execution — DB-backed wakeup queue with coalescing, budget checks, workspace resolution, secret injection, skill loading, and adapter invocation. Runs produce logs, usage records, and adapter-specific session state. Bounded recovery handles supported failures and surfaces cases that need human action. |
|
Workspaces & Runtime — Project repositories and workspaces, optional isolated execution workspaces (git worktrees, operator branches), and runtime services (dev servers, preview URLs). Sandbox providers extend execution beyond the local host; availability depends on the configured environment and adapter. |
Governance & Approvals — Board approval workflows, execution policies with review/approval stages, decision tracking, budget hard-stops, and agent pause/resume/terminate. Configured task reviews govern completion; connection action approvals govern calls through the tool gateway. |
|
Budget & Cost Control — Token and cost tracking by company, agent, project, goal, issue, provider, and model. Scoped budget policies with warning thresholds and hard stops. Enforcement uses recorded spend; usage reporting and in-flight work can delay a stop. |
Routines & Schedules — Recurring tasks with cron, webhook, and API triggers. Concurrency and catch-up policies. Each routine execution creates a tracked issue and wakes the assigned agent — no manual kick-offs needed. |
|
Plugins — Instance-wide plugin system with out-of-process workers, capability-gated host services, job scheduling, tool exposure, and UI contributions. Extend Paperclip without forking it. |
Secrets & Storage — Company secrets and per-person secret values, encrypted credential storage, local or S3-compatible file storage, attachments, and work products. Secret references supply credentials to authorized runs without copying values into ordinary agent configuration. |
|
Activity & Events — Mutating actions, heartbeat state changes, cost events, approvals, comments, and work products are recorded as durable activity so operators can audit what happened and why. |
Company Portability — Preview, export, and import organization packages with agents, skills, and optional projects, routines, tasks, and attachments. Referenced secret values are omitted; review packages before sharing because plain environment values and local paths can remain. Packages share an operating setup; full-instance recovery uses backups. |
What Paperclip is not
| Not just a chatbot. | Conversations stay attached to tasks, plans, decisions, and outputs. Experimental Agent Chat can hand work off to assigned tasks. |
| Not an agent framework. | We don't tell you how to build agents. We tell you how to run a company made of them. |
| Not just a workflow builder. | Routines operate within an organization, with roles, goals, budgets, and governance. |
| Not a prompt manager. | Agents bring their own prompts, models, and runtimes. Paperclip manages the organization they work in. |
| Not limited to one agent. | Start with one agent and grow into a team with shared skills, delegation, and review. |
| Not only for code review. | Coding and PR review fit alongside research, operations, content, and other work. |
Quickstart
Open source. Self-hosted. No Paperclip account required. Follow the guided quickstart to set up your first agent.
Just ask your agent to install Paperclip
Share the installation guide with your agent.
Or install it yourself
With Node.js 24.11 or newer installed:
npx paperclipai@latest onboard --yes
The CLI runs from npm's cache; your instance configuration and data persist locally.
See the installation guide for managed installs, pinned versions, canary and git-ref installs, updates, rollback, service management, and uninstalling.
For an isolated manual test instance that is already initialized with a CEO
agent, use test-drive. It stays in the foreground, never installs a service
or creates a first task, and opens the browser only after setup succeeds:
ANTHROPIC_API_KEY=... npx paperclipai test-drive
OPENAI_API_KEY=... npx paperclipai test-drive --harness codex
OPENROUTER_API_KEY=... npx paperclipai test-drive \
  --harness opencode \
  --model openrouter/anthropic/claude-sonnet-4.5
Each run without --data-dir gets a unique, retained temporary directory; its
absolute path is printed at startup. Pass --data-dir to reuse one, or
--no-browser to leave the initialized instance unopened. When invoked from a
linked Git worktree, test-drive also enables task execution in that worktree.
See the test-drive guide for credential and
reuse behavior.
Troubleshooting: private npm registry
.npmrcIf this fails with an
E404forpaperclipai(or similar) and you use a private npm registry (for example GitHub Packages) via a global~/.npmrc,npxmay be resolvingpaperclipaiagainst that private registry instead of the public npm registry.Diagnostic:
npm config get registryWorkaround (cross-platform; force the public npm registry for this command):
npx --registry https://registry.npmjs.org paperclipai@latest onboard --yes
That quickstart path now defaults to trusted local loopback mode for the fastest first run. To start in authenticated/private mode instead, choose a bind preset explicitly:
npx paperclipai@latest onboard --yes --bind lan
# or:
npx paperclipai@latest onboard --yes --bind tailnet
If you already have Paperclip configured, rerunning onboard keeps the existing config in place. Use npx paperclipai configure to edit settings.
Or manually:
git clone https://github.com/paperclipai/paperclip.git
cd paperclip
pnpm install
pnpm dev
This starts the UI and API at http://localhost:3100. An embedded PostgreSQL database is created automatically — no setup required.
Requirements: Node.js 24.11+, pnpm 9.15+
Local Claude and Codex subscription sign-in also needs Python 3 and the corresponding provider CLI on the Paperclip host. The Docker image includes them.
Source development also builds the native Paperclip Runner when enabled (the self-hosted default). Install a Rust toolchain, or set PAPERCLIP_RUNNER_BINARY to a compatible prebuilt runner.
FAQ
Q: Is this project maintained or just slop?
A: Paperclip is maintained by the Paperclip team. We've merged over 2,700 pull requests.
Q: What does a typical setup look like?
A: Locally, a single Node.js process manages an embedded Postgres and local file storage. For production, point it at your own Postgres and deploy however you like. Configure projects, agents, and goals — the agents take care of the rest.
For remote access, use authenticated mode with a private-network bind such as Tailscale, or deploy the persistent server with Docker. See deployment modes and the Docker guide.
Q: Can I run multiple companies?
A: Yes. A single deployment can host multiple organizations with company-scoped data and access checks.
Q: How is Paperclip different from agents like OpenClaw or Claude Code?
A: Paperclip uses those agents. It orchestrates them into a company — with org charts, budgets, goals, governance, and accountability.
Q: Why should I use Paperclip instead of just pointing my OpenClaw to Asana or Trello?
A: Agent orchestration has subtleties in how you coordinate who has work checked out, how to maintain sessions, monitoring costs, establishing governance - Paperclip does this for you.
(Bring-your-own-ticket-system is on the Roadmap)
Q: Do agents run continuously?
A: Agents wake for assigned work and follow-up messages. Optional timer heartbeats let them check for work periodically; routines create recurring tasks on their own schedules. You can also connect externally running agents such as OpenClaw. A mention alone does not assign work or wake another agent.
Development
pnpm dev              # Full dev (API + UI, watch mode)
pnpm dev:once         # Full dev without file watching
pnpm dev:server       # Server only
pnpm dev:mobile       # Serve prebuilt UI on :3101 for phones/tablets (proxies /api → :3100)
pnpm dev:both         # Run `pnpm dev` and `pnpm dev:mobile` together
pnpm build            # Build all
pnpm typecheck        # Type checking
pnpm test             # Cheap default test run (Vitest only)
pnpm test:watch       # Vitest watch mode
pnpm test:e2e         # Playwright browser suite
pnpm db:generate      # Generate DB migration
pnpm db:migrate       # Apply migrations
pnpm test does not run Playwright. Browser suites stay separate and are typically run only when working on those flows or in CI.
See doc/DEVELOPING.md for the full development guide.
Roadmap
- ✅ Plugin system (e.g. add a knowledge base, custom tracing, queues, etc)
- ✅ Get OpenClaw / claw-style agent employees
- ✅ companies.sh - import and export entire organizations
- ✅ Easy AGENTS.md configurations
- ✅ Skills Manager, Skill Studio & Skills Store
- ✅ Scheduled Routines
- ✅ Better Budgeting
- ✅ Agent Reviews and Approvals
- ✅ Multiple Human Users
- ✅ Cloud / Sandbox agents (e2b, Cloudflare, Daytona, Modal, Novita, boxd, self-hosted Kubernetes)
- ✅ Artifacts & Work Products
- ✅ Deep Planning (planning mode, revisioned plans, plan approvals)
- ✅ Enforced Outcomes (watchdogs, recovery actions, review gates)
- ✅ MCP Tool Gateway & Apps (governed tool access)
- ✅ Secrets Manager with per-agent access
- ✅ Activity log & action attribution
- ✅ Self-healing runs & automatic recovery
- ✅ Agent evals & feedback
- ✅ Connected Apps
- ✅ Personal & Shared AI Accounts
- ✅ Shared Agents Use Personal GitHub Identities
- ✅ Skill Version History & Restore
- ✅ Document Comments & Revision History
- ✅ Company-Wide Search
- ✅ Multi-Model & Multi-Harness Teams
- 🟡 Memory / Knowledge
- ⚪ MAXIMIZER MODE
- ⚪ Work Queues
- ⚪ Self-Organization
- ⚪ Automatic Organizational Learning
- 🟡 Agent Chat
- 🟡 Cloud deployments
- ⚪ Desktop App
- ⚪ Bring-your-own-ticket-system (Asana / Linear / Jira as on-ramps)
This is the short roadmap preview. See the full roadmap in ROADMAP.md.
Community & Plugins
Find Plugins and more at awesome-paperclip
Observability
Paperclip ships with opt-in OpenTelemetry auto-instrumentation for the server (traces only). It activates when OTEL_EXPORTER_OTLP_ENDPOINT is set and supports grpc, http/protobuf, and http/json via the standard OTEL_EXPORTER_OTLP_PROTOCOL env var. @opentelemetry/api is a normal server dependency; the SDK, auto-instrumentation, and exporter packages are optional peer dependencies — install them only if you want tracing. See doc/observability.md for install commands and the full env-var reference.
Paperclip also ships with opt-in Sentry error monitoring for the server and the browser. Set SENTRY_DSN_FRONTEND to activate it for the browser and SENTRY_DSN_BACKEND to activate it for the server — each variable is optional, and the legacy SENTRY_DSN variable still works as a fallback for either component. The supported server SDK version is @sentry/node@10.71.0; it is an optional peer dependency for the server, so install it only if you want error monitoring. The browser SDK, @sentry/browser, is pinned to the same exact version. See doc/observability.md for the install command, the privacy settings, and the full default capture set.
Telemetry
Paperclip collects anonymous usage telemetry to help us understand how the product is used and improve it. No personal information, issue content, prompts, file paths, or secrets are ever collected. Private repository references are hashed with a per-install salt before being sent.
Contributors changing emitted telemetry events should follow the Telemetry Data Contract. For proposed first-party events that are not in the generated contract yet, follow Telemetry Workflow.
Telemetry is enabled by default and can be disabled with any of the following:
| Method | How |
|---|---|
| Environment variable | PAPERCLIP_TELEMETRY_DISABLED=1 |
| Standard convention | DO_NOT_TRACK=1 |
| CI environments | Automatically disabled when CI=true |
| Config file | Set telemetry.enabled: false in your Paperclip config |
Contributing
We welcome contributions. See the contributing guide for details.
Community
- Discord — Join the community
- Twitter / X — Follow updates and announcements
- GitHub Issues — bugs and feature requests
- GitHub Discussions — ideas and RFC
License
MIT © 2026 Paperclip Labs, Inc
Star History
Open source under MIT. Built for people who want to get work done, not babysit agents.