mirror of
https://github.com/paperclipai/paperclip.git
synced 2026-10-15 12:28:10 +02:00
 233c12f029
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work > - Local agent adapters (`claude_local`, `gemini_local`, `grok_local`, …) are the integration surface that lets Paperclip run coding CLIs on the host machine > - The Kimi Code CLI (`kimi`, Moonshot AI) has a documented non-interactive mode, `kimi -p --output-format stream-json` with session resume via `kimi -r`, but Paperclip has no built-in adapter for it > - So Kimi users (especially Kimi membership / OAuth subscribers) cannot onboard their CLI to Paperclip agent teams > - This pull request adds a complete built-in `kimi_local` adapter (both execution engines, session management, instructions + skills delivery, thinking-effort control, environment test, UI and CLI modules, docs) following the established `gemini_local`/`grok_local` package pattern > - Kimi Code ships an ACP server (`kimi acp`), so the adapter runs on Paperclip's shared acpx engine by default (streaming transcript with live tool status, like `claude_local`/`gemini_local`) and falls back to a headless CLI lane (`kimi -p --output-format stream-json`) when ACP prerequisites are unavailable > - The benefit is that Kimi Code becomes a first-class Paperclip agent lane: selectable in the UI, resumable across heartbeats, with the same operating context (instruction bundle, skills, effort) and streaming transcript the other local adapters get ## Linked Issues or Issue Description - Supersedes #9880 (same branch; expanded from the CLI-only lane into a complete adapter with the default ACP engine lane, control-plane skill install, and live transcript wiring) - Refs #9879 (adapter request for Kimi Code CLI, filed with this PR) - Refs #163 (original Kimi support request) Duplicate/related prior PRs, per the dedup search (both appear stale: no updates or maintainer review since May 2026, and both target an older Kimi CLI interface; calling them out for reviewer context per CONTRIBUTING.md): - Refs #6276 (`feat: add kimi-local adapter`): targets an older array-based content format (`{type: think}`/`{type: text}` blocks), not the current documented stream-json schema - Refs #5202 (`feat(adapter): add Kimi CLI local adapter with Wire protocol support`): builds on a `--wire` JSON-RPC interface that current Kimi Code CLI (0.27.0) no longer documents; the current documented headless interface is `-p --output-format stream-json` This PR is a fresh implementation against current master and the currently documented/verified Kimi CLI behavior (see Verification). Happy to fold in anything useful from the earlier attempts if a reviewer prefers. ## What Changed - **New adapter package** `packages/adapters/kimi-local` (`@paperclipai/adapter-kimi-local`), modeled on `gemini-local`/`grok-local`: - `src/server/execute.ts`: spawns `kimi -p <prompt> --output-format stream-json` (argv array, no shell), `-m <model>` only when configured, `-r <sessionId>` when the stored session cwd matches the run cwd, automatic fresh-session retry on unrecoverable-session errors, headless-safe env (`CI=1`, `NO_COLOR=1`, `KIMI_CODE_NO_AUTO_UPDATE=1`, `TERM=dumb`; user-configured values win), full remote (ssh/sandbox) execution lane with runtime install via `@moonshot-ai/kimi-code` - **Instruction bundle delivery**: the prompt path directive now names the sibling instruction files (`./HEARTBEAT.md`, `./SOUL.md`, `./TOOLS.md`) alongside the prepended entry file, and local runs pass `--add-dir <instructions-dir>` so Kimi can actually open them (matching `claude_local`). Without this, only the entry file reached Kimi and agents improvised the operating workflow that `HEARTBEAT.md` documents - **Thinking effort**: a configured `effort` is forwarded as the `KIMI_MODEL_THINKING_EFFORT` operational override (Kimi has no per-invocation effort flag). It is only sent for models that advertise `support_efforts` (currently `kimi-code/k3`) to avoid provider rejections, and `medium` maps to `high` since Kimi has no medium tier (`low`/`high`/`max` pass through) - **Skills delivery**: desired Paperclip skills are delivered via Kimi's `--skills-dir` flag from a dedicated per-run directory (a local snapshot, or the synced snapshot on remote targets), so skills load reliably and in isolation. Paperclip never overwrites the shared `$KIMI_CODE_HOME/skills` home, so skills installed by the operator or other agents are left intact. `--skills-dir` is only passed when at least one skill is desired, so unconfigured agents keep Kimi's default skill discovery - **Live run status**: the adapter now forwards each streamed stream-json line to `onEvent` (assistant `content` as an assistant snippet, `tool_calls` as tool-name events), which drives the issue-thread activity indicator (`currentToolName` / `lastAssistantSnippet` / `lastEventAt`). Previously the adapter only wrote the raw run log, so the issue thread showed a stale "no output for N s" line with no tool or reasoning context while Kimi worked. Tool results are omitted so the last meaningful "Using X" / snippet is not overwritten by a generic label - `src/server/parse.ts`: parses the verified Kimi stream-json event shapes (`assistant` text, `assistant.tool_calls` with JSON-string arguments, `tool` results, trailing `meta.session.resume_hint` for session-id capture) plus failure classifiers (`kimi_auth_required`, transient network, unrecoverable session). A signaled exit (null exit code, not a timeout) is now reported as a failure rather than coalesced to success, and the error message names the terminating signal - `src/server/skills.ts`: lists/syncs Paperclip skills for the adapter's skill-management surface - `src/server/test.ts`: environment test covering CLI resolution + `kimi --version`, cwd check, auth detection (OAuth credential dirs, keyed `[providers.*]` in config.toml, or the `KIMI_MODEL_NAME` + `KIMI_MODEL_API_KEY` env pair), and a live hello probe - `src/ui/` (stdout-line parser for transcripts, config builder) and `src/cli/` (stream event formatter) modules - Root metadata: three managed model aliases (`kimi-code/kimi-for-coding`, `kimi-code/kimi-for-coding-highspeed`, `kimi-code/k3`), effort-capable-model metadata (`EFFORT_CAPABLE_MODELS`, effort mapping helpers), `agentConfigurationDoc` - Tests: 101 tests across parse, execute (args building, resume gating, retry, auth error code, timeout, signaled-exit failure, effort forwarding/gating/mapping, `--add-dir` instructions directive, `--skills-dir` gating, `onEvent` runtime-event forwarding), ACP engine (engine resolution, acpx config build, node-version gate), ACP transcript delegation, environment test, UI parse/build-config - **ACP engine lane (default)** (`src/server/acp.ts` + shared `adapter-utils/acpx-engine`): Kimi Code ships an ACP server (`kimi acp`), so `kimi_local` now runs on Paperclip's shared acpx engine by default, matching `claude_local`/`codex_local`/`gemini_local`. The issue-thread transcript streams live (assistant text deltas, tool calls with a `pending`->`completed` status lifecycle) instead of the CLI lane's bursty complete-message output. Registered `kimi_local -> "kimi"` in `ACPX_ADAPTER_AGENT_IDS` and resolved the built-in agent command to `kimi acp`; `execute.ts` dispatches to the ACP executor first with an automatic CLI fallback when ACP prerequisites fail (`engine=acp` requires ACP, `engine=cli` pins the headless lane); `index.ts` falls back to the shared acpx session codec; the UI/CLI delegate `acpx.*` events to the shared acpx transcript parser and event formatter. The headless CLI lane (above) remains as the fallback - **Registration** (one entry each, mirroring existing adapters): server adapter registry + `BUILTIN_ADAPTER_TYPES`, `AGENT_ADAPTER_TYPES` (shared), UI adapter registry + display registry (`Kimi Code`, Moon icon) + capabilities defaults, CLI adapter registry, `Dockerfile` (package copy + `npm install --global @moonshot-ai/kimi-code@latest`), `vitest.config.ts` workspace, `scripts/release-package-manifest.json` - **Behavioral sets** mirroring `gemini_local` (Kimi resumes sessions the same way): `GIT_SENSITIVE_LOCAL_ADAPTER_TYPES`, `SESSIONED_LOCAL_ADAPTERS` (heartbeat + recovery), `REMOTE_MANAGED_ADAPTERS`, ssh/sandbox execution-target allow-lists, `ADAPTER_DEFAULT_RULES_BY_TYPE` (`timeoutSec: 0`, `graceSec: 15`), and `LEGACY_SESSIONED_ADAPTER_TYPES` + `ADAPTER_SESSION_MANAGEMENT` in adapter-utils - **UI touch-points**: New Agent default-model branch, AgentConfigForm command map (`kimi_local: "kimi"`) + model defaults + a Kimi-specific thinking-effort option list (`Low`/`High`/`Max`, reflecting Kimi's tiers rather than borrowing Claude's), OnboardingWizard (command map, model default, `kimi login` / `KIMI_MODEL_NAME + KIMI_MODEL_API_KEY` auth hints, manual-debug command line), InviteLanding enabled adapters - **Control-plane skill install** (`cli/src/commands/client/agent.ts`): `paperclipai agent local-cli` seeded the Paperclip control-plane skills into `~/.codex/skills` and `~/.claude/skills` so Codex/Claude agents auto-discover the API reference every run. Kimi had no equivalent target, so `kimi_local` agents began each session without the control-plane skill and rediscovered routes (e.g. the company-scoped `POST /api/companies/{companyId}/issues`) by trial and error. Added `~/.kimi-code/skills` (honoring `KIMI_CODE_HOME`) as a third install target for parity. Independent of the per-run `--skills-dir` delivery, which only applies to explicitly configured skills. - **Docs**: `docs/adapters/kimi-local.md` (prerequisites, auth options, config fields including `effort`, session resume, instruction bundle, skills delivery, control-plane skill install) + a row in `docs/adapters/overview.md` Out of scope (deliberately): model profiles, built-in agent `allowedAdapterTypes` additions. ## Verification\n\nCurrent-master rebase verification (OpenAI Codex, 2026-08-03): 13 focused files / 231 tests pass; adapter-utils, server, UI, CLI, and Kimi adapter typechecks pass; full repository build and UI token gates pass. The branch is conflict-free against master at head `1249df117c5e12e5771b9a570a6340866450619e`.\n\nAutomated (all from repo root, pnpm 9.15.4, Node 22): - `vitest run packages/adapters/kimi-local`: 89/89 pass (includes coverage for the instruction `--add-dir` directive, effort forwarding/gating/mapping, `--skills-dir` gating, the signaled-exit failure path, and `onEvent` runtime-event forwarding with cross-chunk line buffering) - `vitest run server/src/__tests__/adapter-registry.test.ts server/src/__tests__/adapter-routes.test.ts server/src/services/heartbeat-stop-metadata.test.ts ui/src/adapters/adapter-display-registry.test.ts`: 37/37 pass - `vitest run cli/src/__tests__/skills.test.ts`: 13/13 pass (the control-plane skill install target follows the existing Codex/Claude install path, whose symlink logic is unchanged) - `vitest run packages/shared`: 307/307 pass; `vitest run packages/adapter-utils`: pass except one pre-existing, unrelated failure (`mcp-isolation.integration.test.ts` requires Claude CLI ≥ 2.1.207; host has 2.1.185, fails identically on unmodified master) - `pnpm --filter @paperclipai/adapter-kimi-local typecheck|build`, plus typecheck of `server`, `ui`, `cli`, `adapter-utils`: all clean - `pnpm install --frozen-lockfile`: passes (the PR diff itself contains no lockfile changes, per repo policy; verified against a locally regenerated lockfile) - `node scripts/check-no-git-push.mjs` and `node scripts/check-forbidden-tokens.mjs`: pass - CI note: the `policy` job's release-bootstrap step is expected to stay red until a maintainer bootstraps the first npm publish of `@paperclipai/adapter-kimi-local`; see the CI Note for Maintainers comment. All other contributor-actionable checks are green. Manual end-to-end (real Kimi CLI 0.27.0, OAuth login, dev server on an isolated instance): 1. Server `GET /api/adapters` lists `kimi_local` as builtin with correct capability flags; models endpoint returns the three Kimi models 2. `POST .../adapters/kimi_local/test-environment`: all checks pass, including a live `kimi -p` hello probe 3. Created a `kimi_local` agent and invoked two heartbeats: run 1 spawned `kimi -p ... --output-format stream-json`, Kimi used its `Read` tool, produced the expected answer, and the session id was captured from the `session.resume_hint` meta event; run 2 resumed the **same** Kimi session (`sessionIdBefore == sessionIdAfter`) via `-r` 4. UI: adapter appears in the New Agent dropdown; selecting it shows the Kimi command placeholder, the three models, and the Kimi config fields; the run transcript renders Kimi tool calls via the adapter's stdout parser The instruction-bundle, thinking-effort, and `--skills-dir` changes landed after the manual run above. They are covered by the unit tests listed under Automated, and the Kimi CLI flags they rely on (`--add-dir`, `--skills-dir`, `KIMI_MODEL_THINKING_EFFORT`) were confirmed against the installed Kimi Code CLI 0.27.0 (`kimi --help`, config-file thinking-effort docs). Screenshots (assets branch on the fork, not part of the diff): 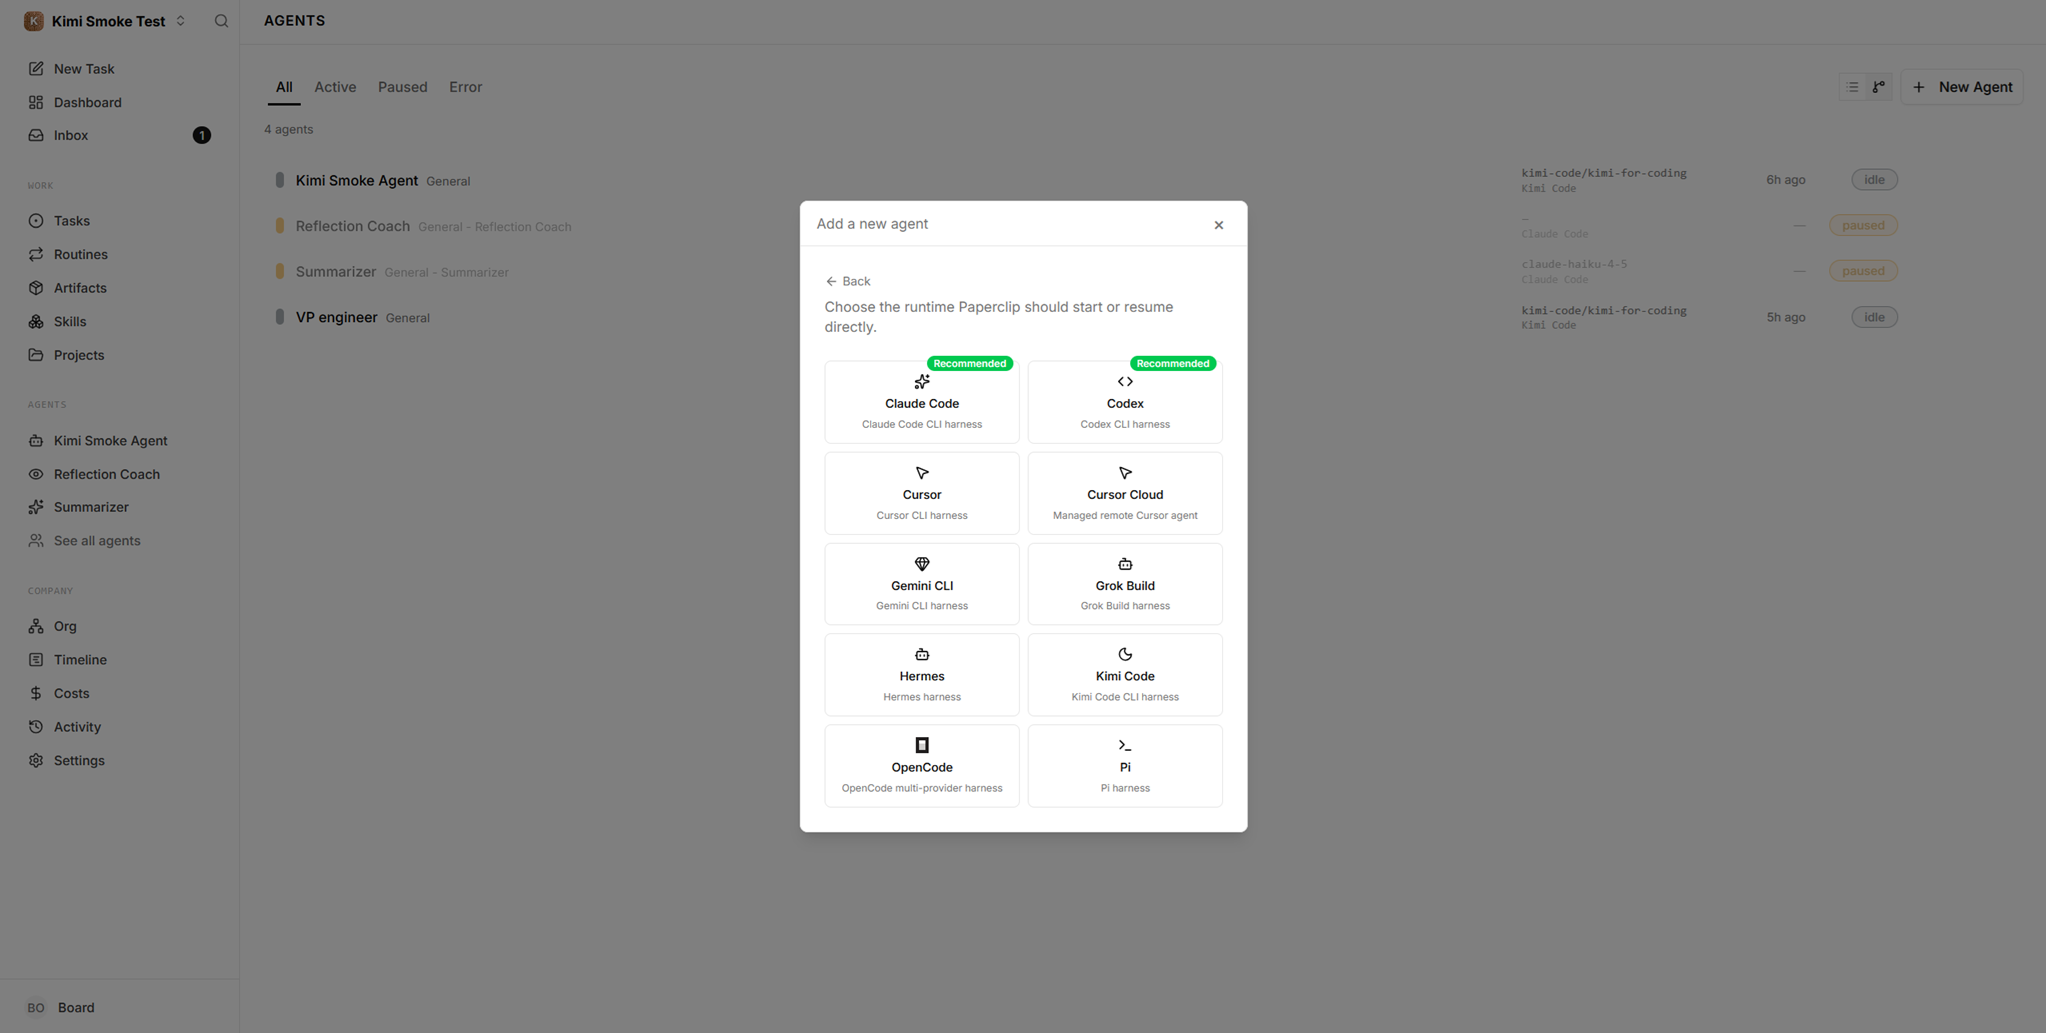 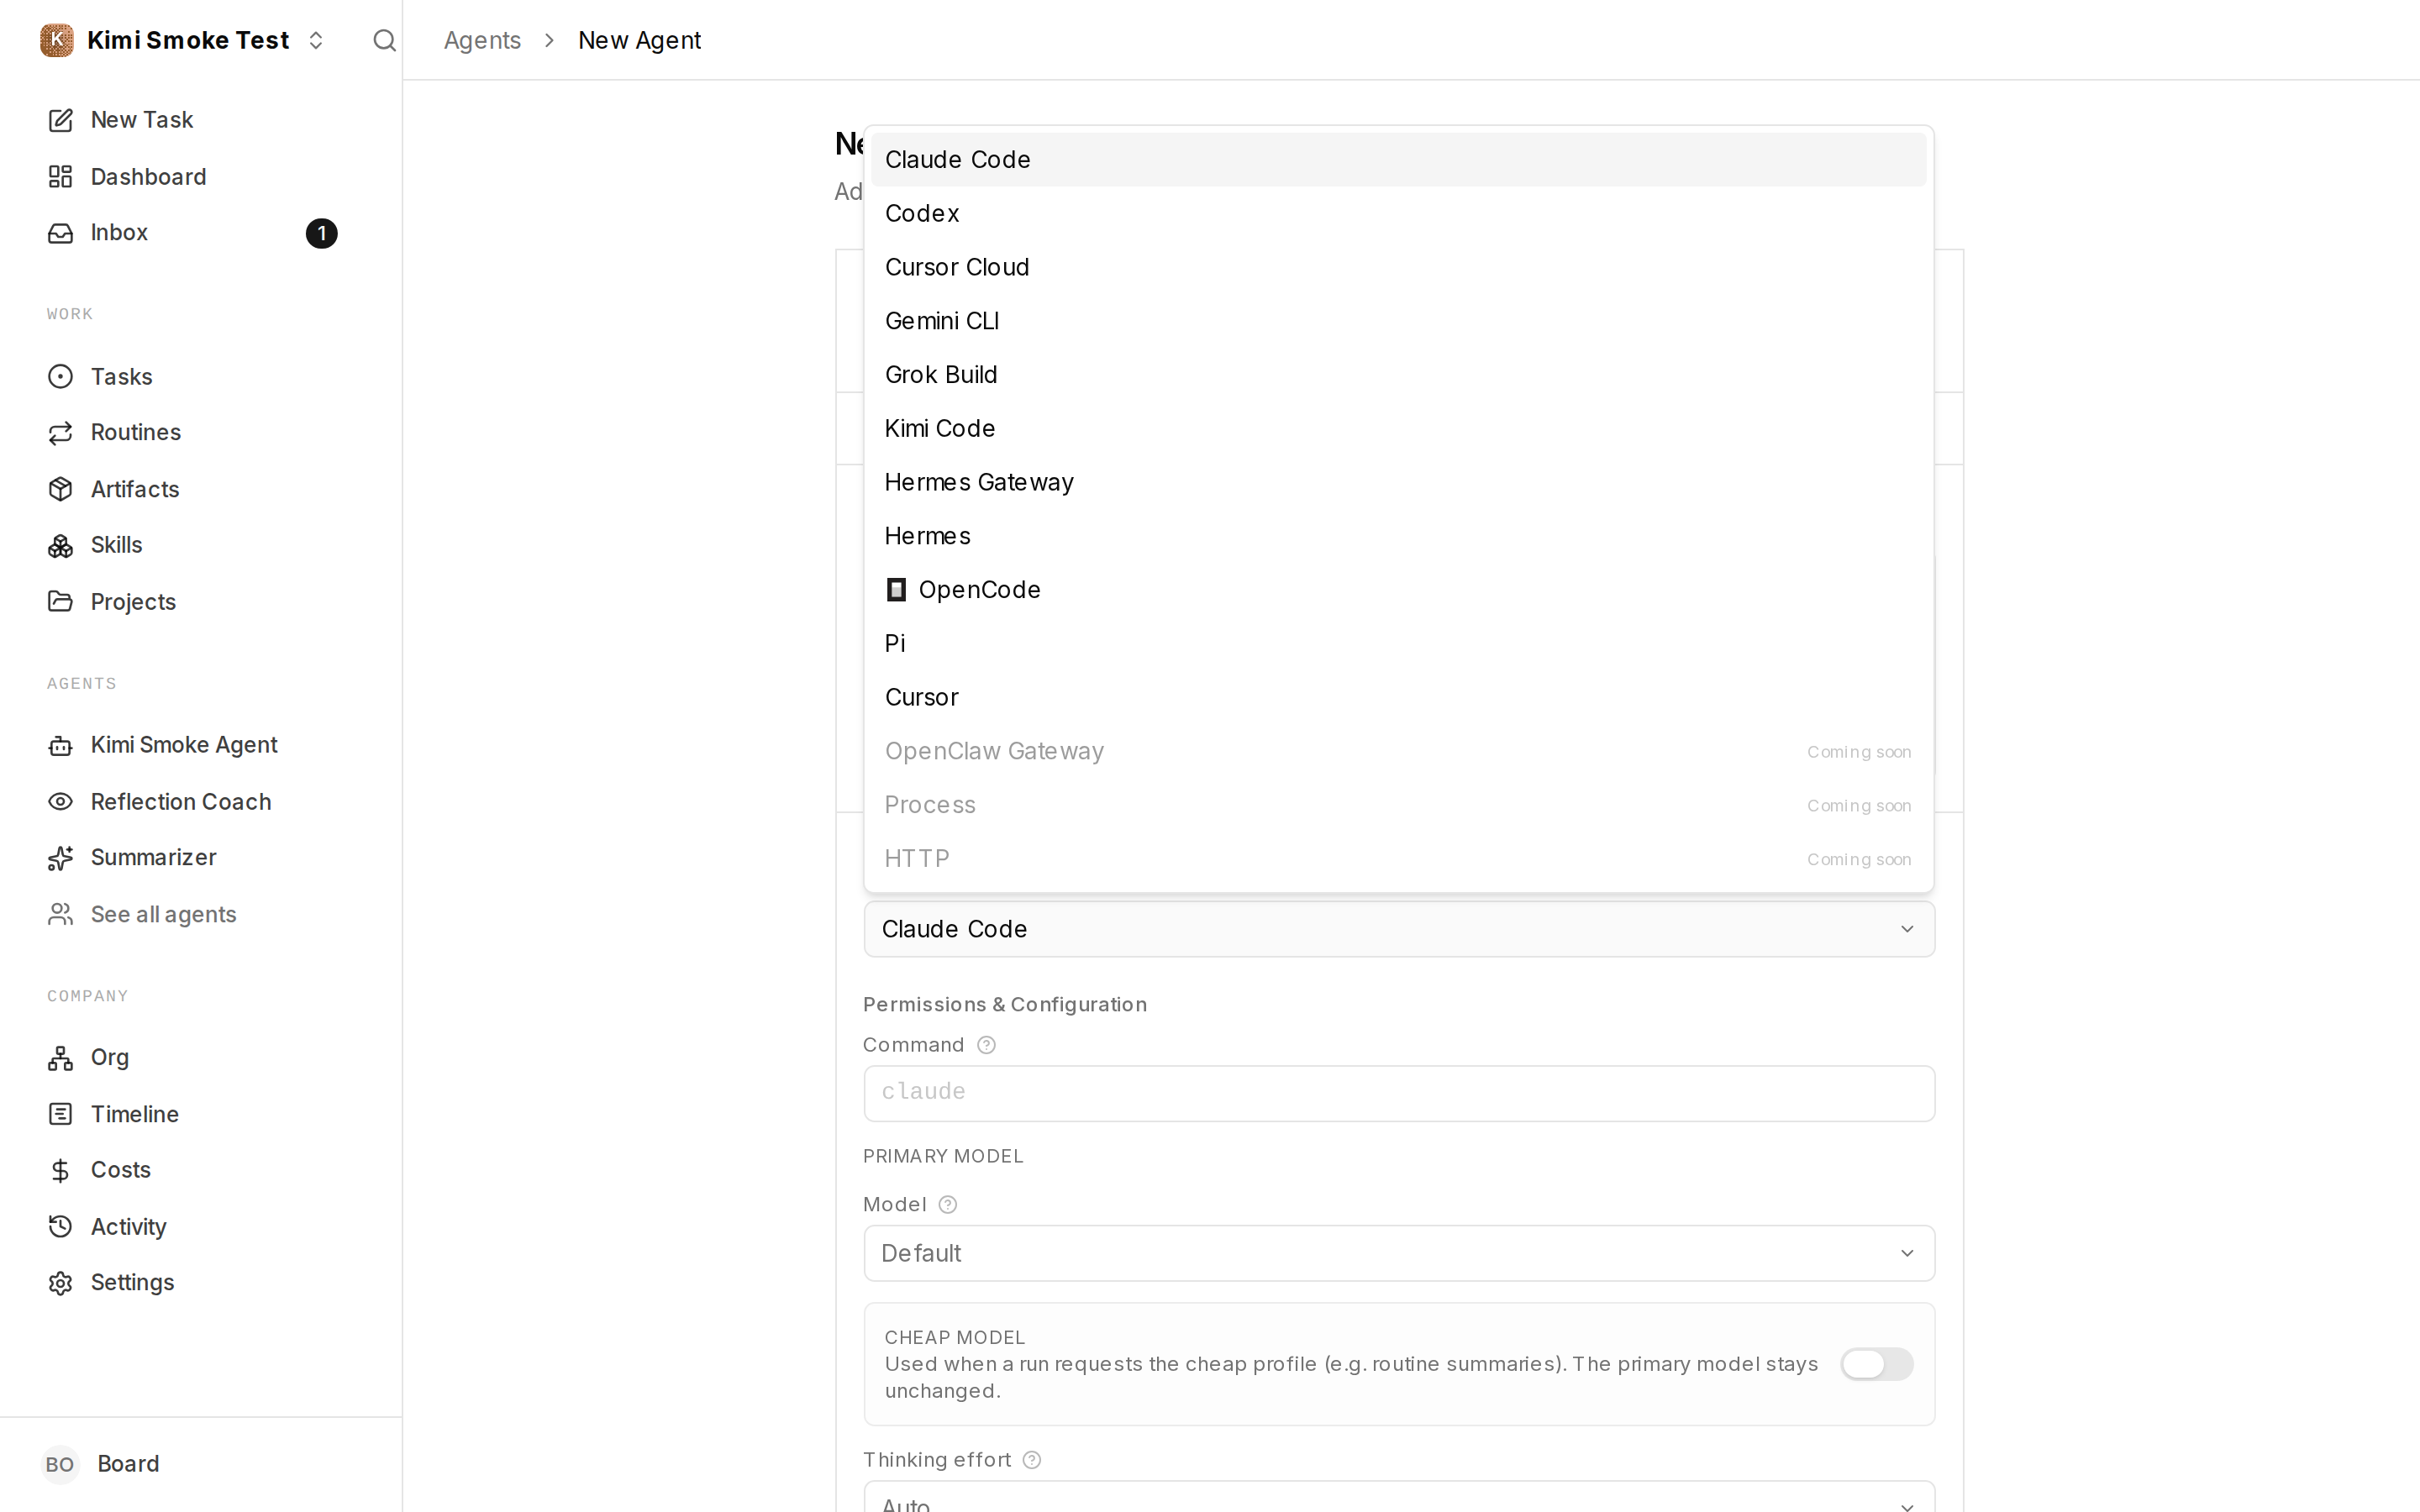 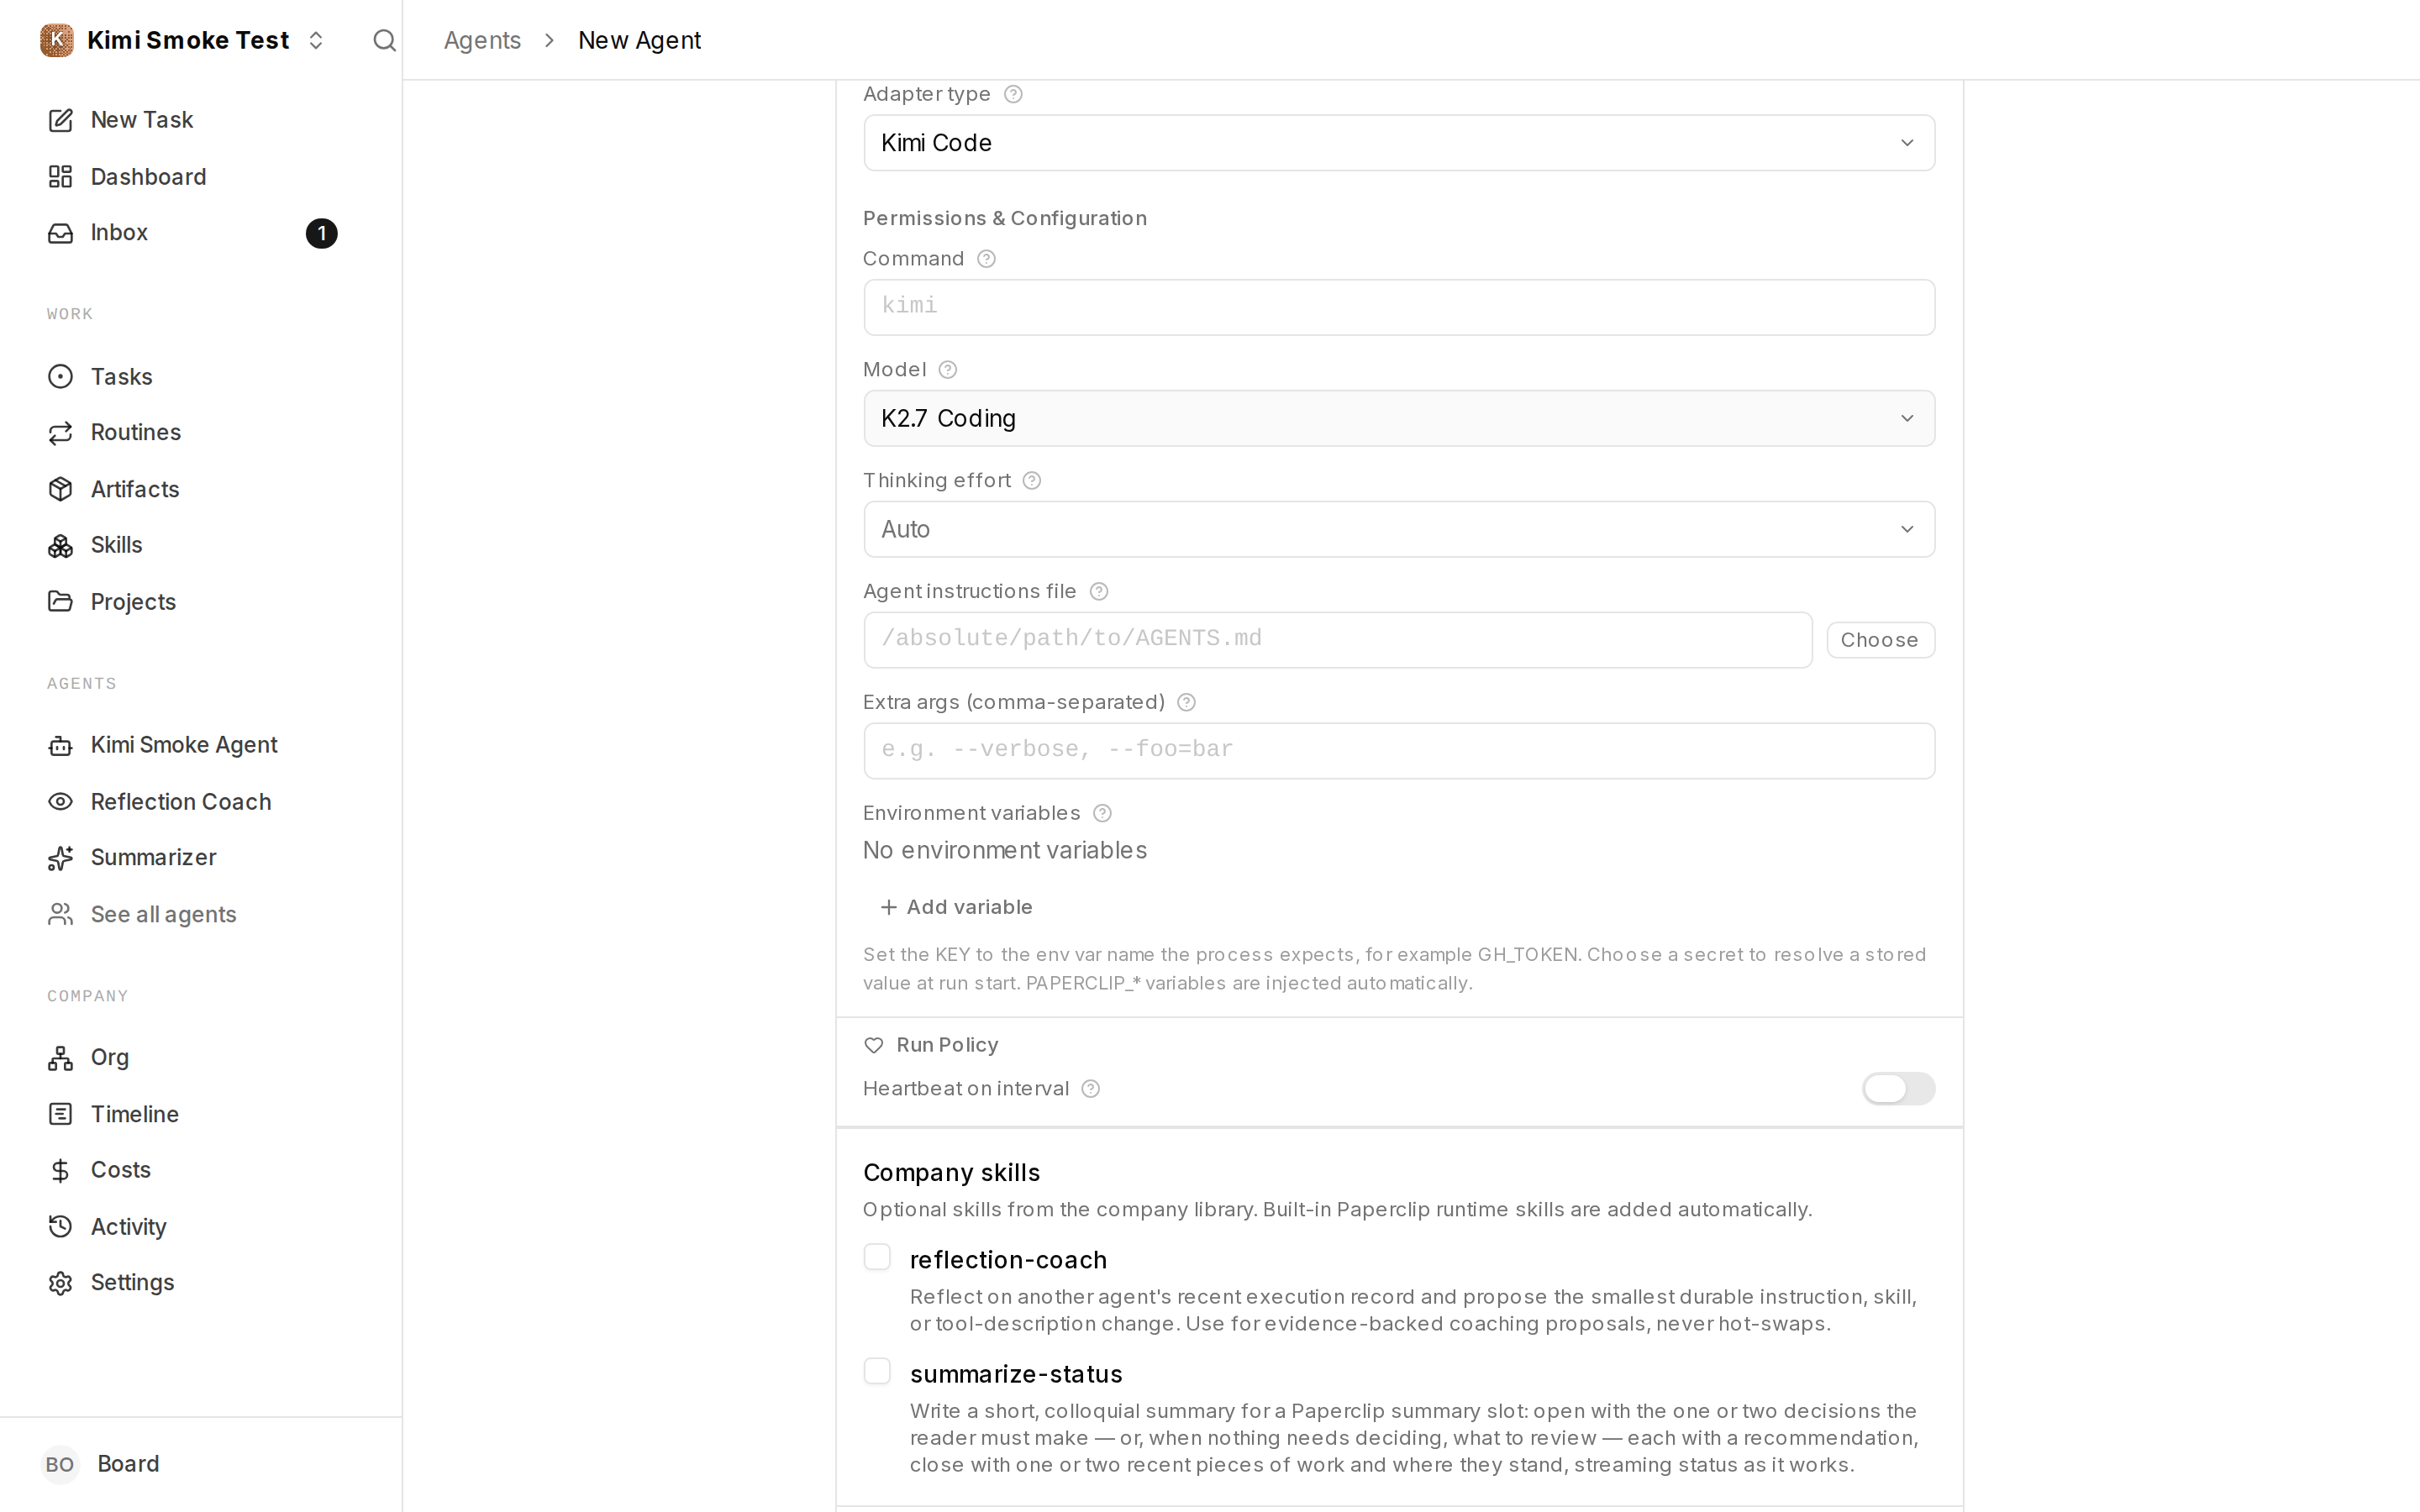 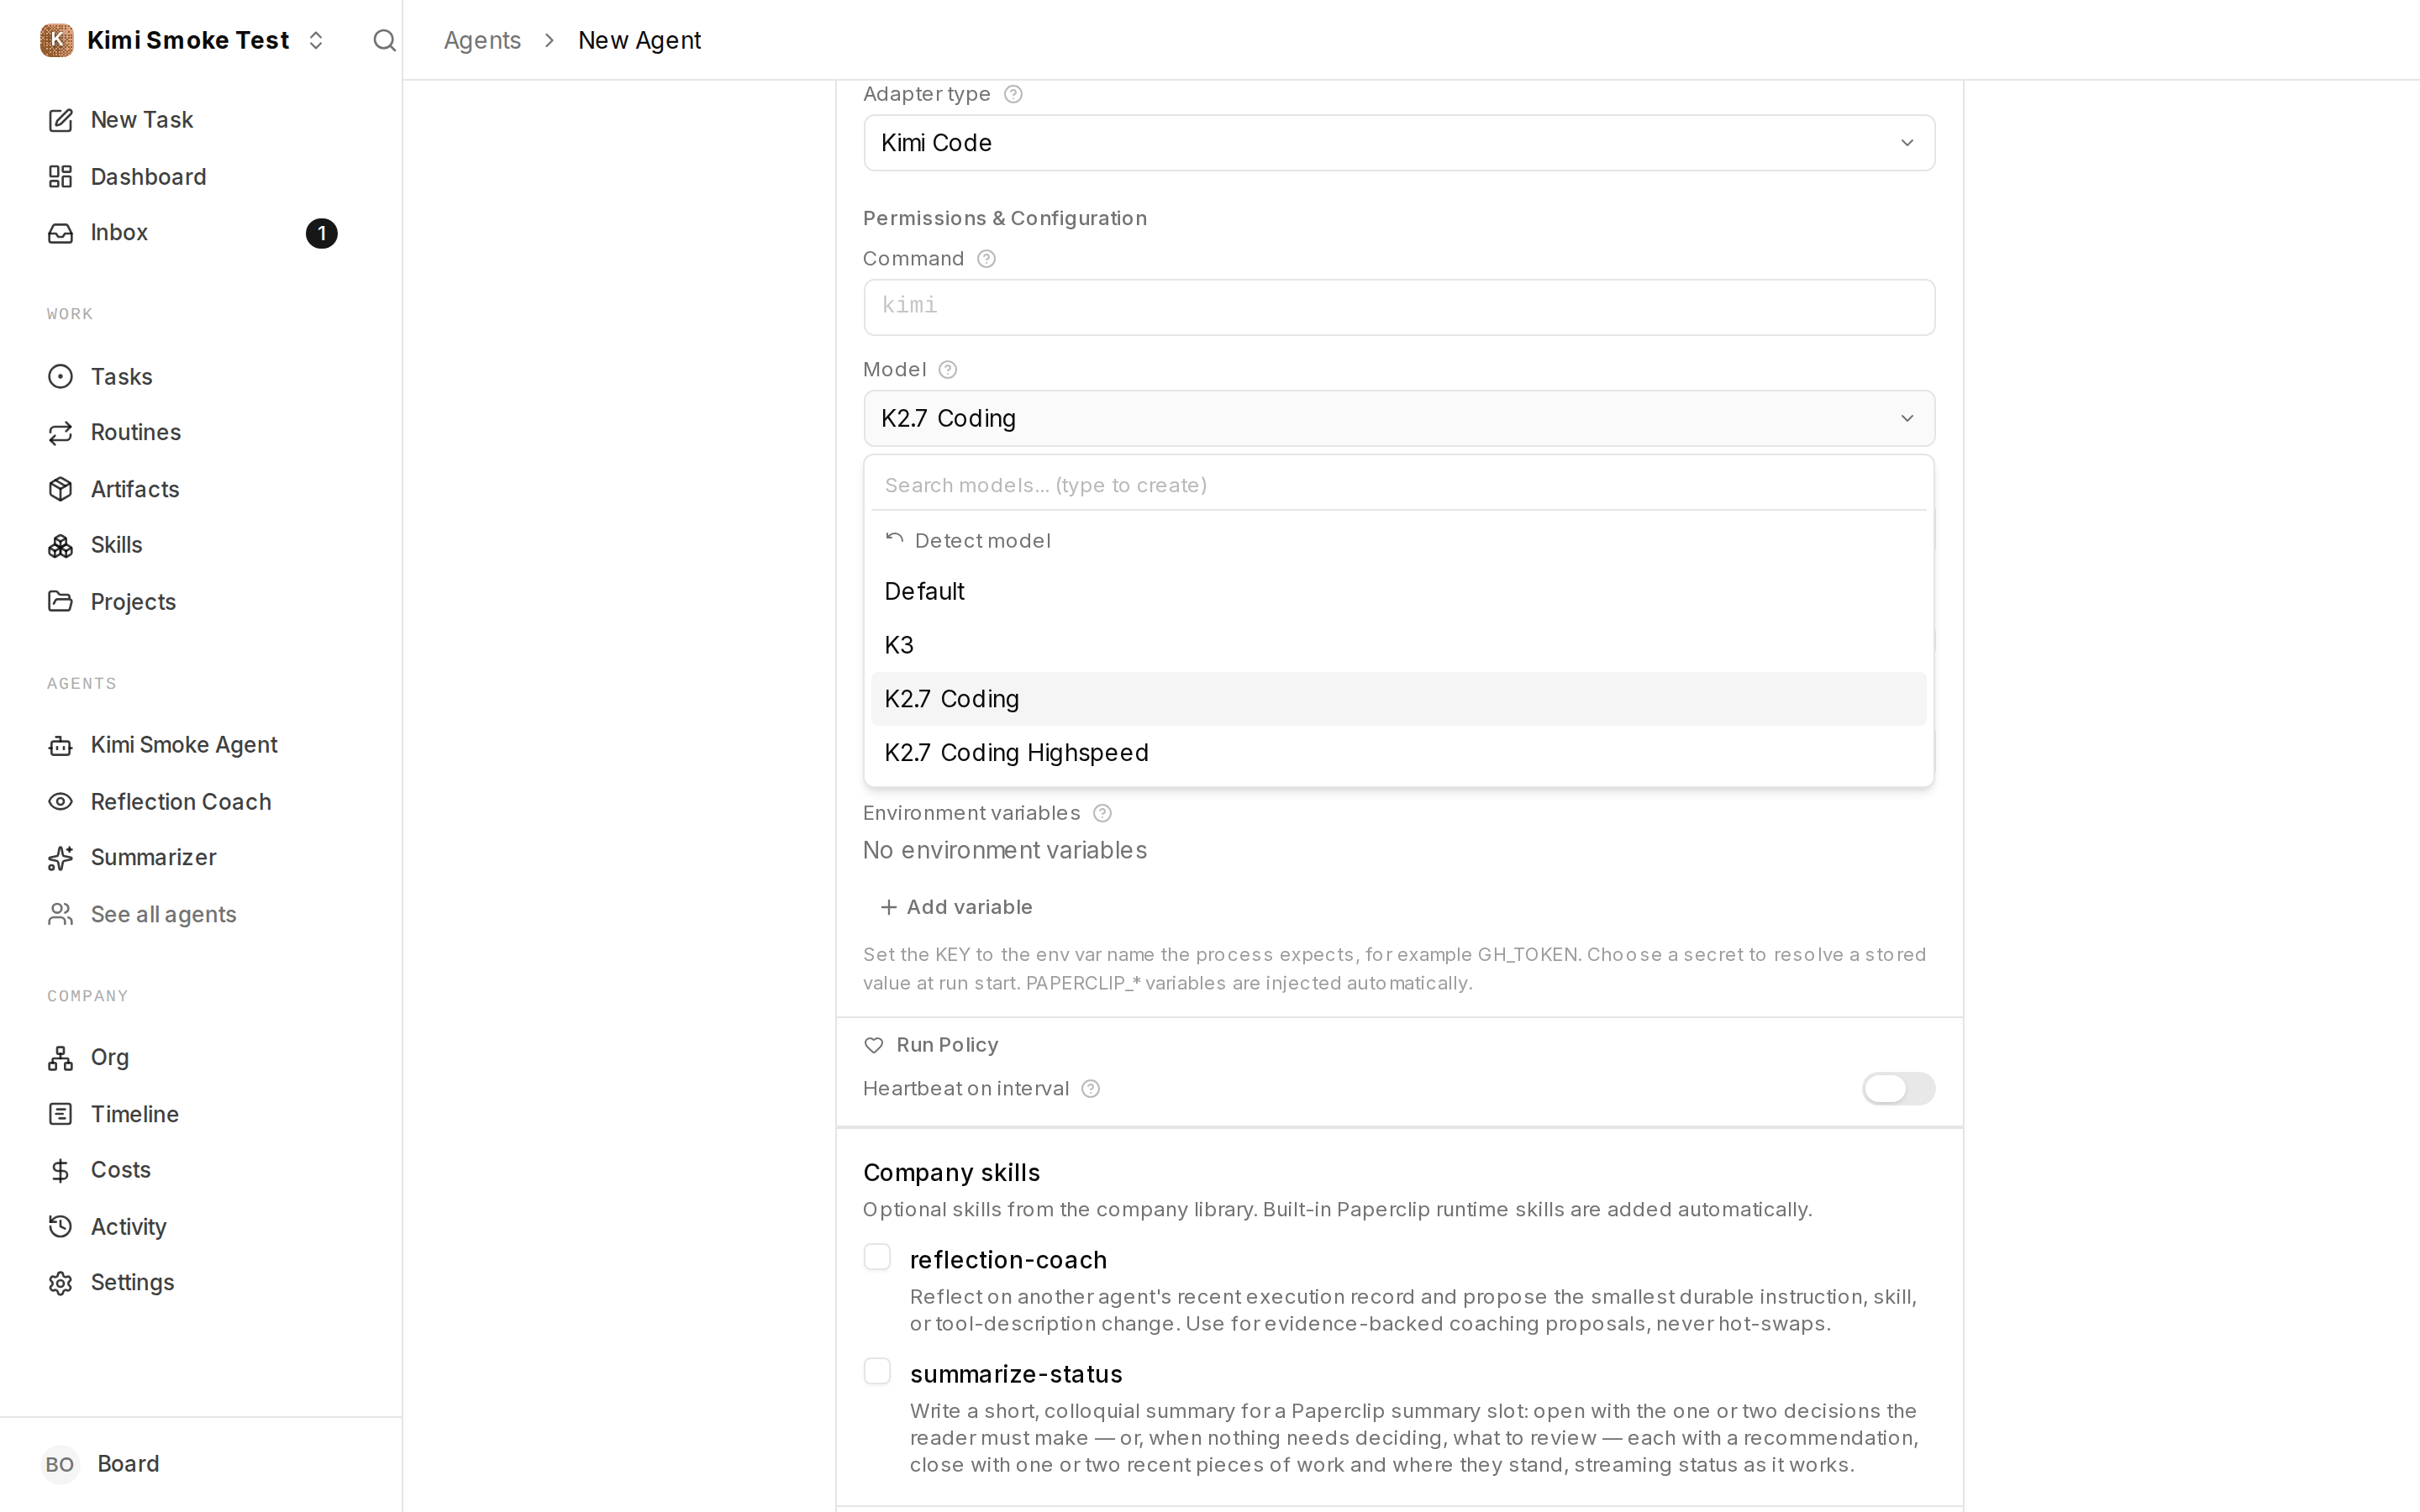 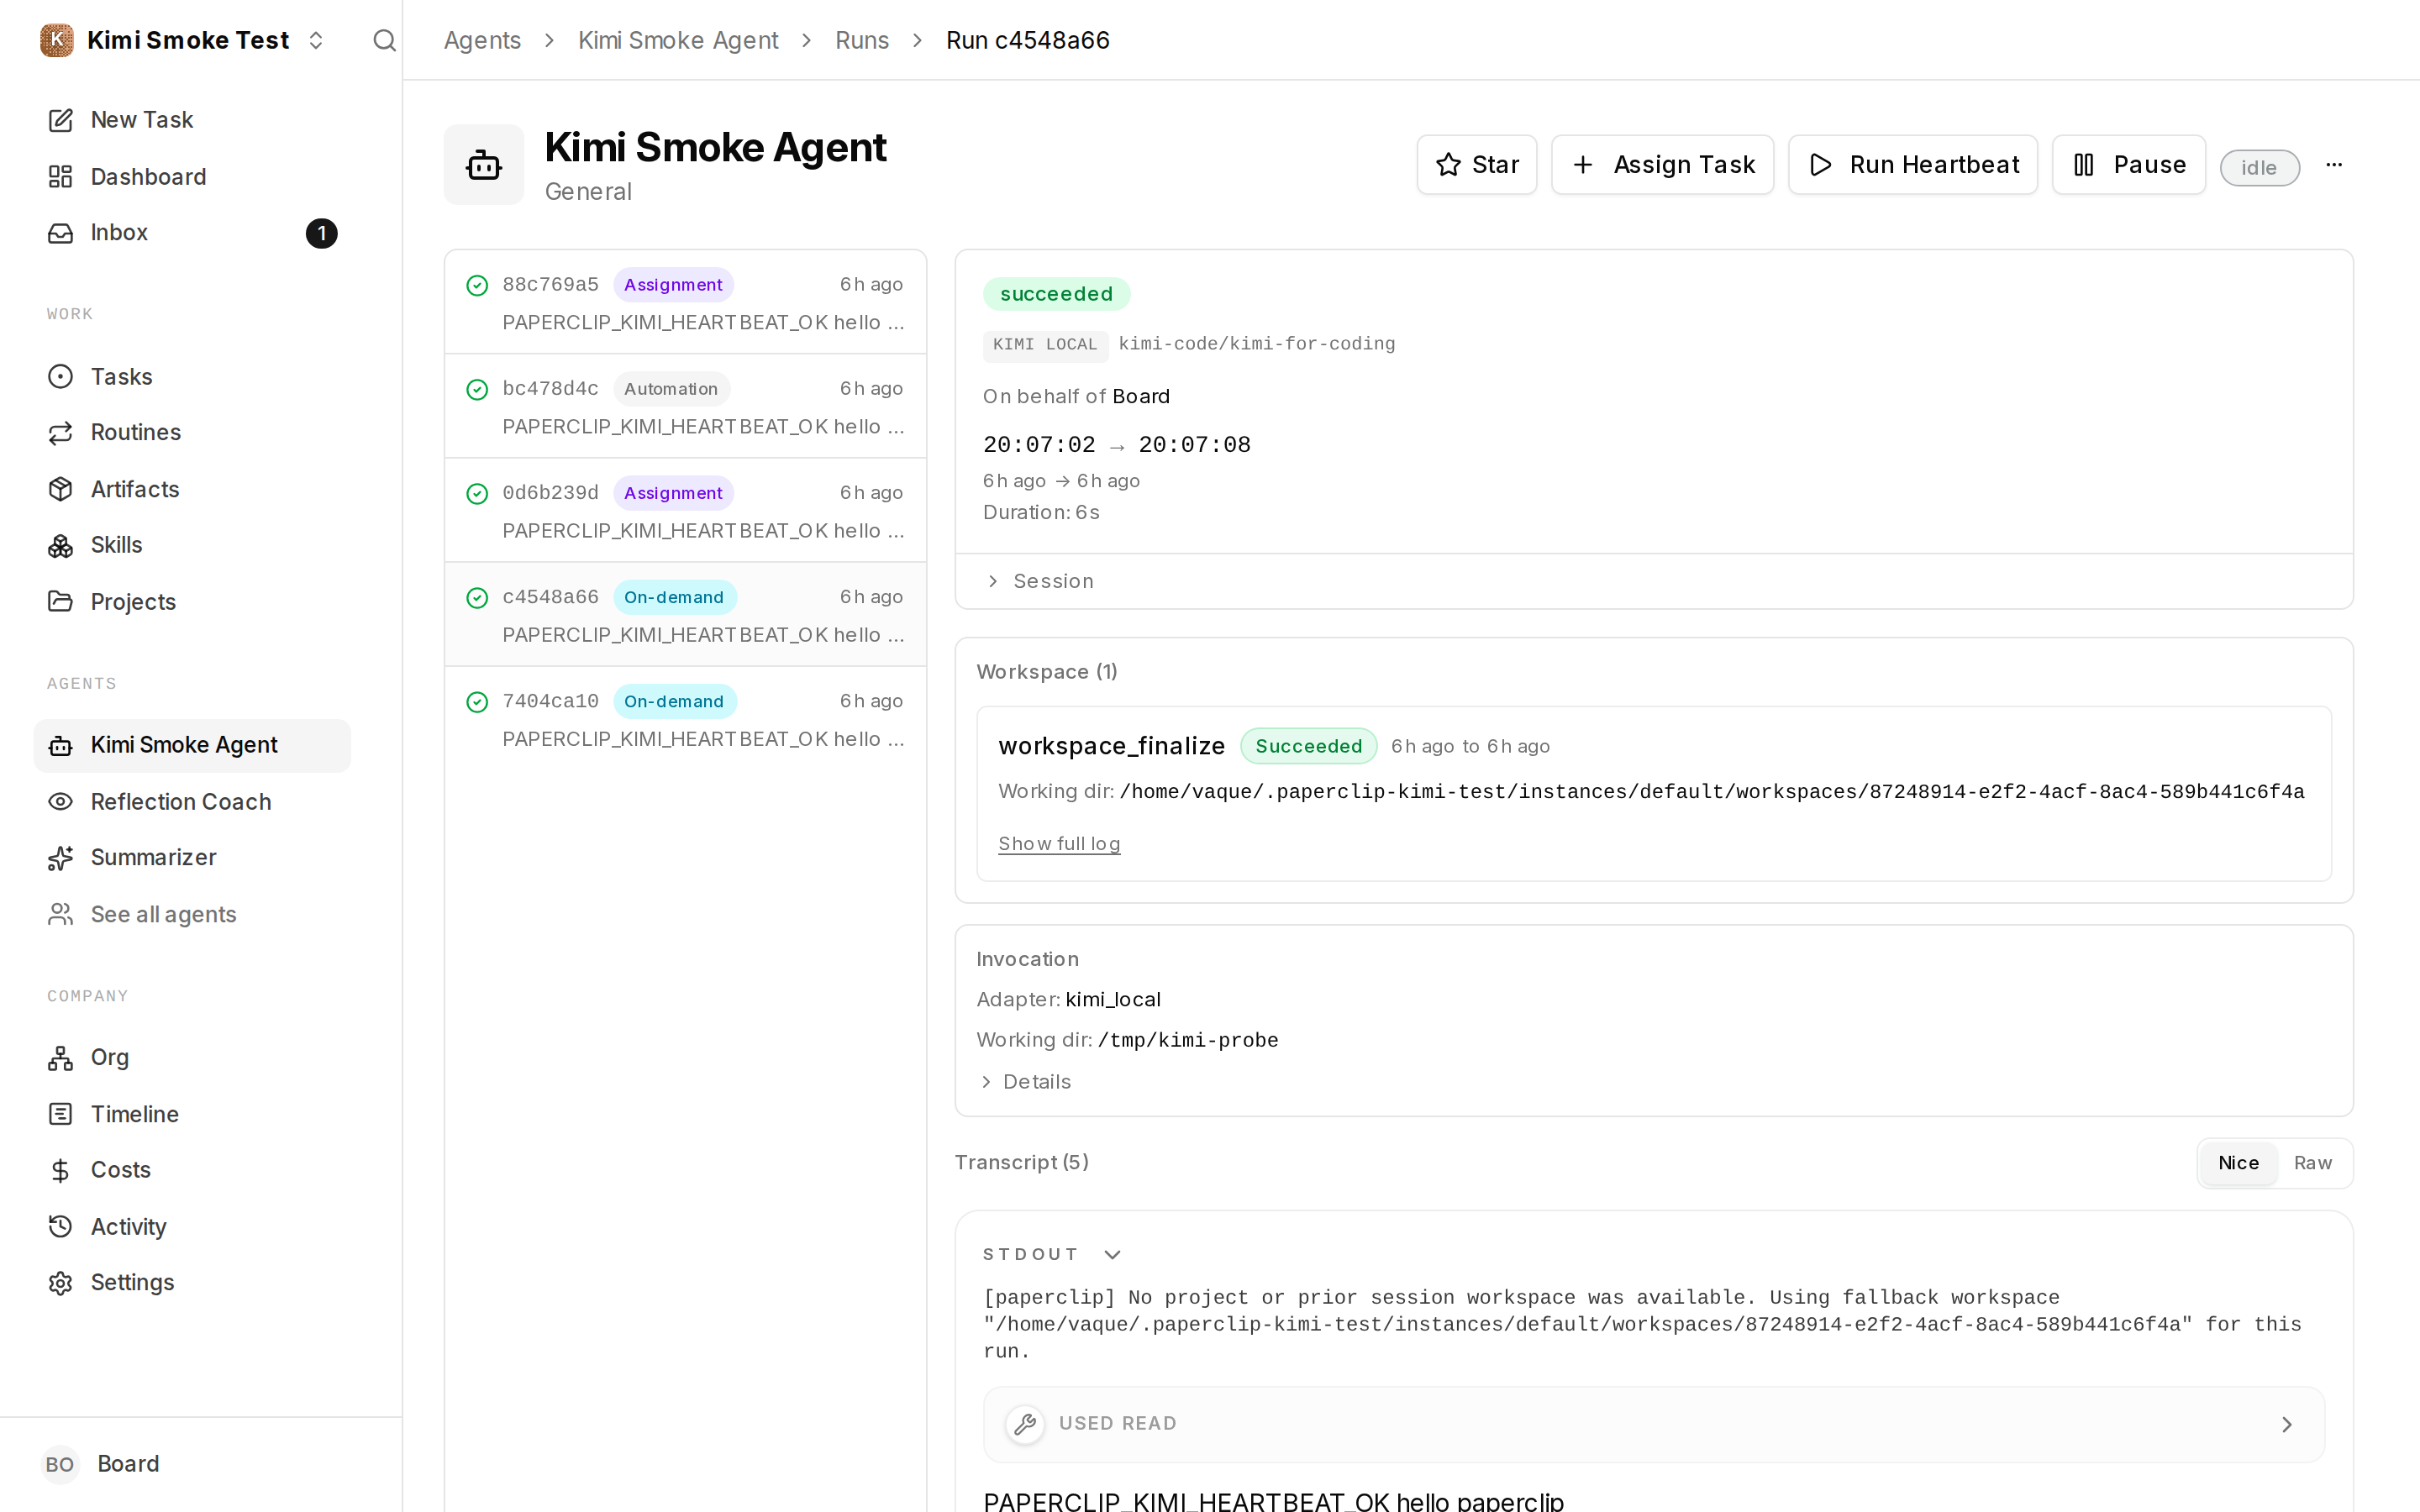 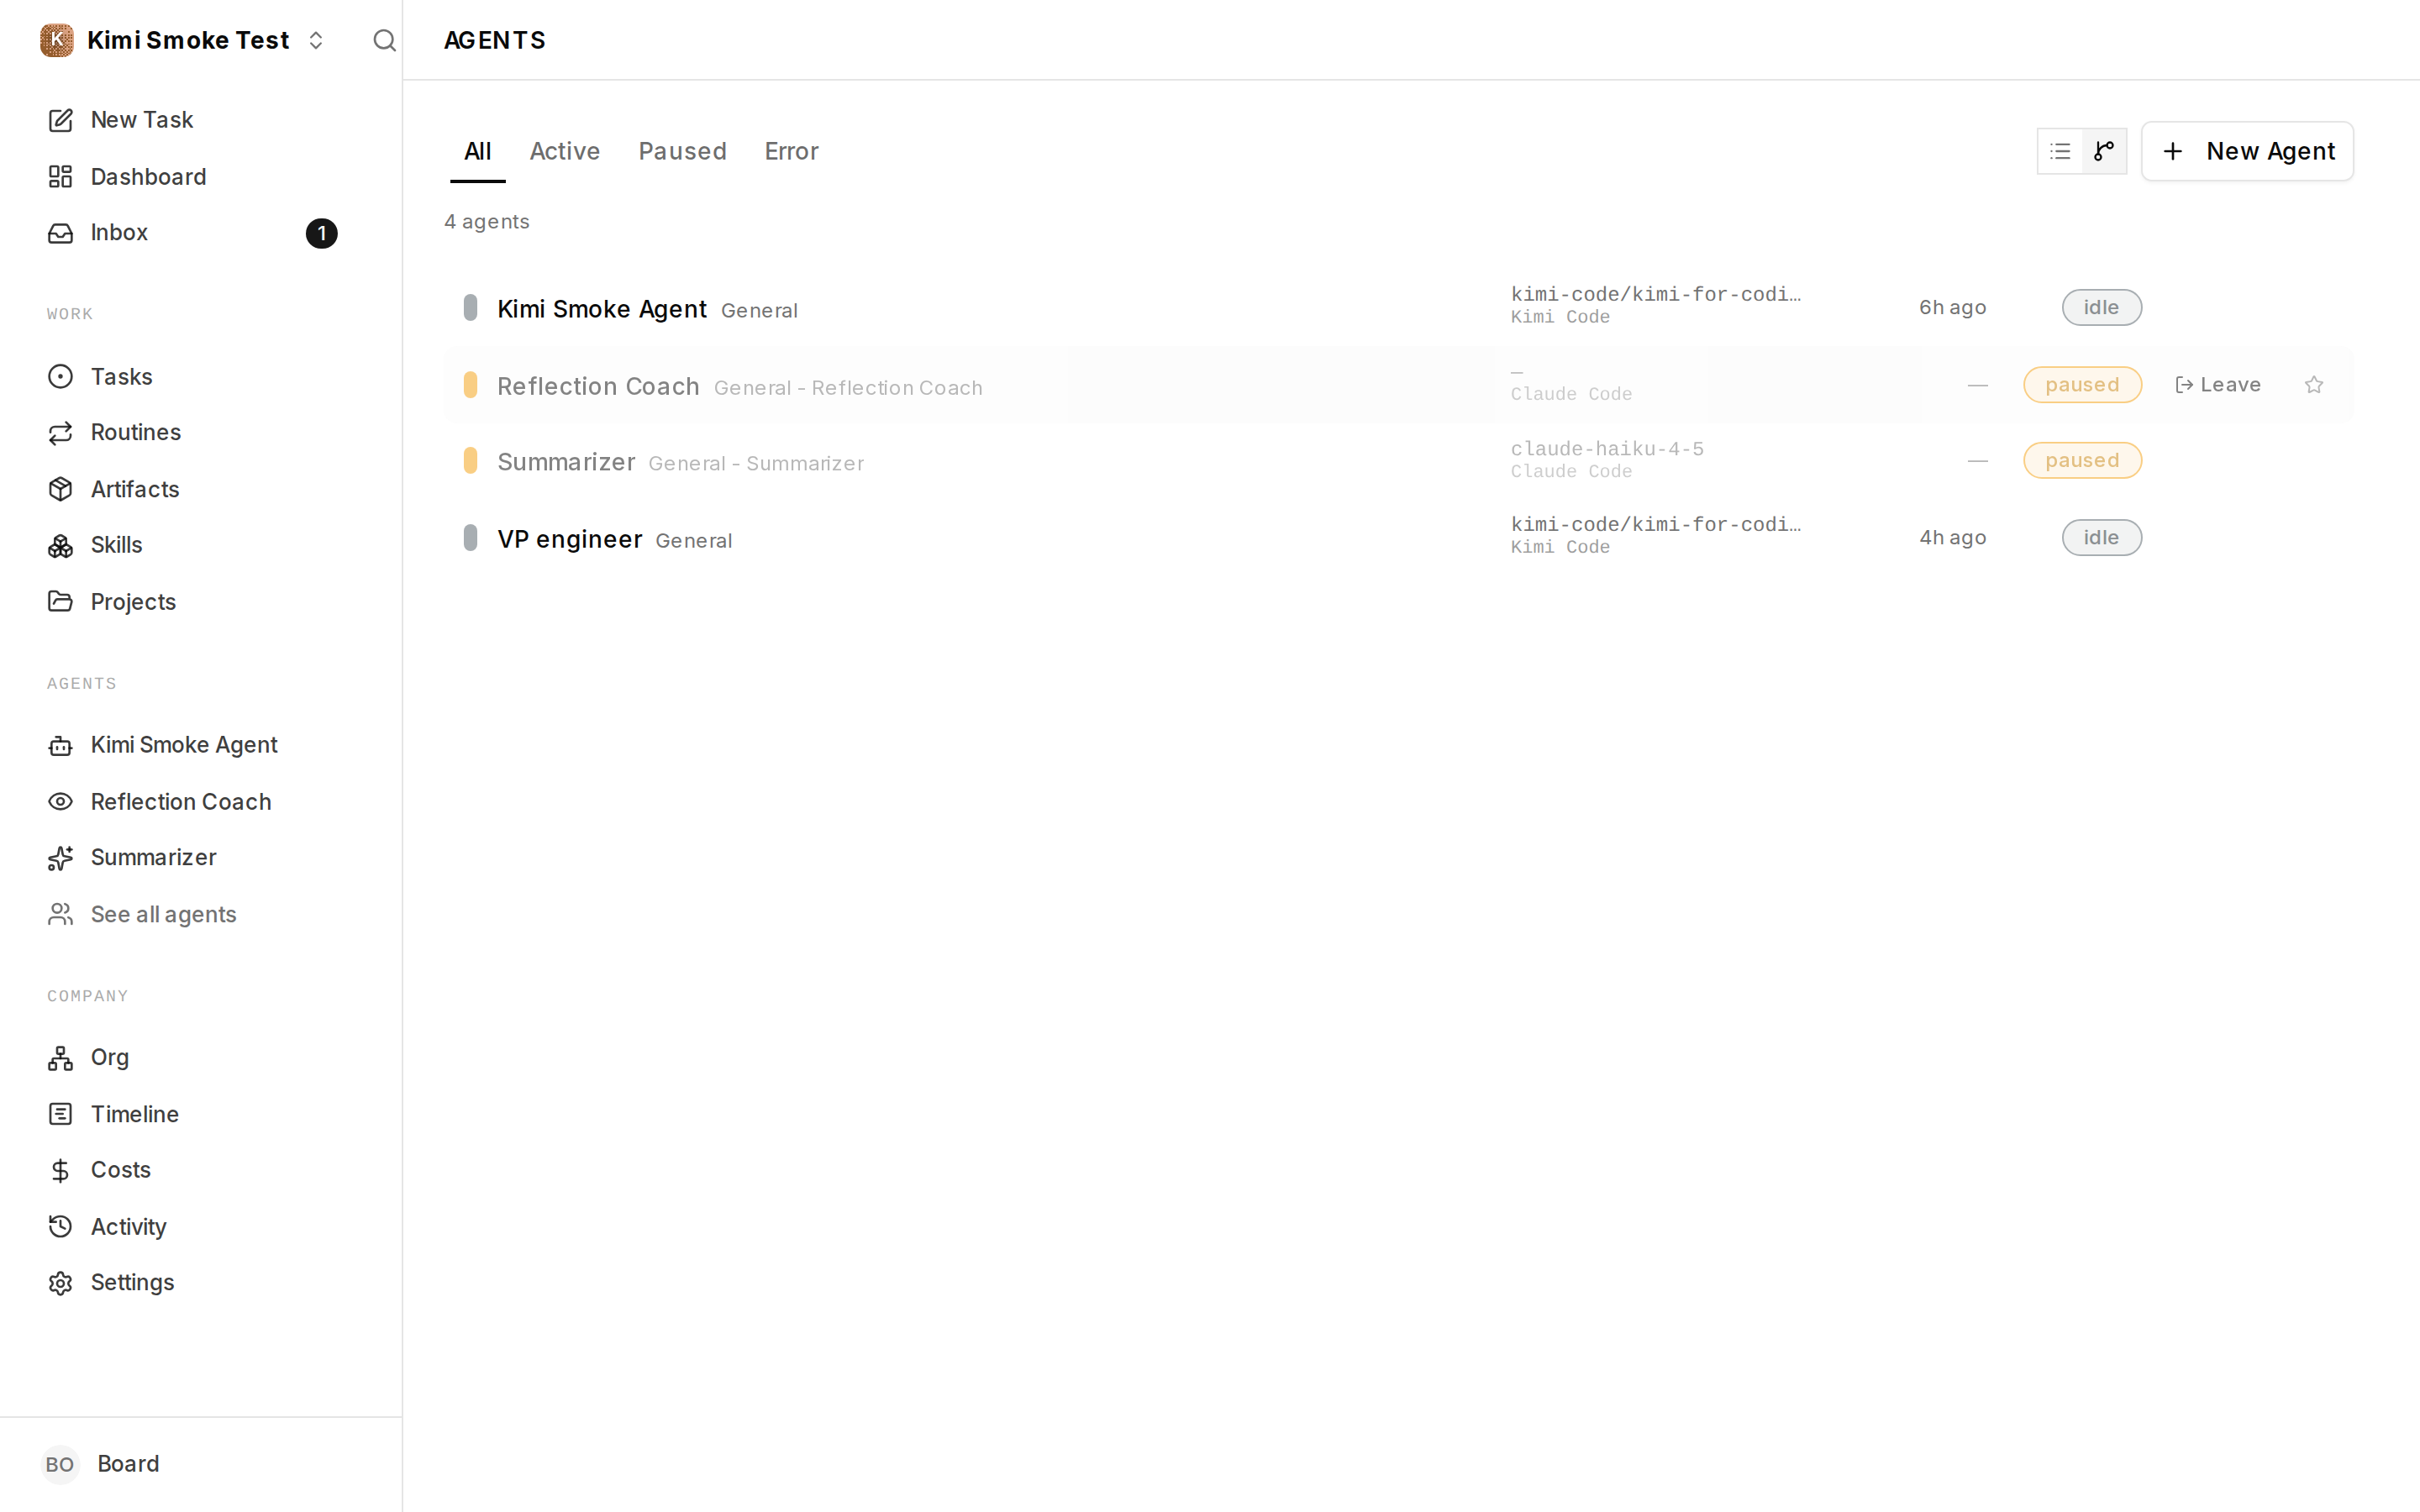 ## Risks - Low risk to existing behavior: the change is additive, one new workspace package plus single-entry registrations alongside existing adapters; no existing adapter code paths are modified. - The adapter invokes the locally installed `kimi` CLI; like other local adapters, run behavior depends on the host's Kimi version. The parser is written against the documented/verified 0.27.0 stream-json schema and degrades gracefully (malformed lines are skipped, failures surface as run errors). - `--skills-dir` overrides Kimi's auto-discovery of user and project skills for the run. This is intentional (paperclip-managed agents get a reproducible, isolated skill set), and it is only passed when at least one Paperclip skill is desired, so unconfigured agents keep default discovery. - Thinking effort is only forwarded to models that advertise `support_efforts` (currently `kimi-code/k3`); `EFFORT_CAPABLE_MODELS` must be extended when more Kimi models gain support, otherwise a configured effort is silently ignored for them. - `Dockerfile` now installs `@moonshot-ai/kimi-code@latest` globally alongside the other agent CLIs, so image size increases slightly. - Maintainer action needed for the npm bootstrap gate: the `policy` job's release-bootstrap step fails until the first npm publish of `@paperclipai/adapter-kimi-local` (the gate from #5146 that every new adapter package has passed through). Enrollment with `publishFromCi: true` is required by the manifest validator (dropping the entry, `false`, or `private` are all rejected), so this is intentionally left to a maintainer. Remaining CI lanes are expected to run once it is done. ## Model Used\n\n- **Current-master rebase, conflict adaptation, and registry-parity coverage:** OpenAI, **GPT-5 Codex** (Codex agent; exact serving model ID and context-window size were not exposed to the runtime), with repository, shell, Git, and GitHub tooling. It preserved Hawik’s commit authorship, reconciled ACPX and environment-capability changes, added current registry tests, and ran the verification above.\n- **Adapter implementation and initial review:** Moonshot AI, **Kimi K3 Coding** (latest), via **Kimi Code CLI v0.27.0** (`kimi-code/k3` alias, 1M-token context window, thinking mode, agentic tool use). The CLI agent explored the repo, wrote the adapter implementation (delegated to a coder sub-agent of the same model), ran tests, and drafted the first version of this PR body. A second model-driven review pass (read-only, same model) audited the diff for security/correctness before submission; its findings (shell-quoting hardening, auth-detection false positive, session-compaction registration, test gaps) were fixed and are included. - **Harness-context fixes and review responses:** Anthropic, **Claude Opus 4.8** (`claude-opus-4-8`) via Claude Code. Diagnosed from run logs that Kimi received only the entry instructions file (not the `HEARTBEAT.md`/`SOUL.md`/`TOOLS.md` bundle) and that `effort` was never wired, then implemented the instruction `--add-dir` delivery, `KIMI_MODEL_THINKING_EFFORT` forwarding, and `--skills-dir` skill delivery, added the accompanying tests and docs, and addressed the automated review comments (preserving external skills on remote sync, treating a signaled exit as a failure). Also extended the `paperclipai agent local-cli` installer to seed the control-plane skills into `~/.kimi-code/skills` for Codex/Claude parity, wired `onEvent` runtime events so the issue-thread activity indicator reflects Kimi's tool and reasoning output live, and built the ACP engine lane (`kimi acp` via the shared acpx engine, default) so the transcript streams with live tool status like the other ACP adapters. The Kimi CLI flags, subcommand, and env var relied on here were verified against the installed Kimi Code CLI 0.27.0. - All CLI behaviors claimed here (`-p`, `--output-format stream-json`, `-r` resume, event shapes, `--add-dir`, `--skills-dir`, `KIMI_MODEL_THINKING_EFFORT`) were verified empirically against the installed Kimi CLI, not assumed. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green *(only the release-bootstrap step remains red, pending the maintainer npm publish described in Risks)* - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups *(will address all Greptile comments as they arrive)* - [x] I will address all Greptile and reviewer comments before requesting merge --- ## Maintainer Addendum (2026-08-20) The shared acpx-engine and issue-chat changes (run-summary segmentation, placeholder tool-event coalescing, `ISSUE_CHAT_TRANSCRIPT_MAX_VISIBLE_ENTRIES` 30 → 400, live-reasoning UI) have been **extracted to #11761** so the cross-adapter behavior changes review and revert independently — both commits there preserve @hawikk's authorship. This PR is now the kimi-specific adapter only (60 files, +3,793/−8, essentially pure addition); the only shared-engine touch left is the `kimi acp` command resolution. `publishFromCi` is `true` — the package name is bootstrapped on npm. --------- Co-authored-by: Claude Opus 4.8 <noreply@anthropic.com> Co-authored-by: Paperclip <noreply@paperclip.ing> Co-authored-by: Dotta <bippadotta@protonmail.com> Co-authored-by: Devin Foley <devin@paperclip.ing>






1411 lines
49 KiB
TypeScript
1411 lines
49 KiB
TypeScript
import { beforeEach, describe, expect, it, vi } from "vitest";
|
|
|
|
const { mockResolveEnvironmentDriverConfigForRuntime } = vi.hoisted(() => ({
|
|
mockResolveEnvironmentDriverConfigForRuntime: vi.fn(),
|
|
}));
|
|
|
|
vi.mock("../services/environment-config.js", () => ({
|
|
resolveEnvironmentDriverConfigForRuntime: mockResolveEnvironmentDriverConfigForRuntime,
|
|
}));
|
|
|
|
import {
|
|
measureStartupStep,
|
|
runWithoutActiveStep,
|
|
SANDBOX_STARTUP_SPAN_ATTRS,
|
|
} from "@paperclipai/adapter-utils/acpx-engine/startup-timing";
|
|
import {
|
|
DEFAULT_SANDBOX_REMOTE_CWD,
|
|
resolveEnvironmentExecutionTarget,
|
|
} from "../services/environment-execution-target.js";
|
|
|
|
const A = SANDBOX_STARTUP_SPAN_ATTRS;
|
|
|
|
// A recording trace context that models the OTel parenting contract:
|
|
// `startSpan(name, options, context)` reads the parent from the explicit
|
|
// `context` token that `contextWithSpan` built. A test asserts the exact parent
|
|
// of each child span without an OTel package.
|
|
function createRecordingTrace() {
|
|
const spans: Array<{
|
|
name: string;
|
|
attributes: Record<string, unknown>;
|
|
parent: unknown;
|
|
ended: boolean;
|
|
setAttribute(key: string, value: unknown): void;
|
|
end(): void;
|
|
}> = [];
|
|
const tracer = {
|
|
startSpan(name: string, _options?: unknown, context?: unknown) {
|
|
const parent =
|
|
context && typeof context === "object" && "span" in context
|
|
? (context as { span: unknown }).span
|
|
: null;
|
|
const span = {
|
|
name,
|
|
attributes: {} as Record<string, unknown>,
|
|
parent,
|
|
ended: false,
|
|
setAttribute(key: string, value: unknown) {
|
|
span.attributes[key] = value;
|
|
},
|
|
end() {
|
|
span.ended = true;
|
|
},
|
|
};
|
|
spans.push(span);
|
|
return span;
|
|
},
|
|
};
|
|
const contextWithSpan = (span: unknown) => ({ span });
|
|
return { tracer, contextWithSpan, spans };
|
|
}
|
|
|
|
// A fake tracer that records the third `startSpan` argument — the parent-context
|
|
// token — for each span, keyed by the span name. `contextWithSpan` wraps a span
|
|
// in a token and keeps that token, so a test asserts the exact token identity,
|
|
// not a rebuilt copy. The exec seam reads the parent-context token from the
|
|
// active step store and passes it as the third `startSpan` argument. This helper
|
|
// holds the parent assertion in one place for reuse.
|
|
function recordParentContext() {
|
|
const calls: Array<{ name: string; parentContext: unknown; span: unknown }> = [];
|
|
const tokens = new Map<unknown, unknown>();
|
|
const tracer = {
|
|
startSpan(name: string, _options?: unknown, parentContext?: unknown) {
|
|
const span = {
|
|
name,
|
|
setAttribute(_key: string, _value: unknown) {},
|
|
setStatus(_status: { code: number; message?: string }) {},
|
|
end() {},
|
|
};
|
|
calls.push({ name, parentContext, span });
|
|
return span;
|
|
},
|
|
};
|
|
const contextWithSpan = (span: unknown) => {
|
|
const token = { span };
|
|
tokens.set(span, token);
|
|
return token;
|
|
};
|
|
// The span object recorded for a given span name.
|
|
const spanNamed = (name: string) => calls.find((call) => call.name === name)?.span;
|
|
// The parent-context token that `startSpan` received for a given span name.
|
|
const parentContextFor = (name: string) =>
|
|
calls.find((call) => call.name === name)?.parentContext;
|
|
// The parent-context token that `contextWithSpan` returned for a given span.
|
|
const tokenForSpan = (span: unknown) => tokens.get(span);
|
|
return { tracer, contextWithSpan, calls, spanNamed, parentContextFor, tokenForSpan };
|
|
}
|
|
|
|
describe("resolveEnvironmentExecutionTarget", () => {
|
|
beforeEach(() => {
|
|
mockResolveEnvironmentDriverConfigForRuntime.mockReset();
|
|
delete process.env.PAPERCLIP_API_URL;
|
|
delete process.env.PAPERCLIP_RUNTIME_API_URL;
|
|
});
|
|
|
|
it("uses a bounded default cwd for sandbox targets when lease metadata omits remoteCwd", async () => {
|
|
mockResolveEnvironmentDriverConfigForRuntime.mockResolvedValue({
|
|
driver: "sandbox",
|
|
config: {
|
|
provider: "fake-plugin",
|
|
reuseLease: false,
|
|
timeoutMs: 30_000,
|
|
},
|
|
});
|
|
|
|
const target = await resolveEnvironmentExecutionTarget({
|
|
db: {} as never,
|
|
companyId: "company-1",
|
|
adapterType: "codex_local",
|
|
environment: {
|
|
id: "env-1",
|
|
driver: "sandbox",
|
|
config: {
|
|
provider: "fake-plugin",
|
|
},
|
|
},
|
|
leaseId: "lease-1",
|
|
leaseMetadata: {},
|
|
lease: null,
|
|
environmentRuntime: null,
|
|
});
|
|
|
|
expect(target).toMatchObject({
|
|
kind: "remote",
|
|
transport: "sandbox",
|
|
providerKey: "fake-plugin",
|
|
remoteCwd: DEFAULT_SANDBOX_REMOTE_CWD,
|
|
leaseId: "lease-1",
|
|
environmentId: "env-1",
|
|
timeoutMs: 30_000,
|
|
});
|
|
});
|
|
|
|
it("keeps sandbox targets on bridge mode even when lease metadata includes a Paperclip API URL", async () => {
|
|
mockResolveEnvironmentDriverConfigForRuntime.mockResolvedValue({
|
|
driver: "sandbox",
|
|
config: {
|
|
provider: "fake-plugin",
|
|
reuseLease: false,
|
|
timeoutMs: 30_000,
|
|
},
|
|
});
|
|
|
|
const target = await resolveEnvironmentExecutionTarget({
|
|
db: {} as never,
|
|
companyId: "company-1",
|
|
adapterType: "codex_local",
|
|
environment: {
|
|
id: "env-1",
|
|
driver: "sandbox",
|
|
config: {
|
|
provider: "fake-plugin",
|
|
},
|
|
},
|
|
leaseId: "lease-1",
|
|
leaseMetadata: {
|
|
paperclipApiUrl: "https://paperclip.example.test",
|
|
},
|
|
lease: null,
|
|
environmentRuntime: null,
|
|
});
|
|
|
|
expect(target).toMatchObject({
|
|
kind: "remote",
|
|
transport: "sandbox",
|
|
providerKey: "fake-plugin",
|
|
remoteCwd: DEFAULT_SANDBOX_REMOTE_CWD,
|
|
});
|
|
expect(target).not.toHaveProperty("paperclipApiUrl");
|
|
expect(target).not.toHaveProperty("paperclipTransport");
|
|
});
|
|
|
|
it("passes through a provider-declared sandbox shell command from lease metadata", async () => {
|
|
mockResolveEnvironmentDriverConfigForRuntime.mockResolvedValue({
|
|
driver: "sandbox",
|
|
config: {
|
|
provider: "fake-plugin",
|
|
reuseLease: false,
|
|
timeoutMs: 30_000,
|
|
},
|
|
});
|
|
|
|
const target = await resolveEnvironmentExecutionTarget({
|
|
db: {} as never,
|
|
companyId: "company-1",
|
|
adapterType: "claude_local",
|
|
environment: {
|
|
id: "env-1",
|
|
driver: "sandbox",
|
|
config: {
|
|
provider: "fake-plugin",
|
|
},
|
|
},
|
|
leaseId: "lease-1",
|
|
leaseMetadata: {
|
|
shellCommand: "bash",
|
|
},
|
|
lease: null,
|
|
environmentRuntime: null,
|
|
});
|
|
|
|
expect(target).toMatchObject({
|
|
kind: "remote",
|
|
transport: "sandbox",
|
|
shellCommand: "bash",
|
|
});
|
|
});
|
|
|
|
it("keeps sandbox targets on callback bridge execution even when lease metadata advertises SSH access", async () => {
|
|
mockResolveEnvironmentDriverConfigForRuntime.mockResolvedValue({
|
|
driver: "sandbox",
|
|
config: {
|
|
provider: "fake-plugin",
|
|
reuseLease: false,
|
|
timeoutMs: 30_000,
|
|
},
|
|
});
|
|
|
|
const target = await resolveEnvironmentExecutionTarget({
|
|
db: {} as never,
|
|
companyId: "company-1",
|
|
adapterType: "claude_local",
|
|
environment: {
|
|
id: "env-1",
|
|
driver: "sandbox",
|
|
config: {
|
|
provider: "fake-plugin",
|
|
},
|
|
},
|
|
leaseId: "lease-1",
|
|
leaseMetadata: {
|
|
remoteCwd: "/home/sandbox/paperclip-workspace",
|
|
sshAccess: {
|
|
type: "ssh",
|
|
host: "ssh.example.test",
|
|
port: 22,
|
|
username: "paperclip",
|
|
},
|
|
},
|
|
lease: null,
|
|
environmentRuntime: null,
|
|
});
|
|
|
|
expect(target).toMatchObject({
|
|
kind: "remote",
|
|
transport: "sandbox",
|
|
providerKey: "fake-plugin",
|
|
remoteCwd: "/home/sandbox/paperclip-workspace",
|
|
});
|
|
});
|
|
|
|
it("resolves sandbox targets for every remote-managed adapter, including grok_local and kimi_local", async () => {
|
|
for (const adapterType of [
|
|
"claude_local",
|
|
"codex_local",
|
|
"cursor",
|
|
"gemini_local",
|
|
"grok_local",
|
|
"kimi_local",
|
|
"opencode_local",
|
|
"pi_local",
|
|
]) {
|
|
mockResolveEnvironmentDriverConfigForRuntime.mockResolvedValue({
|
|
driver: "sandbox",
|
|
config: {
|
|
provider: "fake-plugin",
|
|
reuseLease: false,
|
|
timeoutMs: 30_000,
|
|
},
|
|
});
|
|
|
|
const target = await resolveEnvironmentExecutionTarget({
|
|
db: {} as never,
|
|
companyId: "company-1",
|
|
adapterType,
|
|
environment: {
|
|
id: "env-1",
|
|
driver: "sandbox",
|
|
config: { provider: "fake-plugin" },
|
|
},
|
|
leaseId: "lease-1",
|
|
leaseMetadata: {},
|
|
lease: null,
|
|
environmentRuntime: null,
|
|
});
|
|
|
|
expect(target, `adapter ${adapterType}`).toMatchObject({
|
|
kind: "remote",
|
|
transport: "sandbox",
|
|
providerKey: "fake-plugin",
|
|
});
|
|
}
|
|
});
|
|
|
|
it("returns null for adapters without remote-managed environment support", async () => {
|
|
for (const driver of ["sandbox", "ssh"] as const) {
|
|
const target = await resolveEnvironmentExecutionTarget({
|
|
db: {} as never,
|
|
companyId: "company-1",
|
|
adapterType: "process",
|
|
environment: {
|
|
id: "env-1",
|
|
driver,
|
|
config: { provider: "fake-plugin" },
|
|
},
|
|
leaseId: "lease-1",
|
|
leaseMetadata: {},
|
|
lease: null,
|
|
environmentRuntime: null,
|
|
});
|
|
|
|
expect(target, `driver ${driver}`).toBeNull();
|
|
}
|
|
expect(mockResolveEnvironmentDriverConfigForRuntime).not.toHaveBeenCalled();
|
|
});
|
|
|
|
it("resolves SSH execution targets for grok_local", async () => {
|
|
mockResolveEnvironmentDriverConfigForRuntime.mockResolvedValue({
|
|
driver: "ssh",
|
|
config: {
|
|
host: "ssh.example.test",
|
|
port: 22,
|
|
username: "paperclip",
|
|
remoteWorkspacePath: "/srv/paperclip",
|
|
privateKey: "PRIVATE KEY",
|
|
knownHosts: "[ssh.example.test]:22 ssh-ed25519 AAAA",
|
|
strictHostKeyChecking: true,
|
|
},
|
|
});
|
|
|
|
const target = await resolveEnvironmentExecutionTarget({
|
|
db: {} as never,
|
|
companyId: "company-1",
|
|
adapterType: "grok_local",
|
|
environment: {
|
|
id: "env-ssh-1",
|
|
driver: "ssh",
|
|
config: {},
|
|
},
|
|
leaseId: "lease-ssh-1",
|
|
leaseMetadata: {},
|
|
lease: null,
|
|
environmentRuntime: null,
|
|
});
|
|
|
|
expect(target).toMatchObject({
|
|
kind: "remote",
|
|
transport: "ssh",
|
|
remoteCwd: "/srv/paperclip",
|
|
});
|
|
});
|
|
|
|
it("resolves SSH execution targets for kimi_local", async () => {
|
|
mockResolveEnvironmentDriverConfigForRuntime.mockResolvedValue({
|
|
driver: "ssh",
|
|
config: {
|
|
host: "ssh.example.test",
|
|
port: 22,
|
|
username: "paperclip",
|
|
remoteWorkspacePath: "/srv/paperclip",
|
|
privateKey: "PRIVATE KEY",
|
|
knownHosts: "[ssh.example.test]:22 ssh-ed25519 AAAA",
|
|
strictHostKeyChecking: true,
|
|
},
|
|
});
|
|
|
|
const target = await resolveEnvironmentExecutionTarget({
|
|
db: {} as never,
|
|
companyId: "company-1",
|
|
adapterType: "kimi_local",
|
|
environment: {
|
|
id: "env-ssh-1",
|
|
driver: "ssh",
|
|
config: {},
|
|
},
|
|
leaseId: "lease-ssh-1",
|
|
leaseMetadata: {},
|
|
lease: null,
|
|
environmentRuntime: null,
|
|
});
|
|
|
|
expect(target).toMatchObject({
|
|
kind: "remote",
|
|
transport: "ssh",
|
|
remoteCwd: "/srv/paperclip",
|
|
});
|
|
});
|
|
|
|
it("resolves SSH execution targets in bridge mode", async () => {
|
|
mockResolveEnvironmentDriverConfigForRuntime.mockResolvedValue({
|
|
driver: "ssh",
|
|
config: {
|
|
host: "ssh.example.test",
|
|
port: 22,
|
|
username: "paperclip",
|
|
remoteWorkspacePath: "/srv/paperclip",
|
|
privateKey: "PRIVATE KEY",
|
|
knownHosts: "[ssh.example.test]:22 ssh-ed25519 AAAA",
|
|
strictHostKeyChecking: true,
|
|
},
|
|
});
|
|
|
|
const target = await resolveEnvironmentExecutionTarget({
|
|
db: {} as never,
|
|
companyId: "company-1",
|
|
adapterType: "codex_local",
|
|
environment: {
|
|
id: "env-ssh-1",
|
|
driver: "ssh",
|
|
config: {},
|
|
},
|
|
leaseId: "lease-ssh-1",
|
|
leaseMetadata: {},
|
|
lease: null,
|
|
environmentRuntime: null,
|
|
});
|
|
|
|
expect(target).toMatchObject({
|
|
kind: "remote",
|
|
transport: "ssh",
|
|
remoteCwd: "/srv/paperclip",
|
|
leaseId: "lease-ssh-1",
|
|
environmentId: "env-ssh-1",
|
|
spec: {
|
|
host: "ssh.example.test",
|
|
port: 22,
|
|
username: "paperclip",
|
|
remoteWorkspacePath: "/srv/paperclip",
|
|
remoteCwd: "/srv/paperclip",
|
|
},
|
|
});
|
|
expect(target).not.toHaveProperty("paperclipApiUrl");
|
|
});
|
|
|
|
it("exposes a sandbox runner with single-stream stdin upload disabled", async () => {
|
|
mockResolveEnvironmentDriverConfigForRuntime.mockResolvedValue({
|
|
driver: "sandbox",
|
|
config: {
|
|
provider: "fake-plugin",
|
|
reuseLease: false,
|
|
timeoutMs: 30_000,
|
|
},
|
|
});
|
|
|
|
const environmentRuntime = {
|
|
execute: vi.fn().mockResolvedValue({
|
|
exitCode: 0,
|
|
signal: null,
|
|
timedOut: false,
|
|
stdout: "ok",
|
|
stderr: "",
|
|
metadata: { durationMs: 600, getDurationMs: 15 },
|
|
}),
|
|
supportsSync: vi.fn().mockReturnValue(false),
|
|
};
|
|
|
|
const target = await resolveEnvironmentExecutionTarget({
|
|
db: {} as never,
|
|
companyId: "company-1",
|
|
adapterType: "codex_local",
|
|
environment: { id: "env-1", driver: "sandbox", config: { provider: "fake-plugin" } },
|
|
leaseId: "lease-1",
|
|
leaseMetadata: { remoteCwd: "/workspace" },
|
|
lease: { id: "lease-1" } as never,
|
|
environmentRuntime: environmentRuntime as never,
|
|
});
|
|
|
|
const runner = (target as { runner?: {
|
|
supportsSingleStreamStdinProgress?: boolean;
|
|
execute(input: { command: string; args?: string[] }): Promise<unknown>;
|
|
} }).runner;
|
|
expect(runner).toBeTruthy();
|
|
// Provider-backed sandbox RPCs do not surface bounded mid-stream progress
|
|
// for a single stdin upload, so the runner leaves the capability disabled.
|
|
expect(runner!.supportsSingleStreamStdinProgress).toBe(false);
|
|
|
|
// The exec seam still runs each command; the run-log no longer carries the
|
|
// detailed per-step round-trip or provider-duration counts.
|
|
await runner!.execute({ command: "echo", args: ["a"] });
|
|
await runner!.execute({ command: "echo", args: ["b"] });
|
|
expect(environmentRuntime.execute).toHaveBeenCalledTimes(2);
|
|
});
|
|
|
|
it("forwards the session flags to the environment runtime execute", async () => {
|
|
mockResolveEnvironmentDriverConfigForRuntime.mockResolvedValue({
|
|
driver: "sandbox",
|
|
config: {
|
|
provider: "fake-plugin",
|
|
reuseLease: false,
|
|
timeoutMs: 30_000,
|
|
},
|
|
});
|
|
|
|
const environmentRuntime = {
|
|
execute: vi.fn().mockResolvedValue({
|
|
exitCode: 0,
|
|
signal: null,
|
|
timedOut: false,
|
|
stdout: "ok",
|
|
stderr: "",
|
|
metadata: { durationMs: 600, getDurationMs: 15 },
|
|
}),
|
|
supportsSync: vi.fn().mockReturnValue(false),
|
|
};
|
|
|
|
const target = await resolveEnvironmentExecutionTarget({
|
|
db: {} as never,
|
|
companyId: "company-1",
|
|
adapterType: "codex_local",
|
|
environment: { id: "env-1", driver: "sandbox", config: { provider: "fake-plugin" } },
|
|
leaseId: "lease-1",
|
|
leaseMetadata: { remoteCwd: "/workspace" },
|
|
lease: { id: "lease-1" } as never,
|
|
environmentRuntime: environmentRuntime as never,
|
|
});
|
|
|
|
const runner = (target as { runner?: {
|
|
execute(input: {
|
|
command: string;
|
|
args?: string[];
|
|
useSession?: boolean;
|
|
bypassSession?: boolean;
|
|
}): Promise<unknown>;
|
|
} }).runner!;
|
|
|
|
// The agent command opts onto the persistent session with `useSession`,
|
|
// which the seam maps to `forceSession`. It never bypasses the session.
|
|
await runner.execute({ command: "node", args: ["script.js"], useSession: true });
|
|
// A bridge control-plane exec opts off the persistent session with
|
|
// `bypassSession`, which the seam forwards unchanged.
|
|
await runner.execute({ command: "sh", args: ["-c", "cat"], bypassSession: true });
|
|
|
|
const first = environmentRuntime.execute.mock.calls[0]![0] as {
|
|
forceSession?: boolean;
|
|
bypassSession?: boolean;
|
|
};
|
|
expect(first.forceSession).toBe(true);
|
|
expect(first.bypassSession).toBeUndefined();
|
|
|
|
const second = environmentRuntime.execute.mock.calls[1]![0] as {
|
|
forceSession?: boolean;
|
|
bypassSession?: boolean;
|
|
};
|
|
expect(second.forceSession).toBeUndefined();
|
|
expect(second.bypassSession).toBe(true);
|
|
});
|
|
|
|
// A recording tracer that captures each provider-exec span's name, attribute
|
|
// map, and end. It satisfies the structural tracer the seam calls.
|
|
function createRecordingExecTracer() {
|
|
const spans: Array<{
|
|
name: string;
|
|
attributes: Record<string, unknown>;
|
|
status: { code: number; message?: string } | null;
|
|
ended: boolean;
|
|
}> = [];
|
|
const tracer = {
|
|
startSpan(name: string) {
|
|
const span = {
|
|
name,
|
|
attributes: {} as Record<string, unknown>,
|
|
status: null as { code: number; message?: string } | null,
|
|
ended: false,
|
|
setAttribute(key: string, value: unknown) {
|
|
span.attributes[key] = value;
|
|
},
|
|
setStatus(status: { code: number; message?: string }) {
|
|
span.status = status;
|
|
},
|
|
end() {
|
|
span.ended = true;
|
|
},
|
|
};
|
|
spans.push(span);
|
|
return span;
|
|
},
|
|
};
|
|
return { tracer, spans };
|
|
}
|
|
|
|
// The value of `SpanStatusCode.ERROR` in `@opentelemetry/api`. A failed exec
|
|
// span must carry this native status, not only the `failed` outcome attribute.
|
|
const SPAN_STATUS_CODE_ERROR = 2;
|
|
|
|
// The closed span-attribute allowlist for a `sandbox.exec` span. A test
|
|
// asserts every recorded key is in this set, so a command, an argument, a
|
|
// path, an id, or an error-text key can never ride the span.
|
|
const ALLOWED_EXEC_SPAN_ATTRIBUTE_KEYS = new Set<string>([
|
|
A.provider,
|
|
A.execCommand,
|
|
A.execExitCode,
|
|
A.execWallMs,
|
|
A.execWaitBeforeMs,
|
|
A.execSandboxMs,
|
|
A.execNetworkMs,
|
|
A.execCriticalPath,
|
|
A.execCacheHit,
|
|
A.outcome,
|
|
]);
|
|
|
|
async function runnerFor(input: {
|
|
provider: string;
|
|
execResult: Record<string, unknown>;
|
|
tracer: unknown;
|
|
}) {
|
|
return runnerWithExecute({
|
|
provider: input.provider,
|
|
tracer: input.tracer,
|
|
execute: vi.fn().mockResolvedValue(input.execResult),
|
|
});
|
|
}
|
|
|
|
// Build the sandbox runner with a custom provider-exec implementation, so a
|
|
// test can drive a thrown execution or assert the span order around the await.
|
|
async function runnerWithExecute(input: {
|
|
provider: string;
|
|
tracer: unknown;
|
|
execute: (...args: unknown[]) => Promise<unknown>;
|
|
}) {
|
|
mockResolveEnvironmentDriverConfigForRuntime.mockResolvedValue({
|
|
driver: "sandbox",
|
|
config: { provider: input.provider, reuseLease: false, timeoutMs: 30_000 },
|
|
});
|
|
const environmentRuntime = {
|
|
execute: input.execute,
|
|
supportsSync: vi.fn().mockReturnValue(false),
|
|
};
|
|
const target = await resolveEnvironmentExecutionTarget({
|
|
db: {} as never,
|
|
companyId: "company-1",
|
|
adapterType: "codex_local",
|
|
environment: { id: "env-1", driver: "sandbox", config: { provider: input.provider } },
|
|
leaseId: "lease-1",
|
|
leaseMetadata: { remoteCwd: "/workspace" },
|
|
lease: { id: "lease-1" } as never,
|
|
environmentRuntime: environmentRuntime as never,
|
|
tracer: input.tracer as never,
|
|
});
|
|
return (target as { runner?: {
|
|
execute(input: { command: string; args?: string[] }): Promise<unknown>;
|
|
} }).runner!;
|
|
}
|
|
|
|
// Run the sandbox runner's execute with an incremental log sink and collect
|
|
// the ordered deliveries. The runner's execute accepts an `onLog`, so this
|
|
// casts past the narrowed helper return type.
|
|
async function runExecuteCollectingLogs(
|
|
runner: { execute(input: unknown): Promise<unknown> },
|
|
): Promise<Array<[string, string]>> {
|
|
const delivered: Array<[string, string]> = [];
|
|
await runner.execute({
|
|
command: "echo",
|
|
onLog: async (stream: "stdout" | "stderr", chunk: string) => {
|
|
delivered.push([stream, chunk]);
|
|
},
|
|
});
|
|
return delivered;
|
|
}
|
|
|
|
it("delivers only the un-streamed suffix after a provider streams a prefix then polls the complete result", async () => {
|
|
// The provider streams a prefix through the incremental sink, then its
|
|
// stream fails and it polls the complete output as the final result. The
|
|
// reconciler must deliver the remaining tail once, so no output byte is lost
|
|
// or repeated.
|
|
const { tracer } = createRecordingExecTracer();
|
|
const runner = await runnerWithExecute({
|
|
provider: "daytona",
|
|
tracer,
|
|
execute: async (input: unknown) => {
|
|
const typed = input as { onLog?: (s: "stdout" | "stderr", c: string) => Promise<void> };
|
|
await typed.onLog?.("stdout", "hello ");
|
|
await typed.onLog?.("stderr", "warn:");
|
|
return { exitCode: 0, signal: null, timedOut: false, stdout: "hello world", stderr: "warn:done" };
|
|
},
|
|
});
|
|
const delivered = await runExecuteCollectingLogs(
|
|
runner as { execute(input: unknown): Promise<unknown> },
|
|
);
|
|
expect(delivered).toEqual([
|
|
["stdout", "hello "],
|
|
["stderr", "warn:"],
|
|
["stdout", "world"],
|
|
["stderr", "done"],
|
|
]);
|
|
});
|
|
|
|
it("does not repeat output when the provider already streamed the complete result", async () => {
|
|
// The provider streams the whole output through the incremental sink and
|
|
// returns the same complete result. The suffix is empty, so the reconciler
|
|
// never re-delivers the streamed bytes.
|
|
const { tracer } = createRecordingExecTracer();
|
|
const runner = await runnerWithExecute({
|
|
provider: "daytona",
|
|
tracer,
|
|
execute: async (input: unknown) => {
|
|
const typed = input as { onLog?: (s: "stdout" | "stderr", c: string) => Promise<void> };
|
|
await typed.onLog?.("stdout", "full");
|
|
return { exitCode: 0, signal: null, timedOut: false, stdout: "full", stderr: "" };
|
|
},
|
|
});
|
|
const delivered = await runExecuteCollectingLogs(
|
|
runner as { execute(input: unknown): Promise<unknown> },
|
|
);
|
|
expect(delivered).toEqual([["stdout", "full"]]);
|
|
});
|
|
|
|
it("delivers the full captured output when the provider streams nothing incrementally", async () => {
|
|
// The provider streams no incremental chunk, so the whole final result is
|
|
// the suffix and reaches the sink once.
|
|
const { tracer } = createRecordingExecTracer();
|
|
const runner = await runnerWithExecute({
|
|
provider: "daytona",
|
|
tracer,
|
|
execute: async () => ({
|
|
exitCode: 0,
|
|
signal: null,
|
|
timedOut: false,
|
|
stdout: "batch-out",
|
|
stderr: "batch-err",
|
|
}),
|
|
});
|
|
const delivered = await runExecuteCollectingLogs(
|
|
runner as { execute(input: unknown): Promise<unknown> },
|
|
);
|
|
expect(delivered).toEqual([
|
|
["stdout", "batch-out"],
|
|
["stderr", "batch-err"],
|
|
]);
|
|
});
|
|
|
|
it("delivers the whole final output when the poll fallback buffer does not continue the streamed prefix", async () => {
|
|
// The provider streams a prefix, then its stream fails and it polls a
|
|
// buffer that does NOT start with that prefix. A length slice would drop
|
|
// the leading bytes of the poll buffer and corrupt the durable log, so the
|
|
// reconciler delivers the whole final output instead. The streamed prefix
|
|
// repeats, but no output byte is lost or truncated.
|
|
const { tracer } = createRecordingExecTracer();
|
|
const runner = await runnerWithExecute({
|
|
provider: "daytona",
|
|
tracer,
|
|
execute: async (input: unknown) => {
|
|
const typed = input as { onLog?: (s: "stdout" | "stderr", c: string) => Promise<void> };
|
|
await typed.onLog?.("stdout", "hello ");
|
|
await typed.onLog?.("stderr", "warn:");
|
|
// The poll buffer starts with different leading text on both streams.
|
|
return { exitCode: 0, signal: null, timedOut: false, stdout: "RESYNCED output", stderr: "RESET err" };
|
|
},
|
|
});
|
|
const delivered = await runExecuteCollectingLogs(
|
|
runner as { execute(input: unknown): Promise<unknown> },
|
|
);
|
|
expect(delivered).toEqual([
|
|
["stdout", "hello "],
|
|
["stderr", "warn:"],
|
|
["stdout", "RESYNCED output"],
|
|
["stderr", "RESET err"],
|
|
]);
|
|
});
|
|
|
|
it("sets the provider duration attributes from finite Daytona-shaped metadata", async () => {
|
|
const { tracer, spans } = createRecordingExecTracer();
|
|
const runner = await runnerFor({
|
|
provider: "daytona",
|
|
execResult: {
|
|
exitCode: 0,
|
|
signal: null,
|
|
timedOut: false,
|
|
stdout: "ok",
|
|
stderr: "",
|
|
metadata: { durationMs: 600, getDurationMs: 15 },
|
|
},
|
|
tracer,
|
|
});
|
|
|
|
await runner.execute({ command: "echo", args: ["a"] });
|
|
|
|
expect(spans).toHaveLength(1);
|
|
const span = spans[0]!;
|
|
expect(span.name).toBe("sandbox.exec");
|
|
expect(span.ended).toBe(true);
|
|
// `sandbox_ms` = provider in-sandbox run; `wait_before_ms` = handle-fetch.
|
|
expect(span.attributes[A.execSandboxMs]).toBe(600);
|
|
expect(span.attributes[A.execWaitBeforeMs]).toBe(15);
|
|
expect(span.attributes[A.provider]).toBe("daytona");
|
|
// `echo` is a known command basename, so it rides as a clamped label.
|
|
expect(span.attributes[A.execCommand]).toBe("echo");
|
|
expect(span.attributes[A.execExitCode]).toBe(0);
|
|
expect(span.attributes[A.outcome]).toBe("ok");
|
|
// A successful exec leaves the native span status unset (default OTel status).
|
|
expect(span.status).toBeNull();
|
|
expect(span.attributes[A.execCriticalPath]).toBe(true);
|
|
// The wall time is a real, finite, non-negative number.
|
|
expect(typeof span.attributes[A.execWallMs]).toBe("number");
|
|
expect(span.attributes[A.execWallMs] as number).toBeGreaterThanOrEqual(0);
|
|
});
|
|
|
|
it("carries the explicit exec cache_hit from result.metadata.cacheHit", async () => {
|
|
const { tracer, spans } = createRecordingExecTracer();
|
|
const runner = await runnerFor({
|
|
provider: "daytona",
|
|
execResult: {
|
|
exitCode: 0,
|
|
signal: null,
|
|
timedOut: false,
|
|
stdout: "ok",
|
|
stderr: "",
|
|
metadata: { durationMs: 600, getDurationMs: 0, cacheHit: true },
|
|
},
|
|
tracer,
|
|
});
|
|
|
|
await runner.execute({ command: "echo", args: ["a"] });
|
|
|
|
const span = spans[0]!;
|
|
// The flag comes from the metadata boolean, not from a zero handle-fetch.
|
|
expect(span.attributes[A.execCacheHit]).toBe(true);
|
|
});
|
|
|
|
it("omits exec cache_hit when the provider reports no cacheHit metadata", async () => {
|
|
const { tracer, spans } = createRecordingExecTracer();
|
|
const runner = await runnerFor({
|
|
provider: "daytona",
|
|
execResult: {
|
|
exitCode: 0,
|
|
signal: null,
|
|
timedOut: false,
|
|
stdout: "ok",
|
|
stderr: "",
|
|
metadata: { durationMs: 600, getDurationMs: 15 },
|
|
},
|
|
tracer,
|
|
});
|
|
|
|
await runner.execute({ command: "echo", args: ["a"] });
|
|
|
|
const span = spans[0]!;
|
|
// A provider that omits the boolean yields no attribute — never `false`.
|
|
expect(span.attributes).not.toHaveProperty(A.execCacheHit);
|
|
});
|
|
|
|
it("omits each duration attribute when a provider returns no timing (does not throw, keeps provider)", async () => {
|
|
const { tracer, spans } = createRecordingExecTracer();
|
|
const runner = await runnerFor({
|
|
provider: "kubernetes",
|
|
execResult: { exitCode: 0, signal: null, timedOut: false, stdout: "", stderr: "" },
|
|
tracer,
|
|
});
|
|
|
|
await expect(runner.execute({ command: "echo" })).resolves.toBeTruthy();
|
|
|
|
expect(spans).toHaveLength(1);
|
|
const span = spans[0]!;
|
|
expect(A.execSandboxMs in span.attributes).toBe(false);
|
|
expect(A.execWaitBeforeMs in span.attributes).toBe(false);
|
|
// With no provider durations, the derived network time is also omitted.
|
|
expect(A.execNetworkMs in span.attributes).toBe(false);
|
|
// The provider attribute is always present so a trace shows which provider ran.
|
|
expect(span.attributes[A.provider]).toBe("kubernetes");
|
|
});
|
|
|
|
it("never emits a `0` duration attribute for a Daytona timeout that omits durationMs", async () => {
|
|
const { tracer, spans } = createRecordingExecTracer();
|
|
const runner = await runnerFor({
|
|
provider: "daytona",
|
|
execResult: {
|
|
exitCode: 124,
|
|
signal: null,
|
|
timedOut: true,
|
|
stdout: "",
|
|
stderr: "",
|
|
// The Daytona timeout branch may leave durationMs undefined.
|
|
metadata: { getDurationMs: 20 },
|
|
},
|
|
tracer,
|
|
});
|
|
|
|
await runner.execute({ command: "sleep", args: ["999"] });
|
|
|
|
const span = spans[0]!;
|
|
expect(A.execSandboxMs in span.attributes).toBe(false);
|
|
expect(span.attributes[A.execWaitBeforeMs]).toBe(20);
|
|
// A non-zero exit yields `failed`; the exit code rides as a number.
|
|
expect(span.attributes[A.outcome]).toBe("failed");
|
|
// A failed exec also sets the native span status to ERROR.
|
|
expect(span.status).toEqual({ code: SPAN_STATUS_CODE_ERROR });
|
|
expect(span.attributes[A.execExitCode]).toBe(124);
|
|
// `sleep` is not in the known-command allowlist, so it clamps to `other`.
|
|
expect(span.attributes[A.execCommand]).toBe("other");
|
|
});
|
|
|
|
it("never sets a command, arg, env, cwd, or stream text as a span attribute, even with secret-like input", async () => {
|
|
const { tracer, spans } = createRecordingExecTracer();
|
|
const runner = await runnerFor({
|
|
provider: "daytona",
|
|
execResult: {
|
|
exitCode: 0,
|
|
signal: null,
|
|
timedOut: false,
|
|
// Secret-like standard-stream text must never ride the span.
|
|
stdout: "AKIAIOSFODNN7EXAMPLE token=s3cr3t-stdout",
|
|
stderr: "error at /home/agent/.ssh/id_rsa: s3cr3t-stderr",
|
|
metadata: { durationMs: 5, getDurationMs: 1 },
|
|
},
|
|
tracer,
|
|
});
|
|
|
|
await runner.execute({
|
|
// A full command line, a secret-like argument, a secret-like env value, a
|
|
// stdin blob, and a path-like cwd — none may ride the span.
|
|
command: "bash -lc 'rm -rf /secret/path'",
|
|
args: ["--token", "s3cr3t-arg", "--password", "hunter2"],
|
|
env: { AWS_SECRET_ACCESS_KEY: "s3cr3t-env", HOME: "/home/agent" },
|
|
cwd: "/home/agent/secret-workspace/.git",
|
|
stdin: "s3cr3t-stdin-blob",
|
|
});
|
|
|
|
const span = spans[0]!;
|
|
for (const key of Object.keys(span.attributes)) {
|
|
expect(ALLOWED_EXEC_SPAN_ATTRIBUTE_KEYS.has(key), `non-allowlisted key "${key}"`).toBe(true);
|
|
}
|
|
// The command clamps to the bounded `other` fallback (not a known basename).
|
|
expect(span.attributes[A.execCommand]).toBe("other");
|
|
// No forbidden substring rides any attribute value.
|
|
const values = Object.values(span.attributes).map(String);
|
|
for (const forbidden of [
|
|
"rm -rf",
|
|
"s3cr3t",
|
|
"hunter2",
|
|
"AKIA",
|
|
"id_rsa",
|
|
"/secret/path",
|
|
"/home/agent",
|
|
"secret-workspace",
|
|
"stdin",
|
|
]) {
|
|
expect(
|
|
values.some((value) => value.includes(forbidden)),
|
|
`attribute value leaked "${forbidden}"`,
|
|
).toBe(false);
|
|
}
|
|
});
|
|
|
|
it("normalizes a plugin-backed provider key to `plugin` and keeps a built-in family as-is", async () => {
|
|
const plugin = createRecordingExecTracer();
|
|
const pluginRunner = await runnerFor({
|
|
provider: "acme-custom-sandbox",
|
|
execResult: { exitCode: 0, signal: null, timedOut: false, stdout: "", stderr: "" },
|
|
tracer: plugin.tracer,
|
|
});
|
|
await pluginRunner.execute({ command: "echo" });
|
|
expect(plugin.spans[0]!.attributes[A.provider]).toBe("plugin");
|
|
|
|
const builtIn = createRecordingExecTracer();
|
|
const builtInRunner = await runnerFor({
|
|
provider: "e2b",
|
|
execResult: { exitCode: 0, signal: null, timedOut: false, stdout: "", stderr: "" },
|
|
tracer: builtIn.tracer,
|
|
});
|
|
await builtInRunner.execute({ command: "echo" });
|
|
expect(builtIn.spans[0]!.attributes[A.provider]).toBe("e2b");
|
|
});
|
|
|
|
it("parents the exec span to the active step span when the exec runs inside a measured step", async () => {
|
|
const { tracer, contextWithSpan, spans } = createRecordingTrace();
|
|
const runner = await runnerFor({
|
|
provider: "daytona",
|
|
execResult: { exitCode: 0, signal: null, timedOut: false, stdout: "", stderr: "" },
|
|
tracer,
|
|
});
|
|
|
|
// The exec seam reads the active step context through `getActiveStepContext`.
|
|
// Wrap the exec in one measured step and assert the exec span parents to the
|
|
// step span, not to nothing.
|
|
await measureStartupStep({}, () => 0, "stage.sync", () => runner.execute({ command: "echo" }), {
|
|
tracer,
|
|
contextWithSpan,
|
|
});
|
|
|
|
const stepSpan = spans.find((span) => span.name === "stage.sync");
|
|
const execSpan = spans.find((span) => span.name === "sandbox.exec");
|
|
expect(stepSpan).toBeTruthy();
|
|
expect(execSpan).toBeTruthy();
|
|
expect(execSpan!.parent).toBe(stepSpan);
|
|
});
|
|
|
|
it("opens an unparented exec span when the exec runs outside any measured step", async () => {
|
|
const { tracer, spans } = createRecordingTrace();
|
|
const runner = await runnerFor({
|
|
provider: "daytona",
|
|
execResult: { exitCode: 0, signal: null, timedOut: false, stdout: "", stderr: "" },
|
|
tracer,
|
|
});
|
|
|
|
// No measured step wraps the exec, so the active step context is null and
|
|
// the exec span opens unparented (a no-op when tracing is off).
|
|
await runner.execute({ command: "echo" });
|
|
|
|
const execSpan = spans.find((span) => span.name === "sandbox.exec");
|
|
expect(execSpan).toBeTruthy();
|
|
expect(execSpan!.parent).toBeNull();
|
|
});
|
|
|
|
// The three baseline tests below record the third `startSpan` argument — the
|
|
// parent-context token — and assert its identity. They pin the current exec
|
|
// parenting so a later phase that re-points the exec parent has a fixed
|
|
// reference point.
|
|
it("test_exec_inside_measured_step_parents_to_step_context", async () => {
|
|
const rec = recordParentContext();
|
|
const runner = await runnerFor({
|
|
provider: "daytona",
|
|
execResult: { exitCode: 0, signal: null, timedOut: false, stdout: "", stderr: "" },
|
|
tracer: rec.tracer,
|
|
});
|
|
|
|
// Run the seam `execute` inside one measured step. The step publishes its
|
|
// child context to the active step store, so the seam reads it and passes it
|
|
// as the third `startSpan` argument for the exec span.
|
|
await measureStartupStep({}, () => 0, "stage.sync", () => runner.execute({ command: "echo" }), {
|
|
tracer: rec.tracer,
|
|
contextWithSpan: rec.contextWithSpan,
|
|
});
|
|
|
|
const stepSpan = rec.spanNamed("stage.sync");
|
|
expect(stepSpan).toBeTruthy();
|
|
// The exec span parents to the step span. The third `startSpan` argument is
|
|
// the exact parent-context token that `contextWithSpan` built for the step
|
|
// span, not a rebuilt copy.
|
|
expect(rec.parentContextFor("sandbox.exec")).toBe(rec.tokenForSpan(stepSpan));
|
|
});
|
|
|
|
it("test_exec_in_root_region_is_unparented_today", async () => {
|
|
const rec = recordParentContext();
|
|
const runner = await runnerFor({
|
|
provider: "daytona",
|
|
execResult: { exitCode: 0, signal: null, timedOut: false, stdout: "", stderr: "" },
|
|
tracer: rec.tracer,
|
|
});
|
|
|
|
// No measured step wraps the exec, so the active step store is empty. The
|
|
// seam reads no parent and passes `undefined` as the third `startSpan`
|
|
// argument. The exec span opens unparented today.
|
|
await runner.execute({ command: "echo" });
|
|
|
|
expect(rec.spanNamed("sandbox.exec")).toBeTruthy();
|
|
expect(rec.parentContextFor("sandbox.exec")).toBeUndefined();
|
|
});
|
|
|
|
it("test_exec_on_runWithoutActiveStep_is_unparented_today", async () => {
|
|
const rec = recordParentContext();
|
|
const runner = await runnerFor({
|
|
provider: "daytona",
|
|
execResult: { exitCode: 0, signal: null, timedOut: false, stdout: "", stderr: "" },
|
|
tracer: rec.tracer,
|
|
});
|
|
|
|
// `runWithoutActiveStep` empties the active step store for the wrapped work.
|
|
// The seam reads no parent and passes `undefined` as the third `startSpan`
|
|
// argument. The exec span opens unparented today.
|
|
await runWithoutActiveStep(() => runner.execute({ command: "echo" }));
|
|
|
|
expect(rec.spanNamed("sandbox.exec")).toBeTruthy();
|
|
expect(rec.parentContextFor("sandbox.exec")).toBeUndefined();
|
|
});
|
|
|
|
it("opens the exec span before the provider await so the span wraps the execution", async () => {
|
|
const { tracer, spans } = createRecordingExecTracer();
|
|
// Assert the span is already open (started, not ended) while the provider
|
|
// runs. If the seam opened the span after the await, no open span would
|
|
// exist here and the native span duration would be near zero.
|
|
const runner = await runnerWithExecute({
|
|
provider: "daytona",
|
|
tracer,
|
|
execute: vi.fn().mockImplementation(async () => {
|
|
const open = spans.find((span) => span.name === "sandbox.exec");
|
|
expect(open, "the exec span must be open during the provider await").toBeTruthy();
|
|
expect(open!.ended).toBe(false);
|
|
return { exitCode: 0, signal: null, timedOut: false, stdout: "", stderr: "" };
|
|
}),
|
|
});
|
|
|
|
await runner.execute({ command: "echo" });
|
|
|
|
const span = spans.find((s) => s.name === "sandbox.exec");
|
|
expect(span!.ended).toBe(true);
|
|
expect(span!.attributes[A.outcome]).toBe("ok");
|
|
});
|
|
|
|
it("records a failed exec span and rethrows when the provider execution throws", async () => {
|
|
const { tracer, spans } = createRecordingExecTracer();
|
|
const runner = await runnerWithExecute({
|
|
provider: "daytona",
|
|
tracer,
|
|
execute: vi.fn().mockRejectedValue(new Error("provider transport failed")),
|
|
});
|
|
|
|
// The original error rides through unchanged; observability never swallows it.
|
|
await expect(runner.execute({ command: "echo" })).rejects.toThrow("provider transport failed");
|
|
|
|
// A thrown execution still produces one ended span with the `failed` outcome,
|
|
// instead of no span at all.
|
|
const span = spans.find((s) => s.name === "sandbox.exec");
|
|
expect(span).toBeTruthy();
|
|
expect(span!.ended).toBe(true);
|
|
expect(span!.attributes[A.outcome]).toBe("failed");
|
|
// A thrown execution also sets the native span status to ERROR.
|
|
expect(span!.status).toEqual({ code: SPAN_STATUS_CODE_ERROR });
|
|
expect(span!.attributes[A.provider]).toBe("daytona");
|
|
// `echo` is a known basename, so the clamped command rides the span.
|
|
expect(span!.attributes[A.execCommand]).toBe("echo");
|
|
// No exec result exists, so the exit code never rides the span.
|
|
expect(A.execExitCode in span!.attributes).toBe(false);
|
|
// The wall time is a real, finite, non-negative number.
|
|
expect(typeof span!.attributes[A.execWallMs]).toBe("number");
|
|
expect(span!.attributes[A.execWallMs] as number).toBeGreaterThanOrEqual(0);
|
|
// Only allowlisted keys ride the failed span.
|
|
for (const key of Object.keys(span!.attributes)) {
|
|
expect(ALLOWED_EXEC_SPAN_ATTRIBUTE_KEYS.has(key), `non-allowlisted key "${key}"`).toBe(true);
|
|
}
|
|
});
|
|
|
|
it("keeps the exec span outcome `ok` when the execution succeeds but a log callback rejects", async () => {
|
|
const { tracer, spans } = createRecordingExecTracer();
|
|
// The provider execution succeeds and returns stdout, so the seam invokes
|
|
// the log callback. The callback rejects, which models a downstream log-sink
|
|
// failure. The rejection must reach the caller, but it must never reclassify
|
|
// the successful execution as a failed span.
|
|
const runner = await runnerWithExecute({
|
|
provider: "daytona",
|
|
tracer,
|
|
execute: vi.fn().mockResolvedValue({
|
|
exitCode: 0,
|
|
signal: null,
|
|
timedOut: false,
|
|
stdout: "hello",
|
|
stderr: "",
|
|
}),
|
|
});
|
|
|
|
const onLog = vi.fn().mockRejectedValue(new Error("log sink rejected"));
|
|
// The rejection rides through unchanged; observability never swallows it.
|
|
await expect(
|
|
(runner as { execute(input: unknown): Promise<unknown> }).execute({ command: "echo", onLog }),
|
|
).rejects.toThrow("log sink rejected");
|
|
|
|
// The span ended with the successful outcome from the command result, not
|
|
// the failed outcome. A log failure never marks the execution failed.
|
|
const span = spans.find((s) => s.name === "sandbox.exec");
|
|
expect(span).toBeTruthy();
|
|
expect(span!.ended).toBe(true);
|
|
expect(span!.attributes[A.outcome]).toBe("ok");
|
|
// A log-callback rejection never marks the span as ERROR; the status stays unset.
|
|
expect(span!.status).toBeNull();
|
|
expect(span!.attributes[A.execExitCode]).toBe(0);
|
|
// The seam reached the log callback exactly once (the stdout delivery).
|
|
expect(onLog).toHaveBeenCalledTimes(1);
|
|
});
|
|
|
|
it("delivers incremental logs before the final result and does not duplicate them", async () => {
|
|
const { tracer } = createRecordingExecTracer();
|
|
const runner = await runnerWithExecute({
|
|
provider: "daytona",
|
|
tracer,
|
|
execute: vi.fn(async (input: { onLog?: (s: string, c: string) => Promise<void> }) => {
|
|
// The provider streams the output while the command runs.
|
|
await input.onLog?.("stdout", "chunk-1");
|
|
await input.onLog?.("stderr", "chunk-2");
|
|
await input.onLog?.("stdout", "chunk-3");
|
|
return {
|
|
exitCode: 0,
|
|
signal: null,
|
|
timedOut: false,
|
|
stdout: "chunk-1chunk-3",
|
|
stderr: "chunk-2",
|
|
};
|
|
}),
|
|
});
|
|
|
|
const onLog = vi.fn();
|
|
const result = await (runner as {
|
|
execute(input: unknown): Promise<{ stdout: string; stderr: string; exitCode: number }>;
|
|
}).execute({ command: "echo", onLog });
|
|
|
|
// The runner receives the incremental chunks in order, and NOT a repeated
|
|
// delivery of the final stdout/stderr.
|
|
expect(onLog.mock.calls).toEqual([
|
|
["stdout", "chunk-1"],
|
|
["stderr", "chunk-2"],
|
|
["stdout", "chunk-3"],
|
|
]);
|
|
// The final result stays available to the caller for parsing and fallback.
|
|
expect(result).toMatchObject({ exitCode: 0, stdout: "chunk-1chunk-3", stderr: "chunk-2" });
|
|
});
|
|
|
|
it("still delivers the final result to the runner when the provider does not stream", async () => {
|
|
const { tracer } = createRecordingExecTracer();
|
|
const runner = await runnerWithExecute({
|
|
provider: "daytona",
|
|
tracer,
|
|
// A provider that never calls onLog returns only the final result.
|
|
execute: vi.fn(async () => ({
|
|
exitCode: 0,
|
|
signal: null,
|
|
timedOut: false,
|
|
stdout: "final-out",
|
|
stderr: "final-err",
|
|
})),
|
|
});
|
|
|
|
const onLog = vi.fn();
|
|
const result = await (runner as {
|
|
execute(input: unknown): Promise<{ stdout: string; stderr: string }>;
|
|
}).execute({ command: "echo", onLog });
|
|
|
|
expect(onLog.mock.calls).toEqual([
|
|
["stdout", "final-out"],
|
|
["stderr", "final-err"],
|
|
]);
|
|
expect(result).toMatchObject({ stdout: "final-out", stderr: "final-err" });
|
|
});
|
|
|
|
it("creates exactly one sandbox.exec span for one streamed provider call", async () => {
|
|
const { tracer, spans } = createRecordingExecTracer();
|
|
const runner = await runnerWithExecute({
|
|
provider: "daytona",
|
|
tracer,
|
|
execute: vi.fn(async (input: { onLog?: (s: string, c: string) => Promise<void> }) => {
|
|
await input.onLog?.("stdout", "chunk-a");
|
|
await input.onLog?.("stdout", "chunk-b");
|
|
await input.onLog?.("stderr", "chunk-c");
|
|
return {
|
|
exitCode: 0,
|
|
signal: null,
|
|
timedOut: false,
|
|
stdout: "chunk-achunk-b",
|
|
stderr: "chunk-c",
|
|
};
|
|
}),
|
|
});
|
|
|
|
const onLog = vi.fn();
|
|
await (runner as { execute(input: unknown): Promise<unknown> }).execute({
|
|
command: "echo",
|
|
onLog,
|
|
});
|
|
|
|
// One long-lived provider call opens one span; each stream chunk opens none.
|
|
expect(spans).toHaveLength(1);
|
|
expect(spans[0]!.name).toBe("sandbox.exec");
|
|
expect(spans[0]!.ended).toBe(true);
|
|
});
|
|
|
|
it("keeps streamed log text and secret values out of span attributes", async () => {
|
|
const { tracer, spans } = createRecordingExecTracer();
|
|
const secret = "sk-super-secret-value";
|
|
const runner = await runnerWithExecute({
|
|
provider: "daytona",
|
|
tracer,
|
|
execute: vi.fn(async (input: { onLog?: (s: string, c: string) => Promise<void> }) => {
|
|
await input.onLog?.("stdout", `token=${secret}\n`);
|
|
return {
|
|
exitCode: 0,
|
|
signal: null,
|
|
timedOut: false,
|
|
stdout: `token=${secret}\n`,
|
|
stderr: "",
|
|
};
|
|
}),
|
|
});
|
|
|
|
const onLog = vi.fn();
|
|
// The secret rides the env and the streamed chunk, never the command label.
|
|
await (runner as { execute(input: unknown): Promise<unknown> }).execute({
|
|
command: "run-agent",
|
|
env: { API_KEY: secret },
|
|
onLog,
|
|
});
|
|
|
|
expect(spans).toHaveLength(1);
|
|
const span = spans[0]!;
|
|
// Attributes carry only the closed allowlist — never log text or secrets.
|
|
for (const key of Object.keys(span.attributes)) {
|
|
expect(ALLOWED_EXEC_SPAN_ATTRIBUTE_KEYS.has(key), `non-allowlisted key "${key}"`).toBe(true);
|
|
}
|
|
const serialized = JSON.stringify(span.attributes);
|
|
expect(serialized).not.toContain(secret);
|
|
expect(serialized).not.toContain("token=");
|
|
expect(serialized).not.toContain("chunk");
|
|
});
|
|
|
|
// Fire one run-time exec from a bridge continuation that runs after the step
|
|
// span ended. Each bridge step (`bridge.paperclip`, `bridge.process-session`)
|
|
// starts long-lived work with `criticalPath: false`. The bridge boundary wraps
|
|
// that long-lived work in `runWithoutActiveStep`, exactly as modeled here, so
|
|
// the continuation reads an empty active step. Return the recorded exec span.
|
|
async function runContinuationExec(step: string, options: { wrap: boolean }) {
|
|
const { tracer, contextWithSpan, spans } = createRecordingTrace();
|
|
const runner = await runnerFor({
|
|
provider: "daytona",
|
|
execResult: { exitCode: 0, signal: null, timedOut: false, stdout: "", stderr: "" },
|
|
tracer,
|
|
});
|
|
|
|
let resolveExec!: () => void;
|
|
const execDone = new Promise<void>((resolve) => {
|
|
resolveExec = resolve;
|
|
});
|
|
|
|
// Schedule the exec from a timer inside the step body, so it fires after the
|
|
// step span ends. The `wrap` flag models the fix: when true, the boundary
|
|
// wraps the long-lived work in `runWithoutActiveStep`; when false, it models
|
|
// the pre-fix leak.
|
|
const scheduleContinuation = () => {
|
|
setTimeout(() => {
|
|
void runner.execute({ command: "echo" }).then(() => resolveExec());
|
|
}, 0);
|
|
};
|
|
|
|
await measureStartupStep(
|
|
{},
|
|
() => 0,
|
|
step,
|
|
async () => {
|
|
if (options.wrap) {
|
|
runWithoutActiveStep(scheduleContinuation);
|
|
} else {
|
|
scheduleContinuation();
|
|
}
|
|
return "started";
|
|
},
|
|
{ tracer, contextWithSpan, criticalPath: false },
|
|
);
|
|
|
|
await execDone;
|
|
return spans.find((span) => span.name === "sandbox.exec");
|
|
}
|
|
|
|
it("opens an unparented exec span for a process-session bridge continuation", async () => {
|
|
const execSpan = await runContinuationExec("bridge.process-session", { wrap: true });
|
|
expect(execSpan).toBeTruthy();
|
|
// The step span ended and the boundary emptied the store, so the continuation
|
|
// exec opens a root span, not one under the dead bridge step.
|
|
expect(execSpan!.parent).toBeNull();
|
|
});
|
|
|
|
it("opens an unparented exec span for a paperclip bridge continuation", async () => {
|
|
const execSpan = await runContinuationExec("bridge.paperclip", { wrap: true });
|
|
expect(execSpan).toBeTruthy();
|
|
expect(execSpan!.parent).toBeNull();
|
|
});
|
|
|
|
it("does not copy the stale criticalPath = false flag onto a continuation exec", async () => {
|
|
const execSpan = await runContinuationExec("bridge.process-session", { wrap: true });
|
|
expect(execSpan).toBeTruthy();
|
|
// The bridge step set `criticalPath: false`. The continuation reads an empty
|
|
// store, so the exec span records the default `true`, never the stale `false`.
|
|
expect(execSpan!.attributes[A.execCriticalPath]).toBe(true);
|
|
expect(execSpan!.attributes[A.execCriticalPath]).not.toBe(false);
|
|
});
|
|
|
|
it("leaks the ended step onto a continuation exec without the boundary wrap", async () => {
|
|
// The mechanism guard: an unwrapped continuation keeps the ended bridge step
|
|
// store, so the exec span parents to the dead step and copies its
|
|
// `criticalPath: false`. The boundary wrap in the two tests above removes both
|
|
// defects, so this suite fails if a future edit drops the wrap.
|
|
const { tracer, contextWithSpan, spans } = createRecordingTrace();
|
|
const runner = await runnerFor({
|
|
provider: "daytona",
|
|
execResult: { exitCode: 0, signal: null, timedOut: false, stdout: "", stderr: "" },
|
|
tracer,
|
|
});
|
|
|
|
let resolveExec!: () => void;
|
|
const execDone = new Promise<void>((resolve) => {
|
|
resolveExec = resolve;
|
|
});
|
|
|
|
await measureStartupStep(
|
|
{},
|
|
() => 0,
|
|
"bridge.process-session",
|
|
async () => {
|
|
setTimeout(() => {
|
|
void runner.execute({ command: "echo" }).then(() => resolveExec());
|
|
}, 0);
|
|
return "started";
|
|
},
|
|
{ tracer, contextWithSpan, criticalPath: false },
|
|
);
|
|
|
|
await execDone;
|
|
|
|
const stepSpan = spans.find((span) => span.name === "bridge.process-session");
|
|
const execSpan = spans.find((span) => span.name === "sandbox.exec");
|
|
expect(stepSpan).toBeTruthy();
|
|
expect(execSpan).toBeTruthy();
|
|
// The unwrapped continuation parents the exec span to the ended step and
|
|
// copies the stale flag.
|
|
expect(execSpan!.parent).toBe(stepSpan);
|
|
expect(execSpan!.attributes[A.execCriticalPath]).toBe(false);
|
|
});
|
|
});
|