mirror of
https://github.com/paperclipai/paperclip.git
synced 2026-10-11 23:36:51 +02:00
b67dced1bfe7a60677b1f435d51fcdbd89cd02dd
12
Commits
| Author | SHA1 | Message | Date | |
|---|---|---|---|---|
 TonioandClaude Opus 5 |
ac91b7f3b2 |
fix(ui): scope the company selection to the signed-in account (#11430)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work > - Every company-scoped screen reads the active company from `CompanyProvider`, which picks one from the `["companies"]` list and remembers it in localStorage > - That cache entry is shared app-wide and carries no account identity, so it survives a change of account in the tab > - The provider therefore auto-selects from whatever list is cached, which can belong to the account that just went away > - This pull request makes the provider watch the account and refuse to derive a selection from a list fetched for a different one > - The benefit is that the app stops pointing at a company the signed-in account may not be able to see ## Linked Issues or Issue Description No public issue exists. Refs #11380, #11382, #11417. The problem follows. **What happened?** `CompanyProvider` auto-selects a company from the shared `["companies"]` cache entry and writes that id to `localStorage`. Nothing ties that entry to an account. When the account changes in the tab, the previous account's list is still served, so the provider can select — and persist — a company belonging to the account that just went away. Company-scoped screens then render against a company the current account may not be able to see. Signing in through `Auth.tsx` invalidates the entry, so the in-app sign-in path is covered. Two paths are not: a session that lapses server-side, and a second account signing in on another tab. The sign-out sweep in #11380 does not cover them either, because neither presses the sign-out button. **Expected behavior** The company selection is derived only from a company list fetched for the account that is signed in now. **Steps to reproduce** 1. On a self-hosted instance in `authenticated` mode, sign in as account A, which belongs to company X. 2. In a second tab, sign in as account B, which does not belong to company X. 3. Return to the first tab. The session query refetches and reports account B, while the company list is still account A's. 4. The provider keeps company X selected and leaves its id in `localStorage`. **Paperclip version or commit** `master` at `6542ad1f4`. ## What Changed - `ui/src/context/CompanyContext.tsx` — the provider observes `queryKeys.auth.session`. On a change of session user it clears the live selection, removes the shared company list, and holds auto-select until a list fetched for the new account lands. The stored id is left alone on purpose: `resolveBootstrapCompanySelection` re-validates it, so an account signing back in keeps its company while an unrelated account cannot inherit it. - `ui/src/context/CompanyContext.tsx` — an errored list is treated as undecided rather than as "no companies". With `retry: false` a single network blip sticks, and the empty-list branch read it as proof the account owns nothing and cleared the stored selection. - `ui/src/api/client.ts` — new `detachInflightGet(path)`. GET coalescing keys on the request path alone, so a `/companies` request issued under the previous session could be joined by the replacement fetch and answer it with the previous account's companies. Detaching leaves that request to settle for its own callers and makes the next call issue a fresh one. - `ui/src/api/companies.ts` — `companiesApi.detachInflightList()` wraps that for the list path. - `ui/src/context/CompanyContext.tsx` — `companyListUnavailable` separates "no usable list because a request failed" from "this account owns nothing", and `retryCompanies` gives a recovery action that fetches. Both are derived from the query rather than tracked beside it; a second copy of "did the last attempt succeed" drifted out of step during review, reporting a failure over a later empty list that was simply the truth. - `ui/src/components/SidebarCompanyMenu.tsx` — renders "Couldn't load companies" and a Try again item in place of "No companies", which is a claim about the account that a failed request cannot support. This is the menu `Sidebar` mounts, so it is the only place a customer can act on the failure. - `ui/src/components/CompanySwitcher.tsx` — the same treatment. The application does not render this component (its only mount is a Storybook story), so it is kept in step rather than relied on. - `ui/src/context/CompanyContext.test.tsx`, `ui/src/components/SidebarCompanyMenu.test.tsx`, `ui/src/api/client.test.ts` — coverage for the account switch, a same-account re-observation not churning, the detached GET, the failed replacement and its recovery, a single blip self-healing, unavailability not outliving the failure, and the sidebar rendering the recovery action for a failure but plain "No companies" for an account that owns nothing. ### No `retry` override on the replacement fetch The obvious fix for a failed replacement is a retry, and it is not load-bearing here. A transient failure already gets a second attempt: the observer rebinds to a fresh query on the render those state updates schedule, and issues its own request — measured as two attempts with or without the option. Retries would only add failed round trips before a real outage is reported, and the outage is what needs a way out, which is what `companyListUnavailable` and `retryCompanies` provide. ### Why `removeQueries` here, and why that does not generalise Removal notifies no observer. What rebinds them at this call site is the render the surrounding state updates schedule; every observer re-binds to a fresh query on the next render. A caller without that guarantee would leave mounted observers serving the previous account's value, so this is not a pattern to lift elsewhere — the sign-out sweep in #11380 must use `resetQueries` instead, and its measurements are at [#11380](https://github.com/paperclipai/paperclip/pull/11380#issuecomment-5300984911). The inverse caveat holds for a local reset under an observer that stays mounted, which is why #11417 and #11382 avoid `resetQueries`. ## Verification - `pnpm vitest run` in `ui`: **4014 passed, 1 failed**. - `pnpm tsc -b` in `ui`: clean. - `CompanyContext.test.tsx`: 16 passed. `SidebarCompanyMenu.test.tsx`: 15 passed. `client.test.ts`: 9 passed. The failure is pre-existing and unrelated: `IssueProperties.test.tsx` expects `4:08 PM` and gets `9:08 AM`, a timezone-dependent assertion. It reproduces on a tree without this change, and #11478 fixes it. Each new test was confirmed to fail against the implementation it covers, by reverting that change and re-running rather than by assuming. The account-switch test fails without the fix (the selection stays on the previous account's company and no refetch is issued); the flag-clearing test fails without its clause (an empty list keeps reading as "couldn't load"). **Not done:** no manual two-account run in a browser. The path needs two accounts on an `authenticated` instance, which a local dev instance cannot exercise. ## Risks Low. The failure direction is a company selection withheld for one extra round trip, which resolves when the list arrives. The direction it removes is one account's company selected and persisted for another. It adds one company-list request per account change, on a query key the app already uses. It adds no request at boot: the session query it observes is already fetched app-wide. **This does not close the class.** Company-scoped entries other than the list — `["companies", id]`, stats, and the rest of the per-account cache — still survive an account change. That is the cache-lifetime work in #11380, not this provider's. ## Model Used Claude Opus 5 (`claude-opus-5`), through Claude Code. Extended thinking enabled. Tool use enabled: file read and edit, shell for typecheck and test runs, and a scratch vitest harness to measure `removeQueries` and `resetQueries` notification behaviour against the installed `@tanstack/query-core` 5.101.4. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge 🤖 Generated with [Claude Code](https://claude.com/claude-code) --------- Co-authored-by: Claude Opus 5 <noreply@anthropic.com> |
||
|
Devin Foley
|
0a95ada1be |
feat(server): chunked import preview endpoint and resumable upload in the Import page and CLI (#11224)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work > - The previous pull request added server-side chunked resumable import transfers; without clients, large imports still ride the single fragile upload > - The Import page and the CLI need to slice large packages, upload parts with retry and progress, resume after interruptions, and preview before applying > - Preview is the missing server piece: the browser flow is preview-then-import, so a completed spool must be previewable without re-uploading > - This pull request adds the transfer preview endpoint, switches the Import page to the chunked path for zips over 48 MB, and teaches the CLI the same for oversized local imports > - The benefit is that large imports get progress, per-part retry, and resume in both clients, while small imports keep the exact single-shot path they have today ## Linked Issues or Issue Description **What happened?** With only the server transfer routes in place, users still upload large company packages as one request from the Import page and the CLI: no progress indication, no retry below the whole file, and no resume after a dropped connection or refresh. The preview-then-import flow also cannot run against an uploaded transfer, forcing a second full upload. **Expected behavior** A large package uploads once as verified parts with visible progress; preview and import both run against the uploaded spool; an interrupted upload resumes with only the missing parts re-sent; packages at or below 48 MB behave exactly as before. **Steps to reproduce** 1. Select a 500 MB zip on the Import page over an unreliable connection. 2. Watch the single upload fail near the end and restart from zero, twice — once for preview, once for import. 3. Same story headless via the CLI. ## What Changed - Server: `POST /import/transfers/:id/preview` runs the existing preview logic against the completed spool (shared assembly + whole-file verification helper with apply); preview neither completes the run nor deletes the spool, so the subsequent apply reuses it. Missing parts respond with the missing list. - UI: zips over 48 MB take the chunked path in both preview and import — the file is sliced into 32 MB parts hashed with WebCrypto (single ArrayBuffer, no second copy), the transfer is created or resumed (the create response's missing-parts list drives what uploads), parts upload sequentially with three attempts each and visible progress, then transfer preview/apply replace the multipart calls. The existing preview pane, collision handling, adapter overrides, and async job polling are unchanged; ≤ 48 MB keeps the single-shot path. - CLI: oversized local `.zip` or folder imports zip/slice/hash with node crypto, upload with resume and per-part retry and progress lines, and use transfer preview/apply. Small packages keep the inline path byte-identical. - Failure honesty: adapters/API errors fail open to existing behavior; a part failing all attempts surfaces a durable error panel with resume intact. ## Verification - Server: preview-then-apply on one spool (run stays open, spool intact, then apply completes), preview with missing parts rejected — added to the transfer route suite (embedded Postgres). - UI suite: large file takes the chunked path (manifest shape, part uploads, progress, apply on a resumed transfer, single-shot endpoints never called), small file stays single-shot, part failure after three attempts surfaces the error panel without running preview, resume re-uploads only the missing part. - CLI: manifest slicing/hashing, threshold behavior for zip and folder sources, folder-zip round-trip through the real zip reader, upload resume/retry/exhaustion/already-completed, full-command chunked and small-zip inline flows. - Server, ui, cli typechecks clean. Exact counts in the PR checks. ## Risks - The 48 MB threshold only routes between two verified paths; behavior below it is untouched. - Chunked CLI imports use the board-scoped transfer routes, so oversized CLI imports need board credentials (agent tokens keep the agent-safe small-file path). No privilege change — board actors already had the generic routes — but the two size regimes differ semantically; called out for review. - A CLI dry-run over the threshold uploads parts before previewing; the spool persists (24 h sweep) and a later apply resumes without re-upload — inherent to preview-against-spool. Stacked on #11223 — merge that first; this PR then shows only the preview endpoint and client changes. ## Model Used - Claude Fable 5 (`claude-fable-5`) via Claude Code CLI, with extended thinking and tool use (multi-agent implementation with independent verification). ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [ ] All Paperclip CI gates are green - [ ] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge |
||
|
Devin Foley
|
5ec7ce76e5 |
Upload company import packages as compressed zip uploads (fix large-company imports through Cloud) (#10531)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work > - Company Import (#10507, hardened in #10523) lets a user upload a company package on the Import page > - The page expanded the user's `.zip` into a files map and POSTed it as ONE inline JSON body — ~40MB for a real company because attachment blobs get base64-inflated > - On Paperclip Cloud that body travels browser → harness proxy → tenant, where it truncated in transit → body-parser 400 → the browser saw "Failed to fetch", and nothing imported > - Two compounding causes: the giant inline body itself, and the board async opt-in riding an `x-paperclip-cloud-*` header that the Cloud harness strips as anti-spoofing (so async never engaged and the import held one fragile synchronous connection) > - This pull request uploads the raw compressed `.zip` as a multipart request (about a third the size, already compressed) parsed server-side into the same bundle the importer consumes, and moves the async opt-in to a proxy-safe `?async=1` > - The benefit is that a large-company import actually completes through Cloud: a small compressed upload, a real async job that survives dropped connections ## Linked Issues or Issue Description - Refs #10507 / #10523 (Import/Export and its hardening). No open issue; problem described above (large-company browser import through a proxy: inline JSON body truncates → 400 → "Failed to fetch"; async opt-in header stripped by the front door → async never engages). ## What Changed - **Multipart zip transport.** The Import page uploads the raw `File` as `multipart/form-data` (field `package`, import options in a JSON `meta` field); the server unzips it into `{ rootPath, files }` and runs the exact existing preview/import logic. The `application/json` inline path is byte-identical for CLI/programmatic callers. Bare `application/zip` (meta via `?meta=`) is also accepted for programmatic use. - **Shared node zip reader.** `packages/shared/src/portability-zip.ts` (node-only subpath, not re-exported to the browser bundle — same pattern as `portability-hash.ts`); the CLI's `zip.ts` becomes a thin re-export. Identical codec (STORE + DEFLATE via `inflateRawSync`, rejects data descriptors/zip64). - **Proxy-safe async signal.** `wantsAsyncImport` = `?async=1` (board browsers, survives the harness) OR the existing `x-paperclip-cloud-async-import` header (cloud tenants, set server-side). The UI async client now uses `?async=1`. Backward compatible. - **Size + preflight.** New `PORTABLE_ZIP_UPLOAD_LIMIT_BYTES = 128MB`; the inline 56MB preflight no longer gates the zip path (it shows the compressed size instead). Async submit/poll/resume, the duplicate-guard fingerprint (now over the resolved bundle), pause-on-import, progress/error panels, and activation all apply to the multipart path. - OpenAPI documents json + multipart + zip bodies and the `async` query param. ## Verification - Full typecheck chain (shared, server, ui, cli) clean. - 152 tests across 8 files: new `portability-zip.test.ts` (STORE/DEFLATE/base64-blob byte-exact round-trip, truncation throws, data-descriptor rejection); `company-portability-routes.test.ts` +7 (multipart import+preview equals the inline bundle; async multipart 202→poll→success; board async via `?async=1` with no cloud header; cloud-tenant async via header; sync fallback with neither; truncated-zip 400, nothing imported); `CompanyImport.test.tsx` asserts the local zip sends the raw File and the inline preflight no longer blocks; `openapi-routes.test.ts` green. - NOT yet measured: the end-to-end browser upload through the live Cloud harness — verified on staging after deploy before closing out. ## Risks - Import semantics unchanged — only transport changed; the JSON inline path is byte-identical, the cloud-tenant header async path untouched. Multipart parsing is server-side (memory-bound: a ~13MB zip → ~30MB files map, fine on the server). - The bare `application/zip` path is programmatic-only and covered by content-type dispatch but not a dedicated route test (the multipart path is). ## Model Used - Claude Fable 5 (`claude-fable-5`, Anthropic), Claude Code CLI, extended thinking + tool use; root-caused against live logs/DB and the harness proxy source. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [ ] All Paperclip CI gates are green - [ ] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge |
||
|
Devin Foley
|
276ae3a75d |
Harden company import: durable UI, async jobs, integrity guard, batched inserts (#10523)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work > - Company Import/Export (#10507) moves whole companies between instances as portability bundles > - Real-world use on a large company (1,418 issues, ~10.6k comments) surfaced a cluster of related failures: the import took hours and the browser connection died while the server kept running, a retry silently produced a second partial import, the progress/error UI gave no durable signal, and a cloud-tenant user couldn't even open the companies afterward > - Root cause of the slowness: importBundle inserted every issue, comment, and document as a separate round-trip to a network Postgres — an N+1-over-network pattern > - This pull request hardens the whole import path: durable progress/error UI, an async server-side job so imports survive dropped connections (with a duplicate-submit guard), a fail-closed guard against incomplete payloads, and batched inserts that cut a large import from hours to minutes > - The benefit is that migrating a real, large company actually completes, is legible while it runs, and can't half-import twice ## Linked Issues or Issue Description - Refs #10507 (the Import/Export feature this hardens). Supersedes #10513 (the progress/error-UI piece, folded in here). No open issue; problem described above (large-company import: slow, connection-fragile, silently duplicable, opaque UI). ## What Changed - **Batched inserts (perf):** importBundle pre-generates entity ids in JS and inserts in chunked multi-row statements, so children no longer wait on parents' generated ids. A 1,418-issue import drops from ~15,600 insert statements to **82** (190×); benchmark below. Import semantics — collision handling, pause-on-import, label/blocker/monitor/attachment/embedded-asset handling, blob sha verification — are unchanged (full portability suite green). - **Async import jobs for board sessions:** the existing cloud-tenant async job path opens to board sessions with per-actor job keys; the import page submits, polls, and resumes watching after a reload or dropped connection instead of holding one fragile request. A non-terminal job blocks a duplicate submit (409 returns the running job), preventing the double-import. - **Fail-closed completeness guard:** an optional `expectedFileCount` on inline imports; the server rejects (422 `import_payload_incomplete`) a body carrying fewer files than declared, so a re-framed/short payload fails loudly instead of half-importing. - **Durable progress/error UI (was #10513):** persistent progress panels with size-aware copy, persistent error panels with retry guidance, and inline explanation when the preview button is disabled; request-lifecycle guards so stale previews/imports can't publish or detach. ## Verification - `pnpm -r` typechecks (shared, server, ui) clean. - `company-portability.test.ts` (76) + `company-portability-routes.test.ts` (30) green — the import correctness net — plus new `CompanyImport.test.tsx` async/resume/409 coverage and a new batching regression test (a 50-issue import issues <50 issue-insert statements; rows land unchanged). - **Batching benchmark (embedded Postgres):** at 1,418 issues × 7 comments × 1 doc — 82 insert statements vs ~15,598 one-per-row (190×), ~1s wall-clock; a row-verifying run at that scale imports all 1,418 issues / 9,926 comments / 1,418 documents with unique identifiers and no warnings (no rows dropped by chunking). Over a network DB the round-trip reduction is the hours→minutes lever. - What is NOT directly measured here: wall-clock against a real network Postgres (that happens on a staging deploy); the local timing is network-free. ## Risks - Batching is the load-bearing change: it rewrites the import write path. Mitigated by the unchanged 106-test correctness suite, a new scale/row-integrity test, and per-writer transactions (a failure rolls back its table group; not a single outer transaction across writers — noted, correctness preserved). - Async jobs are in-memory (lost on server restart → pollers 404 and can resubmit); matches the pre-existing cloud-tenant job semantics. - `expectedFileCount` is optional (older callers unaffected); over-count is allowed, only under-count fails closed. ## Model Used - Claude Fable 5 (`claude-fable-5`, Anthropic), Claude Code CLI, extended thinking + tool use; implementation across Fable 5 subagents with live diagnosis against a running instance. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [ ] All Paperclip CI gates are green - [ ] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge |
||
|
DottaandPaperclip
|
a116713b9a |
feat(mcp) [split 6/8]: add Tools and Profiles UI foundation (#9561)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work > - Governed MCP access spans contracts, runtime enforcement, adapters, UI surfaces, and operator verification > - The parity reference PR #9534 is too large for effective automated or human review > - The feature therefore needs a linear stack whose individual diffs stay below the 100-file review limit > - This pull request is split 6/8 and focuses on UI API, shared components, and Tools/Profile surfaces > - The benefit is a standalone, testable review boundary while preserving byte-for-byte parity at the top of the stack ## Linked Issues or Issue Description - Related parity reference: #9534 - Problem: Operators need typed clients and administration surfaces that compile independently before navigation exposes them. - Proposed solution: Adds UI APIs, hooks, libraries, shared components, Tools/Profiles pages, and the plugin settings consumer required by the new company-scoped API. - Alternatives considered: keeping #9534 as one 403-file review, or rewriting the feature to manufacture seams; both were rejected in favor of path extraction plus compile-driven boundary moves. - Roadmap alignment: this advances the existing governed MCP/tool-access work already represented by #9534; it does not introduce a separate roadmap initiative. - Stack position: base branch is `pap10341-split/05-runtime-integration`. - Merge policy: merge bottom-up, in order, only after the complete eight-PR stack has been reviewed and the top-of-stack parity gate remains empty. - Requested review: UXDesigner sanity pass on Tools/Profile surfaces; Greptile on every PR. ## What Changed - Adds UI APIs, hooks, libraries, shared components, Tools/Profiles pages, and the plugin settings consumer required by the new company-scoped API. - Keeps this PR below 100 changed files and independently typecheckable. - Preserves the final tree from #9534 when combined with the other seven stack levels. ## Verification - `pnpm typecheck` - `pnpm check:token-gates` — all gates clean - Focused UI Vitest run with `NODE_ENV=test` — 28 files, 183 tests passed ## Risks - Large dead-code UI additions can drift from activation routes; PR 7 supplies the registration layer and top-level parity catches omissions. - Stack risk: merging out of order can expose incomplete layers; mitigate by following the documented bottom-up merge policy. - Parity risk: later edits to an intermediate branch can drift from #9534; mitigate by re-running the empty top-of-stack diff before merge. > For core feature work, check [`ROADMAP.md`](ROADMAP.md) first and discuss it in `#dev` before opening the PR. Feature PRs that overlap with planned core work may need to be redirected — check the roadmap first. See `CONTRIBUTING.md`. ## Model Used - OpenAI Codex, exact model ID `gpt-5.4`; runtime-managed context window; medium reasoning with repository, shell, Git, GitHub CLI, and code-execution tools enabled. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] Internal references are omitted except the execution-plan link explicitly required for this coordinated split stack - [x] My branch name describes the change and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [ ] All Paperclip CI gates are green - [ ] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge ## Stack Coordination - Internal execution plan: [PAP-13874](/PAP/issues/PAP-13874#document-plan) - Parity reference: #9534 - Stack: #9556 → #9557 → #9558 → #9559 → #9560 → #9561 → #9562 → #9563 - Merge bottom-up only after full-stack review and an empty parity diff at #9563. ## UI Evidence QA captured these from the live Garden MCP split stack at 1440px and verified clean rendering: 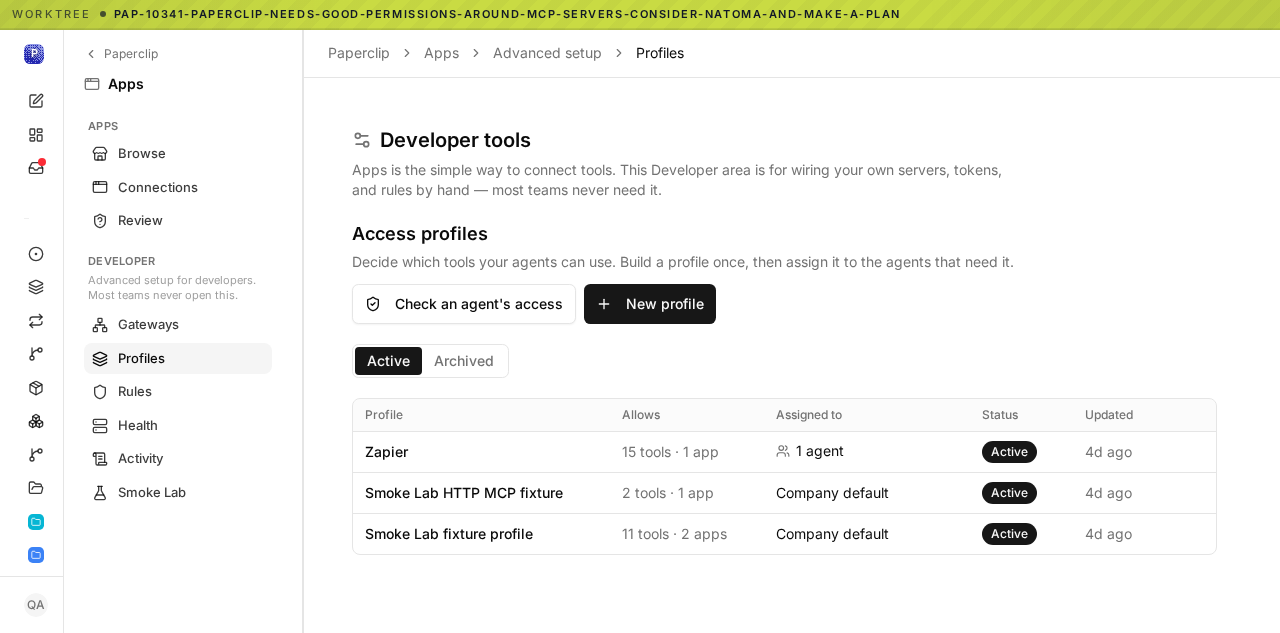 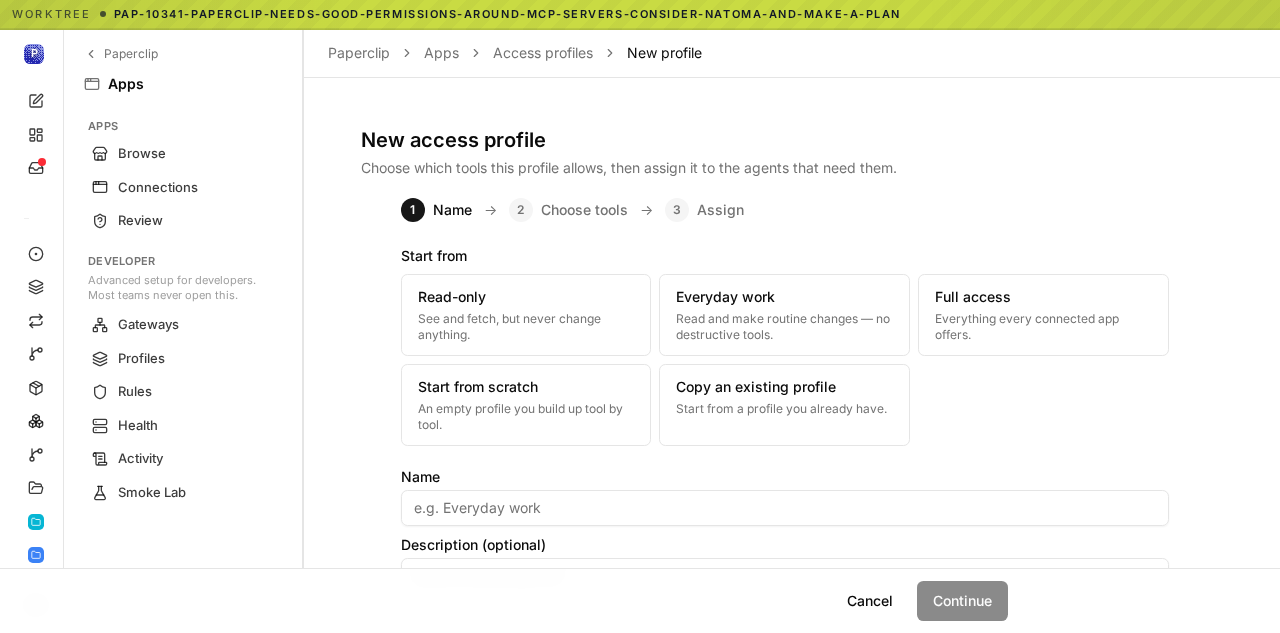 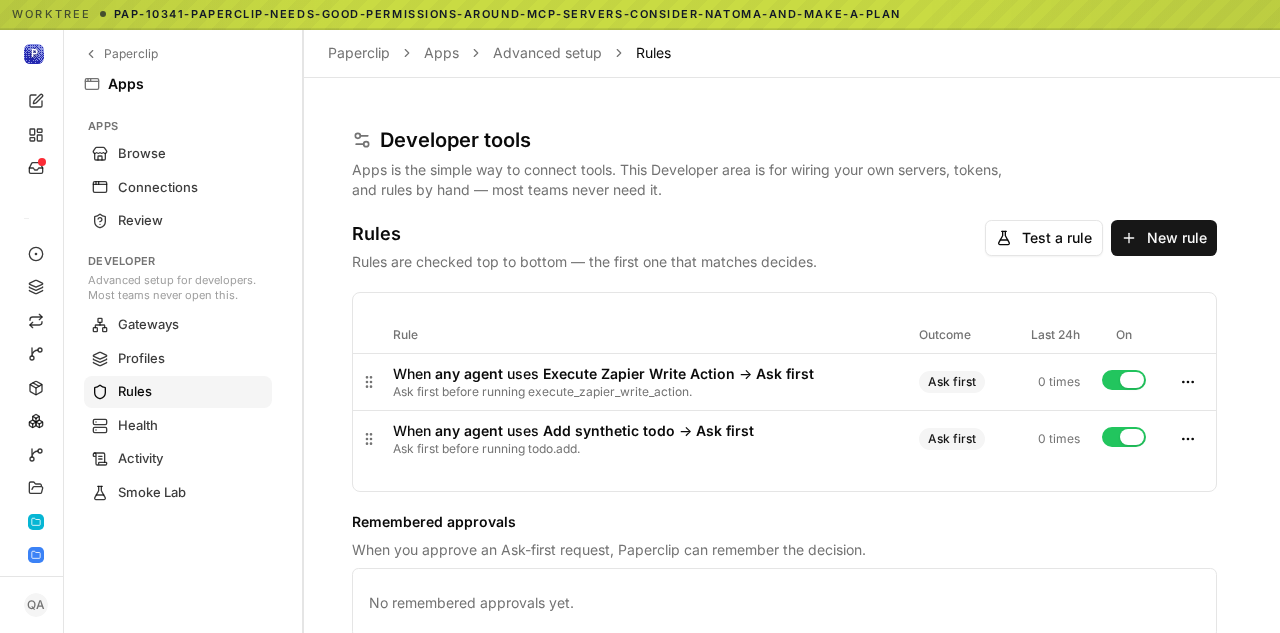 --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
DottaandPaperclip
|
176645187c |
Fix request storm polling and issue-list coalescing (#9190)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work > - The board UI keeps issue, agent, activity, and run state fresh through polling across several pages and sidebar surfaces > - When multiple components or browser tabs poll the same company data at the same time, the API can receive bursts of duplicate issue-list requests > - Those duplicate requests increase database and server load without returning meaningfully different data > - This pull request adds server-side compression/coalescing plus client-side visibility-aware and cross-tab shared polling > - The benefit is lower request volume during normal board usage while preserving fresh UI data for active users ## Linked Issues or Issue Description No exact public GitHub issue was found for this request. Problem: - The board can issue redundant polling requests for the same issue-list data from multiple UI surfaces and tabs. - In busy operator sessions, those bursts can trigger request-storm behavior and unnecessary issue-list load. - Expected behavior is to reuse identical in-flight work server-side and reduce hidden-tab or duplicate-tab polling client-side while preserving normal refresh behavior. Related public context found during duplicate search: - #8206 covers a different board UI 404-storm scope. - #5165 covers separate issue-list behavior around page-size truncation. ## What Changed - Added API compression middleware foundation and a company/created-at index for heartbeat run access. - Added server-side issue-list request storm detection and identical in-flight request coalescing. - Added UI fetch metadata, visibility-aware polling, and request deduplication for issue/activity/client calls. - Added cross-tab shared polling primitives and wired them into the sidebar, inbox, dashboard, issue, project, routine, and agent surfaces. - Resolved the latest `master` migration collision by keeping upstream `0140_built_in_managed_resources.sql` and renumbering this branch's heartbeat-run index migration to `0141_heartbeat_runs_company_created_at_index.sql`; the SQL uses `CREATE INDEX IF NOT EXISTS` for idempotency. - Stabilized server heartbeat cleanup tests exposed by the PR check matrix. - Fixed the Greptile compression follow-up by weakening strong ETags on encoded JSON responses and bypassing compression for streamed/download responses. ## Verification - `pnpm exec vitest run ui/src/components/IssuesList.test.tsx ui/src/pages/Inbox.test.tsx` — passed after resolving the latest `master` conflict in `IssuesList.tsx` and updating the 200-result cap expectations. - `pnpm check:token-gates` — passed after the UI conflict resolution. - `jq -e '.entries | length as $n | (map(.idx) | unique | length == $n) and (map(.tag) | unique | length == $n)' packages/db/src/migrations/meta/_journal.json` — passed after renumbering the migration to `0141`. - `pnpm exec vitest run server/src/__tests__/api-compression.test.ts` - passed after the compression follow-up. - `pnpm exec vitest run server/src/__tests__/issue-list-assignee-filter-routes.test.ts` - passed after the compression follow-up. - `pnpm --filter @paperclipai/server typecheck` - passed after the compression follow-up. - Greptile Review for head `8dbddac41ec273fda404100b4981ddb912fad57b` - passed after the latest conflict/migration fix; all Greptile review threads are resolved. - `pnpm exec vitest run server/src/__tests__/api-compression.test.ts server/src/__tests__/issue-list-assignee-filter-routes.test.ts ui/src/api/client.test.ts ui/src/api/issues.test.ts ui/src/lib/polling.test.ts ui/src/lib/cross-tab-poll.test.ts ui/src/pages/Inbox.test.tsx ui/src/components/SidebarProjects.test.tsx ui/src/components/SidebarAccountMenu.test.tsx ui/src/lib/issueDetailCache.test.ts` — passed. - `pnpm exec vitest run ui/src/api/client.test.ts` — passed. - `pnpm exec vitest run ui/src/pages/Inbox.test.tsx ui/src/components/SidebarProjects.test.tsx ui/src/components/SidebarAccountMenu.test.tsx ui/src/lib/issueDetailCache.test.ts` — passed. - `pnpm exec vitest run server/src/__tests__/heartbeat-worktree-suppression.test.ts` — passed. - `pnpm exec vitest run server/src/__tests__/low-trust-red-team-routes.test.ts` — passed. - `pnpm exec vitest run server/src/__tests__/heartbeat-workspace-finalize-branch.test.ts` — passed. - `pnpm --filter @paperclipai/ui typecheck` — passed. - `pnpm --filter @paperclipai/server typecheck` — passed. - GitHub PR checks for head `8dbddac41ec273fda404100b4981ddb912fad57b`: all GitHub Actions/status checks passed; Greptile, Superagent, Socket, Snyk, build, typecheck/release registry, general tests, serialized server suites, e2e, canary dry run, policy, and commitperclip review are green; Storybook visual regression and security-review were skipped/neutral by policy. - Confirmed this branch does not include `pnpm-lock.yaml` or `.github/workflows` changes. ## Risks - Medium risk: issue-list coalescing changes request timing and cache semantics for a hot API path. - Medium risk: cross-tab polling uses browser coordination primitives, so older or unusual browser environments need fallback behavior to stay correct. - Low migration risk: the new index migration is ordered after current `master` and uses `CREATE INDEX IF NOT EXISTS`. > For core feature work, check [`ROADMAP.md`](ROADMAP.md) first and discuss it in `#dev` before opening the PR. Feature PRs that overlap with planned core work may need to be redirected — check the roadmap first. See `CONTRIBUTING.md`. ## Model Used OpenAI Codex coding agent, GPT-5-based model, tool-enabled with shell/git execution. Exact hosted deployment identifier and context-window size were not surfaced in the agent runtime. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
|
b13eb5b2b5 |
Skill Studio: three-pane skill IDE with sandboxed test runs (#9241)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work. > - The Skills Manager gives operators a reusable skill layer, but iteration still required manual edits, ad hoc prompts, and indirect run inspection. > - Skill authors need a focused workflow for editing skill files, saving representative test inputs, and running those inputs through an agent without exposing harness tasks as normal company work. > - The backend therefore needs durable test inputs, reusable run templates, hidden harness issues, scoped run execution, retention metadata, and read-containment rules around hidden work. > - The frontend needs a three-pane Studio that keeps skill files, saved inputs/templates, and run output/history visible together while preserving the existing design system and token rules. > - This pull request ships that Skill Studio surface end to end: database migrations, shared contracts, server APIs/services, hidden harness execution behavior, UI routes/components, and focused tests. > - The benefit is faster and safer skill iteration, with inspectable outputs and fewer ways for internal harness work to leak into normal task lists, costs, or adjacent read APIs. ## Linked Issues or Issue Description No public GitHub issue exists for this feature. Feature request summary: - Problem: Skill authors need to edit and test company skills in one place instead of switching between the skill detail page, task creation, run output, and manual prompt history. - Proposed solution: Add a Skill Studio workbench with saved inputs, reusable templates, hidden sandboxed test runs, live run status, output inspection, run history, rerun/delete controls, and frontmatter-aware editing. - Expected users: Paperclip operators and agent-company maintainers who create, fork, import, and tune skills. - Related public PRs: Supersedes #9205, which was replaced so the public PR branch name follows contributor policy. - Duplicate search: searched public GitHub issues and PRs for "Skill Studio"; no other active public issue or PR directly covers this feature. ## What Changed - Added database migrations for Skill Studio test inputs, test runs, test run retention, and reusable run templates. - Added shared Skill Studio types, validators, route helpers, frontmatter utilities, and status handling. - Added server services and routes for saved inputs, test runs, templates, reruns, terminal-run deletion, hidden harness issue execution, and run-detail hydration. - Strengthened hidden-issue read containment across issue-adjacent routes and cost rollups used by skill test harness work. - Added the Skill Studio UI with skill file editing, frontmatter editing, saved inputs, templates, run creation/cancel/rerun/delete flows, output rendering, history, route support, and responsive pane behavior. - Added focused backend, shared, and UI tests for the new APIs, routing logic, editor/run behavior, hidden-issue containment, and migration safety. - Rebased onto current `master`, removed the generated lockfile diff from the PR, and verified no workflow files are changed. ## Verification - [x] `pnpm --filter @paperclipai/db check:migrations` - [x] `pnpm check:token-gates` - [x] `pnpm exec vitest run server/src/__tests__/company-skills-service.test.ts server/src/__tests__/company-skills-routes.test.ts server/src/__tests__/company-skill-test-runs-service.test.ts ui/src/lib/skill-studio.test.ts ui/src/pages/SkillStudio.test.tsx` — 5 files, 132 tests passed - [x] Greptile review on the latest PR head - [x] GitHub PR checks on the latest PR head ## Risks - Medium risk because this is a broad feature touching database schema, server orchestration, issue visibility, and a large UI surface. - Hidden harness issue containment is security-sensitive; this PR includes regression coverage for adjacent read paths and cost rollups. - The new migrations are additive and use idempotent guards where applicable, but deployed databases that previously tested draft migration numbers should still be checked carefully. - The UI depends on a new resizable panels package in `ui/package.json`; the lockfile is intentionally left to repository automation. > For core feature work, check [`ROADMAP.md`](ROADMAP.md) first and discuss it in `#dev` before opening the PR. Feature PRs that overlap with planned core work may need to be redirected — check the roadmap first. See `CONTRIBUTING.md`. ## Model Used OpenAI Codex, GPT-5 coding agent with shell, git, and GitHub CLI tool use. Earlier feature commits include assistance from other Paperclip coding agents; this PR preparation, rebase, cleanup commit, and PR body were completed by OpenAI Codex in a Paperclip worktree. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> Co-authored-by: Claude Opus 4.8 <noreply@anthropic.com> |
||
|
dottaandPaperclip
|
21765f8118 |
Fix trigger delete: handle 204 No Content in API client
The DELETE /routine-triggers/:id endpoint returns 204 No Content, but the API client unconditionally called res.json() on all responses, causing a JSON parse error that surfaced as "API route not found". Co-Authored-By: Paperclip <noreply@paperclip.ing> |
||
|
DottaandPaperclip
|
45998aa9a0 |
feat(issues): add issue documents and inline editing
Co-Authored-By: Paperclip <noreply@paperclip.ing> |
||
|
ForgottenandClaude Opus 4.6
|
2ec45c49af |
feat(ui): add auth pages, company rail, inbox redesign, and page improvements
Add Auth sign-in/sign-up page and InviteLanding page for invite acceptance. Add CloudAccessGate that checks deployment mode and redirects to /auth when session is required. Add CompanyRail with drag-and-drop company switching. Add MarkdownBody prose renderer. Redesign Inbox with category filters and inline join-request approval. Refactor AgentDetail to overview/configure/runs views with claude-login support. Replace navigate() anti-patterns with <Link> components in Dashboard and MetricCard. Add live-run indicators in sidebar agents. Fix LiveUpdatesProvider cache key resolution for issue identifiers. Add auth, health, and access API clients. Co-Authored-By: Claude Opus 4.6 <noreply@anthropic.com> |
||
|
ForgottenandClaude Opus 4.6
|
6d0f58d559 |
fix: storage S3 stream conversion, API client FormData support, and attachment API
Fix S3 provider to use async generator for web stream conversion instead of Readable.fromWeb, add postForm helper and attachment API methods to the UI client, and add local disk storage provider tests. Co-Authored-By: Claude Opus 4.6 <noreply@anthropic.com> |
||
|
ForgottenandClaude Opus 4.6
|
c3d82ed857 |
Add React UI with Vite
Dashboard, agents, goals, issues, and projects pages with sidebar navigation. API client layer, custom hooks, and shared layout components. Built with Vite and TypeScript. Co-Authored-By: Claude Opus 4.6 <noreply@anthropic.com> |


