mirror of
https://github.com/paperclipai/paperclip.git
synced 2026-11-08 22:13:59 +01:00
87dfba6818dca415f4e350de2af9e4655faf132e
12
Commits
| Author | SHA1 | Message | Date | |
|---|---|---|---|---|
 DottaandPaperclip |
85e4d12856 |
fix(evals): report controlled protocol cases from safe records (#19070)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work. > - Runner protocol qualification records real provider behavior in TestOps. > - Controlled attempts keep raw records and accounting in private storage. > - A live case passed, but a later public-render command rejected its controlled context. > - The missing public report caused the final result to be stored as broken. > - This pull request creates the closed TestOps result from existing sanitized records inside the private report job. > - The benefit is correct result reporting while the privacy guard stays effective. ## Linked Issues or Issue Description Refs #18985 and #19011. The related-PR search found no separate repair for this failure. **What happened?** [The live canary](https://github.com/paperclipai/paperclip/actions/runs/41916513378) passed all four provider checks. Its controller verified cleanup and closed its request accounting. The private canonical report recorded one passed case. The next command used `--public-viewer` while the controlled manifest remained set. The eval program rejected it with `controlled campaign evidence must remain private`. The closed exporter then had no public payload and correctly stored a broken result. **Expected behavior** Report the original case grade from sanitized structured records. Keep raw controlled records private. Keep the original checks, source bindings, and missing-evidence rules. **Steps to reproduce** Run one controlled protocol case with TestOps reporting enabled. Let the private canonical report finish. The following public-render step fails before the closed result can read the grade. **Paperclip version or commit** Observed at `4740d251b7032e714d33039ba66a56948238c38f`. This repair is based on `c6cb7e2a2d42743c0c3c4ead2cbad4a299f9a2e7`. **Deployment mode** GitHub-hosted Linux, controlled ACPX Claude protocol qualification, first workflow attempt, zero automatic retries. ## What Changed - Add a narrow `export-runs` path to the existing TestOps helper. Bind the sanitized score and artifact to the exact attempt, case, model, provider, driver, and public-projection schema. Reuse the existing strict grade and check validation. - Keep sanitization inside the private report job. Use structured records for controlled TestOps reporting. Keep the public viewer for legacy publication. - Add record identity, privacy, grade, command, and workflow routing controls. Wire the existing helper and workflow-security files into the required Node registry. Document the reporting path. ## Verification - 43 focused campaign/sanitizer, TestOps and workflow security tests passed. The command regression writes a raw attempt, calls the production sanitizer, and runs `export-runs` on its output. It also repeats that chain after a failed-check mutation. Both new-control files now run through required `test:typescript:prep`, not only the optional publisher script. - The actual required prep ran locally with provider credentials excluded. The eval-kernel and Rust builds passed. Its Node registry executed the new producer-to-export and security controls by name: 403 passed, 2 failed, 11 existing skips. The two original package-contract failures cannot resolve this isolated clone's Codex ACP and Claude ACP package links. This is not a green local full-prep claim. The first attempt also stopped at a missing Node-types link, before an ignored clone-local link to the locked cached version restored that prerequisite. - 72 release workflow tests passed with the existing locked pnpm 9.15.4 wrapper and local loopback permission. The first sandbox run failed because loopback fixtures could not listen; the default local tool path also failed two install fixtures. No test assertions were changed to resolve these failures. - The actual repaired workflow shell ran locally against the retained canary campaign and sanitized records. It emitted one closed passed result with all four original checks. No provider request or upload occurred. - Missing or failed checks still reject a pass. Private-only markers stay absent from the closed output. Wrong model, provider, driver, attempt, case, and schemas reject. - The unmodified, pinned eval program still rejects a controlled public-viewer command. - Actionlint and `git diff --check` passed. [Full final-head CI](https://github.com/paperclipai/paperclip/actions/runs/41927878886) passed on its first attempt at `0d0c090b1b`. Required verify/e2e gates, all four Runner lanes, typecheck, build, backend and browser shards passed. Package suite: 4951 passed, 10 existing skips across 297 passed files and one existing file skip. - The required static log contains passing lines for both the production sanitizer-to-export command regression and the closed-projection security control. The prior optional-script registration did not run those tests in required CI; the one script-entry fix now enforces them. Provider/runtime and workflow bytes are unchanged by the verification-only follow-ups. - Greptile: fresh 5/5 on `0d0c090b1b`, with no actionable new issues. The separate Paperclip Review requested a producer-to-consumer regression. That regression and its required-CI wiring are complete. The addressed thread is resolved; no open review threads remain. - No fresh deployed reporting pass is claimed. The failed workflow and its stored broken result remain unchanged. ## Risks The exporter reads structured records inside the private job. It copies only the closed result fields and requires the existing sanitized marker and identity checks. The final reporting job still receives only those files and verifies the saved result bindings. The Python privacy guard, provider path, case assertions, budgets, deadlines, and retries are unchanged. ## Model Used OpenAI Codex, exact model `gpt-6.1-sol`, max reasoning effort. The inherited runtime reports a 475,000-token context window. Capabilities used: reasoning, code changes, and repository, shell, and GitHub tools. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
Dotta
|
8002dfb06e |
fix(evals): repair bounded TestOps protocol admission (#19011)
## Thinking Path > - Paperclip lets people manage AI agent work through a governed control plane. > - Runner protocol qualification uses real providers and records selected cases in TestOps. > - A manual registration run starts an Allure watch session before it validates the case selection. > - Watch creates the job run, but it does not fill the empty job-run input in the child environment. > - The selection helper therefore stops before it can validate the new job run. > - A configured AWS concurrency ceiling can also reject a valid smaller hosted-runner request. > - Hosted tool-cache permissions can also violate Runner qualified-executable admission before a provider starts. > - This pull request captures official session identities, keeps both concurrency ceilings, and stages the same Node bytes in an owned directory. ## Linked Issues or Issue Description Refs #18985. **What happened?** The [first registration attempt](https://github.com/paperclipai/paperclip/actions/runs/41877603952) created an Allure job run, then stopped with `runner_testops_jobrun_missing`. The child inherited an empty `ALLURE_JOB_RUN_ID`. The helper made no job-run API read and executed no provider case. The current configured concurrency ceiling is 100. The controlled hosted cap is 57. The original catalog guard rejects 100 before it applies a valid requested value of 2. The [first service-selected attempt](https://github.com/paperclipai/paperclip/actions/runs/41884365232) reproduced this second pre-provider failure. Its selected case was correctly reported as broken. No provider cell ran. A [second service-selected attempt](https://github.com/paperclipai/paperclip/actions/runs/41887671585) passed selection, lock and cost preflight. Runner rejected a qualified ACPX launch artifact as group- or world-writable. It recorded no model request. The verified sidecar is mode 0755. Hosted Node is the only other launch artifact, which points to Node as the cause. The original run did not retain its exact mode. The TestOps reporter retained the infrastructure failure. **Expected behavior** The manual path must capture the job-run and launch IDs from the active official watch session. It must validate those IDs against the same GitHub run, job, launch and standing plan before provider work. A requested concurrency value must fit the configured ceiling and the selected runner cap. The default must use the lower ceiling. Before credentials, the worker must stage the same Node bytes in an owned directory and preserve Runner permission and digest admission. **Steps to reproduce** 1. Dispatch the trusted Runner protocol workflow with reporting enabled and an empty job-run service input. 2. Let `allurectl watch` create the registration session. 3. Observe that the original helper rejects the empty child input before selection validation. ## What Changed - Call the supported `allurectl job-run env` command for manual registration. Use a fixed argument list without a shell and bound its time and output. - Parse only numeric job-run and launch IDs. Reject missing, duplicate, malformed or conflicting values. Discard all other command output. - Bind the captured launch ID to the authoritative job-run response. Keep the service-supplied ID path and its existing checks. - Apply requested parallelism within both configured and physical ceilings. Use their minimum as the default. Keep the selected-case capacity and provider budget checks. - Snapshot the same current Linux Node bytes into a fresh owner-only directory before credentials. Verify the copy, execute it to bind its path and version, and put only that directory first on the job-local path. Record original and copied Node modes and hashes plus the actual sidecar mode and hash. Keep shared cache permissions and Runner security checks intact. - Add focused context, identity, concurrency, permission and secret-exclusion controls. Supply the production physical cap in the existing release-workflow fixture. - Fix the existing Kimi cancellation fixture to await the complete readiness sentinel within the same 100 by 10 ms bound. Keep its cancellation and cleanup assertions. ## Verification - The original empty-ID failure reproduces locally on the actual helper with all 41 standing cases and zero job-run API reads. - All 63 Node publication, projection, metrics, permission and workflow-security tests pass. The repaired manual context flows through the actual selection helper to case 194. Wrong launch, duplicate IDs, malformed values and command failures still stop selection. - The original catalog prefix rejects configured 100 / hosted 57 / requested 2. The repaired prefix admits 2, clamps a missing request to 57, keeps legacy 100, and rejects requests above either ceiling. - The full release-policy CI command passes locally: 72 release-workflow tests and 107 companion tests. The first sandbox run could not bind its loopback fixtures; the same tests passed with local-network access. The prior-head CI fixture omission is retained and fixed by supplying the same physical cap as production. - Both full static Node file groups pass locally: 418 passed and 11 existing opt-in skips, at concurrency 2. Initial runs used stale dependency links and failed. Correcting only isolated ignored links to declared cached dependencies and pnpm 9.15.4 removed those setup failures. Local Node 26.4 differs from CI Node 24; the exact-head CI below provides canonical verification. - `actionlint .github/workflows/runner-protocol-live-evals.yml` and `git diff --check` pass. - The new staging helper passes all four tests as a nonroot Linux user with networking disabled. An actual retained Runner comparison reproduces the qualified-artifact rejection with Node mode 0777. The same Node bytes at 0500 in a 0700 directory pass that launch boundary and reach a closed provider session. The local turn still fails without credentials or network; this is permission proof, not a protocol case pass. Local Linux Node 24.21 differs from the hosted 24.22.1 executable. - Exact final head `8e06ee5611` [repository CI](https://github.com/paperclipai/paperclip/actions/runs/41892896405) completed successfully. Typecheck, build and all four Runner lanes passed. Runner package tests passed 4950 tests in 297 files, with 10 existing skips. Fresh exact-head Greptile review is 5/5 with no actionable findings or open threads. Prior `59378f` CI Kimi empty-sentinel race and canceled chat worker remain retained. - The patched manual workflow has not run against live TestOps. A separate service-triggered probe supplies its own ID. The service probe used the original concurrency guard with a temporary configured ceiling of 57. After the probe, the original repository ceiling 100 was restored with no active campaigns. That probe does not verify this patched concurrency code. The next launch waits for the protected merge and source/lock verification. ## Risks An incompatible official CLI output fails closed. The helper never evaluates the output or records its unknown variables. The existing job, workflow URL, source, plan and provider checks remain required. An omitted concurrency request now uses the lower of the configured and physical ceilings. Explicit requests above either ceiling still fail. The worker now executes a private copy of its existing Node binary. A copy, mode, hash, path, version or sidecar mismatch stops before credential access. The copy does not make dynamically linked Homebrew Node portable; this workflow path is Linux only. This change does not alter the provider roster, policy, limits, retries or result grading. ## Model Used OpenAI Codex, GPT-6. The exact hosted model ID and context window are not exposed in this session. Used reasoning, code editing, repository inspection and tool execution. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge |
||
|
DottaandPaperclip
|
039e0dad2c |
Connect TestOps protocol plans to verified GitHub attempts (#18985)
## Thinking Path > - Paperclip lets people coordinate agent work through a governed control plane. > - Runner protocol evals test real provider sessions against a seeded mock control plane. > - The saved TestOps protocol plan has no GitHub executor. Its dashboard shows historical results. > - A current one-case attempt also failed before any tool call or provider output. Its retained public-safe snapshot withheld the error cause. > - This pull request connects selected cases to the existing trusted workflow and retains closed operator failure facts. > - Each selected case receives a current result. Missing evidence remains broken. Existing assertions and machine grades remain unchanged. ## Linked Issues or Issue Description **Current behavior** The saved protocol plan cannot start a GitHub qualification attempt. Historical dashboard results can be mistaken for current execution. A failed provider turn can also lose its failure category when the live snapshot applies public evidence redaction. **Proposed behavior** The existing workflow accepts TestOps service inputs, validates exact case identities before provider work, runs the selected cases, and verifies their published statuses. Eval artifacts retain only validated failure phase, category, HTTP status, and retryability. **Reason and benefit** Operators can run the standing plan from TestOps and inspect current, source-bound results. A targeted pass cannot stand in for full-plan coverage. A failed startup can be diagnosed without publishing provider messages or request identifiers. ## What Changed - Add optional TestOps selection and protected reporting jobs to the existing Runner protocol workflow. - Keep the current actor, source, provider credential, and controlled accounting gates. TestOps retains the explicitly selected controlled or legacy mode and a separate 41-case Claude roster. Controlled mode preserves its existing reviewed policy, immutable bindings, tracing and zero-retry admission. Its paid workers explicitly use GitHub-hosted runners, matching the current manifest admission contract even when the legacy AWS fleet is enabled. - Bind the exact standing plan, workflow, job run, source revisions, selected cases, and saved statuses. Accept only verified workflow URL aliases. - Create a closed Allure projection inside the report job. Transfer only fixed case identities, check verdicts, numeric usage and statuses to the reporting environment. Controlled raw/chat/controller evidence remains private. - Publish one result for every selected case. Retain missing execution/report evidence as broken. Reject unsupported passes, model mismatch and source drift. Preserve the evidence schema literal, stop publication on cancellation, and retain closed API error codes/statuses. - Tag full selections separately from targeted attempts. Add bounded ingestion observation. Apply the exact TestOps filter before the unchanged controlled provider/cell-capacity check, so a one-cell registration fits a one-cell reviewed policy. - Retain up to eight eval-only closed provider failure records before board evidence redaction. Forward the original notifications unchanged. - Add selection, reporting, privacy, and admission regression controls. Document scope and remaining acceptance. ## Verification - Direct Node protocol publication, projection, metrics, and security tests: 56 passed. Focused controls exercise both mode admissions, missing controlled policy/retries/source rejection, closed result transfer, exact metadata, and missing-result handling. - `actionlint .github/workflows/runner-protocol-live-evals.yml` and `git diff --check` passed. - A proposed one-cell controlled policy passed the actual hosted validator with a synthetic prepared request and zero provider calls. The actual 41-case catalog filter selected case194/get-task-context and the real hosted admission accepted it under maxCells1. Negative controls rejected the unfiltered41, unsupported provider, source, selection, origin, expiry and lock drift. This does not verify provider auth, a runtime build or TestOps publication; final merged source/lock binding is still required. - The actual diagnostic TypeScript module passed positive, negative, secret-exclusion, and unchanged-notification controls through the existing tsx runtime. A local actual-CLI startup serializer probe passed with closed facts, secret exclusion, exit status and read-only fixture cleanup. This used an isolated resolver into the existing dependency cache; canonical exact-dependency CI remains required. - Prior-head CI passed typecheck, Runner static/Rust/native-server checks and 4946 Runner package tests. One new serializer fixture failed during Linux read-only directory cleanup; this head applies the existing neighboring cleanup pattern. Unrelated chat E2E and CLI import timeouts remain retained. Latest-head required gates are pending. - Original current-source one-case attempt: https://github.com/paperclipai/paperclip/actions/runs/41860234840 . It failed with no tool calls or output. That failure remains retained and is not a passing qualification claim. - Diagnostic candidate attempt: https://github.com/paperclipai/paperclip/actions/runs/41863410602 . It retained the new closed field but still failed before output with category unknown. This disproves the claim that typed retention alone identifies the cause. - The earlier passing run https://github.com/paperclipai/paperclip/actions/runs/40627274706 used controlled Braintrust routing. Both current failures used direct legacy credentials, a different auth path. Next acceptance is one explicitly controlled case with a reviewed current policy, followed by TestOps registration and a fresh full plan. None is claimed complete by this PR body. ## Risks The TestOps contract currently binds the existing 41 cases and one recorded Claude Sonnet 5 profile. Catalog changes fail closed until reviewed. This does not qualify other providers. Admission and execution qualify only the selected accounting mode; a controlled pass does not prove direct credential health. Model-request readiness retains pending operating reconciliation. TestOps ingestion can fail independently; persisted results are checked, and missing evidence is never accepted as a pass. The new failure field contains closed facts only; raw messages, identities, credentials, and tool payloads are excluded. ## Model Used OpenAI Codex, GPT-6. The exact hosted model ID and context window are not exposed in this session. Used reasoning, repository inspection, code editing, and tool execution. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used and the available capability details - [x] I have checked ROADMAP.md and confirmed this does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs - [x] I have described the issue with the enhancement template field labels - [x] I have not referenced internal or instance-local Paperclip issues - [x] My branch name describes the change and contains no internal ticket ID - [x] I have run the available targeted local checks and reported the remaining checks - [x] I have added relevant positive and negative regression controls - [x] I have updated the authoritative protocol documentation - [x] I have considered and documented the risks - [ ] All required Paperclip CI gates are green on the latest head - [ ] Greptile is 5/5 with no open actionable feedback on the latest head - [x] I have addressed all current review feedback --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
DottaandPaperclip
|
8548173fc9 |
feat(evals): connect hosted Runner costs and traces (#17889)
## Thinking Path > - Paperclip manages AI agents and measures their behavior with Runner evaluations. > - The cost controller, native tracing, private receipts and portable runtime are on master. > - The maintained live workflow still launches the provider CLI directly. > - Independent workers need one shared selection and disjoint budget allocations. > - Reports must keep unresolved allocations when a worker produces no evidence. > - This PR connects the maintained workflow to the existing controller and private archive. > - Operators can inspect known costs, conservative holds and trace evidence before qualifying paid recurrence. ## Linked Issues or Issue Description Refs #17452, #17469, #17493, #17506, #17523. **Current behavior** The live Runner workflow does not use the merged cost/tracing controller. Attempt-only aggregation cannot reconstruct a campaign when every worker archive is absent. Ordinary Actions artifacts in this public repository are readable by authenticated public GitHub users. **Proposed behavior** Controlled runs prepare one manifest, bind every selected request, enforce disjoint allocations and retain evidence in private storage. The report starts from the full retained manifest. Missing workers keep their allocations. The workflow rejects retries, unsupported providers, changed requests and absent or stale operating bounds before provider work. **Reason and benefit** The maintained workflow needs auditable costs and traces, including failures and missing receipts, before paid recurrence can be qualified. ## What Changed - Add controlled mode as the manual default and the only scheduled mode. Legacy mode remains explicit for other manual provider qualifications. - Prepare the full request selection and one shared manifest. Bind current run, first attempt, code, definitions, executable hashes and exact profile allocations. - Verify the copied controller and manifest before provider credentials. Require the controlled target to equal the trusted workflow revision before private archive access. - Reuse private archive retention for the controller policy, cell attempts and canonical report. AWS credentials remain transfer-step outputs. Controlled raw evidence is never uploaded as an Actions artifact. - Replay a retained manifest with partial or empty worker evidence. Count operating holds once and preserve known partial charges. - Pin the controller to an explicitly reviewed compatible lockfile digest. Reject resolver or byte drift before a frozen, script-free install into a job-local store. Record the lock digest in the runtime receipt and verify it again in private preparation. - Build the portable controller without secrets, private environment access or OIDC. Private preparation verifies that artifact and performs no dependency install. OIDC jobs use no mutable dependency resolution or shared cache. - Add synthetic source/copied-runtime tests, executable workflow admission tests, private archive tests and an operator runbook. ## Verification - Controller, campaign, portable runtime and workflow tests: 104 passed. This includes real aggregation from an isolated reporter without source dependencies, safe diagnostics, driver drift, distinct evidence binding and reviewed-lock drift. Real private Codex/Claude requests also pass through an independently verified copied runtime with fake transports. - Private transport and workflow contracts: 35 passed. Executable/static workflow guards: 13 passed. - Paired private report tests: 166 passed; Evalbook discovery: 7 passed. - `pnpm -r typecheck` and `pnpm build`: passed. - `pnpm test:e2e:runner:typecheck`, `actionlint .github/workflows/runner-protocol-live-evals.yml` and `git diff --check`: passed. - `pnpm test:run` hit repeated local embedded PostgreSQL initialization failures in unrelated DB-dependent server tests. Its owned process tree was stopped after preserving the log. This is a local verification limitation; current-head CI remains required. - An earlier head hit one unchanged Rust cleanup assertion. The exact test passed locally and the final head passed the full Rust lane; the initial failure log is retained. - On the final head, one unchanged chat idle-queue assertion failed once in CI. Its single scoped retry passed. All test jobs and the final aggregate gate passed on commit `2e328fa53dd296174d59d19f14f068aeeb0b82d8` (CI run 40535692048, attempt 2). - No paid model, Braintrust or cloud calls. No live variables, secrets, schedules or resources changed. ## Risks - Controlled mode fails closed until a reviewed `RUNNER_PROTOCOL_EVAL_CONTROLLER_POLICY_JSON` and a compatible private eval SHA exist. `all` does not silently become a supported subset. - The reviewed policy must cover setup, model requests, trace/gateway processing, archive transfer and retained storage. Hash binding does not establish vendor billing bounds. This PR does not enable recurrence or release historical holds. - The controlled policy must pin `controllerLockSha256`; it never accepts a resolver-generated digest automatically. No lockfile is committed. A changed compatible lock needs review. - Legacy browser verification now requires the committed frozen lockfile. A stale lockfile fails closed; controlled preparation has no dependency install. - Workflow cancellation can prevent the final report. The full manifest is retained before provider work and remains the starting point for reconciliation. - The workflow exceeds 1,000 lines because the shared shard anchor, dependencies, environment expressions and credential boundaries belong to one declarative job graph. Request preparation, accounting, archive safety and runtime verification stay in separately tested modules. ## Model Used OpenAI Codex, GPT-6-based coding agent with tool use and code execution. The host does not expose an exact deployment model ID or context-window size. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run the relevant tests locally and they pass; the broad local suite limitation is documented above - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green on the final head - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups; the secondary reviewer is also 5/5 - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
DottaandPaperclip
|
3f91d58dd5 |
fix(ci): provide Copilot auth only to protected paid eval cells (#17743)
## Thinking Path > - Paperclip manages AI agents and their work. > - Paid runner evals test real provider integrations. > - Copilot cells use the saved-token connection path. > - The two trusted workflows did not pass the Copilot credential to those cells. > - This PR supplies it only when the selected cell needs it. > - Existing environment and actor gates protect access in this public repository. ## Linked Issues or Issue Description Related: #15705 and #15706. A search found no open PR that adds this workflow credential binding. **Describe the bug** Copilot Product and direct-protocol eval cells require `COPILOT_GITHUB_TOKEN`. The protected paid workflows do not currently pass that environment secret to the selected execution step. **Expected behavior** Only a selected Copilot cell receives this credential. Ordinary PR, build, catalog, image and reporting jobs receive none. **Steps to reproduce** Dispatch the trusted full-stack workflow for one Copilot cell. Credential validation fails before the task starts, although the protected environment can hold a valid token. **Environment** GitHub Actions in the public `paperclipai/paperclip` repository, with the reviewed workflow on `master` and the `runner-e2e-paid` environment. ## What Changed - Pass `COPILOT_GITHUB_TOKEN` in the paid Product and direct-protocol execution steps, only when `matrix.credentialName` selects it. - Add the missing Copilot protocol-catalog credential mapping and verify it reaches the selected execution matrix. - Add security checks for the selected-cell binding and bounded protected-job scope. Extend the scan that rejects provider credentials in unrelated workflows. - Document the Copilot credential scope. No secret values, account data or private test evidence are in this PR. ## Verification - Product workflow security: 16 tests passed on this head. - Protocol catalog and workflow security: 21 tests passed, including the Copilot matrix regression reproduced red before its fix. - Current-head required `ci / verify` and `ci / e2e` are green. Greptile is 5/5 with zero unresolved review threads. - The first CI attempt retained runner-shutdown failures; one failed-job retry passed on the unchanged head. Both attempts remain in [the CI run](https://github.com/paperclipai/paperclip/actions/runs/40342429106). - `git diff --check` passed. - A selected-credential scan found zero matching secret values in the seven changed files. - The environment setting was separately checked: `master` only, required approval from existing allowlisted code owners, and administrator bypass disabled. The new secret exists only at environment scope; no repository-wide duplicate was created. - The packaged Copilot runtime verified the selected token and the explicit model without a model prompt. A fresh local UI journey then created an agent, completed its first task and verified the downloaded artifact and cleanup. ## Risks The selected paid cells gain access to one additional environment credential. Missing credentials still fail closed. Default-branch checks, initiating/rerunning actor checks, protected environment access and per-cell credential selection remain in place. This PR adds no trigger and gives no credential to builds or ordinary PR checks. ## Model Used OpenAI Codex, based on GPT-6, with repository tools and browser regression tests. The exact runtime model identifier is not exposed in this session. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either linked existing issues or described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links - [x] My branch name describes the change and contains no internal ticket id - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
DottaandPaperclip
|
db8f8fe5b7 |
fix(evals): select Grok subscription protocol credentials explicitly (#13901)
## Thinking Path > - Paperclip manages agent work through shared runner contracts. > - Direct protocol evals qualify provider behavior against a mock control plane. > - Grok supports API keys and company subscription credentials. > - The hosted protocol workflow selected an API key for every Grok cell. > - Product subscription support did not enable subscription protocol runs. > - This change adds explicit subscription selection and checks the recorded authentication mode. ## Linked Issues or Issue Description Refs #13878, #13882, #12618. The direct Grok protocol roster cannot run with subscription authentication through the trusted default-branch workflow. Add an explicit selector while keeping API-key dispatches compatible. Keep the actor allowlist, protected environment, immutable source revisions, and publication gates. ## What Changed - Add `grok_authentication` with `api_key` and `subscription` choices. Keep `api_key` as the compatibility default. - Deliver the protected `GROK_AUTH_JSON` secret only to a subscription-selected Grok cell. Do not provide an API key to that cell. - Read authentication mode from the pinned eval program's actual roster summary. Retain it in the cell, catalog, campaign roster, and result. - Reject missing or mismatched authentication evidence during aggregation. Preserve cell metadata and an allowlisted failure reason before failing a cell, so malformed evidence cannot hide the retained attempt. - Document credential setup, source separation, and temporary-secret cleanup. ## Verification - `node --test packages/paperclip-runner/scripts/runner-protocol-eval-campaign.test.mjs packages/paperclip-runner/scripts/runner-protocol-eval-workflow-security.test.mjs scripts/__tests__/release-verify-workflow.test.mjs`: 34 tests passed. - Validated all 39 Grok cells at eval revision `3213dbec7e8ca1865ea95e6db7e7d34b095eb47a`; every selected cell requests only the subscription credential. Validation made zero provider calls. - Negative coverage rejects invalid selectors and missing or API authentication evidence in an otherwise passing subscription attempt. - `git diff --check` passed. All 53 current-head checks passed; the unchanged callback-drain timing test passed its bounded rerun, and the failed attempt is retained. Greptile reviewed `ecd3dcc0e998f07cf56fcb1f087946f50f388bec` at 5/5 with no remaining findings. - No Docker or broad builds ran on the developer machine. CI performs repository checks on the configured fleet. ## Risks Grok runs require an eval revision that records `authenticationMode` in the roster summary. Missing evidence fails closed. The credential contains account access and refresh tokens; an owner must approve its delivery to the protected environment before a live run. The change adds no PR trigger or authorization bypass. Live subscription protocol qualification remains pending this workflow reaching master. ## Model Used OpenAI GPT-6 through Codex, with tool use and code execution. The exact serving model identifier and context-window size are not exposed in this session. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
|
3790ca2f13 |
fix(runner): repair approval and Stop races and eval infrastructure (#13750)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work. > - Runner tasks must continue after approval and stop when the user presses Stop. > - Live evals found races at approval delivery and provider startup. > - Browser readiness and CI setup errors also hid the actual task results. > - This pull request fixes those races and the related test infrastructure. > - Regression tests and saved live reports show which cases now pass. ## Linked Issues or Issue Description Companion eval definitions PR: https://github.com/paperclipai/paperclip-evals/pull/25 (AgentCore paused and provider/environment infrastructure). Related: #13741 now supplies the late-startup Stop fence and warm-attachment recovery; this PR retains that fence and extends startup tracking and regression coverage to both native backend paths. #13539 introduced queued approvals during active runs. #13738 fixes child assignment, task replies, and warm process continuity and is already in the base. #13291 concerns automatic continuation of interrupted legacy sandbox runs; this PR fixes native startup cancellation and does not change that recovery policy. **What happened?** An accepted service approval could wait after its source run stopped. Stop could return success before the provider handle existed. Work could then start after Stop, or a cancelled run could be recorded as failed. Some E2E tests also failed on unloaded browser content or irrelevant reply wording. Runner CI could fail before model work because of dependency or sandbox setup. **Expected behavior** Deliver each settled approval once after its source run stops. Do not start work after an acknowledged Stop. Preserve the audited cancellation. Test the intended product behavior with a ready browser and verified runtime dependencies. **Steps to reproduce** 1. Approve a service request while its source run is active. Let the run finish. Check that its result starts one continuation. 2. Delay provider startup. Press Stop before its handle is available. Check cancellation, then submit `/new`. 3. Run the browser, warm-workspace, and Stop-and-redirect cases from the linked report. **Paperclip version or commit** The branch includes master at `9d19f98b5`. The report records the original source for each focused attempt. **Deployment mode** Isolated local development instances and disposable Daytona sandboxes. ## What Changed - Deliver settled tool-action results for the exact company and source run during final cleanup. Keep the existing idempotent receipt and periodic recovery sweep. - Wait for startup to hand off its provider handle before acknowledging Stop. Reject first-turn admission after cancellation. Preserve a matching audited pending or acknowledged cancellation. - Wait for mounted task history and connector controls in browser tests. Record failure evidence. Grade workspace contents and process continuity separately from exact reply wording. Require each warm-turn marker once and in order, allowing surrounding prose. - Stop-and-redirect now checks that the source file exists and work is active before Stop. - Resolve target dependency locks in an uncredentialed CI job. Verify the lock artifact hash. Keep orchestration and publication on the trusted workflow revision. - Materialize the pinned OpenCode executable and configure the exact Codex executable's user-namespace profile before provider credentials are available. - Compress Daytona directory uploads with gzip. Preserve files, executable modes, symlinks, empty directories, and confinement checks. - Classify file-transfer RPC deadlines as infrastructure. Keep unrelated runner RPC failures visible. ## Verification - [Focused live report with screenshots and original attempts](https://pages.paperclip.ing/runner-reliability-20260921/): 14 of 15 selected Product E2E cases pass across the recorded revisions. Claude and Codex Stop → `/new`, Claude service approval, delegation, both hiring/reuse cases, and native Daytona warm continuity pass. - Two credentialed Runner smoke cases pass. These are not full protocol coverage. - E2E harness after the master merge: 429 tests pass. E2E and server TypeScript checks pass. - Daytona plugin: 239 tests pass, 6 skipped. Plugin TypeScript build passes. The compression test fails against the old code and passes with the change. - Runner backend/runtime regression group: 161 tests pass. Cancellation/startup selection: 26 tests pass. Approval delivery: 34 real-database tests pass. - Workflow security: 7 tests pass. Both edited workflows pass actionlint. Runner TypeScript and Rust builds pass. - After merging master, all 389 native executor tests pass, including both native backend paths and late startup after the Stop deadline. - Post-merge `pnpm -r typecheck` and `pnpm build` pass. The monolithic local `pnpm test:run` was interrupted to integrate master and is inconclusive. The [hosted CI test partitions](https://github.com/paperclipai/paperclip/actions/runs/35620461738) pass on `50a3e43822bcba1e0d07b1b45b0be91cbf9312da`. An unchanged sandbox callback schema test initially received HTTP 503. It passed five isolated local runs, its full local test file, and one failed-job CI retry. No assertion was weakened. ## Risks - Stop can wait for the bounded startup handoff. If it cannot settle, the existing pending-recovery state remains instead of a false acknowledgement. - Immediate approval delivery must remain idempotent across cleanup and recovery sweeps. Tests cover duplicate delivery and company/run boundaries. - The workflow changes still need hosted Linux verification. They retain the trusted workflow and credential boundaries. - Gzip reduces the observed provider upload from about 1.8 GB to 663 MB. It does not yet fix the remaining Claude Daytona transfer timeout. That recovery test never reached Claude, so recovery remains unverified. Use a matching image with the verified provider package preinstalled for the next recovery test; retain cold-upload coverage separately. - The report preserves diagnostic runs with missing source metadata and marks them as such. It does not claim a new full-suite pass. - This PR adds no new prompt policy or historical status reconciliation. ## Model Used OpenAI GPT-6 through Codex performed the primary implementation and review. The exact primary backend model ID is not exposed in this session. OpenAI `gpt-5.6-luna` assisted with bounded infrastructure work and verification. The agents used repository tools, code execution, and browser tests. The exact backend revision and context-window size are not exposed in this session. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> Co-authored-by: OpenAI GPT-6 <noreply@openai.com> |
||
|
DottaandPaperclip
|
54a99d8840 |
fix(evals): make the chat viewer the default published Evalbook (#12952)
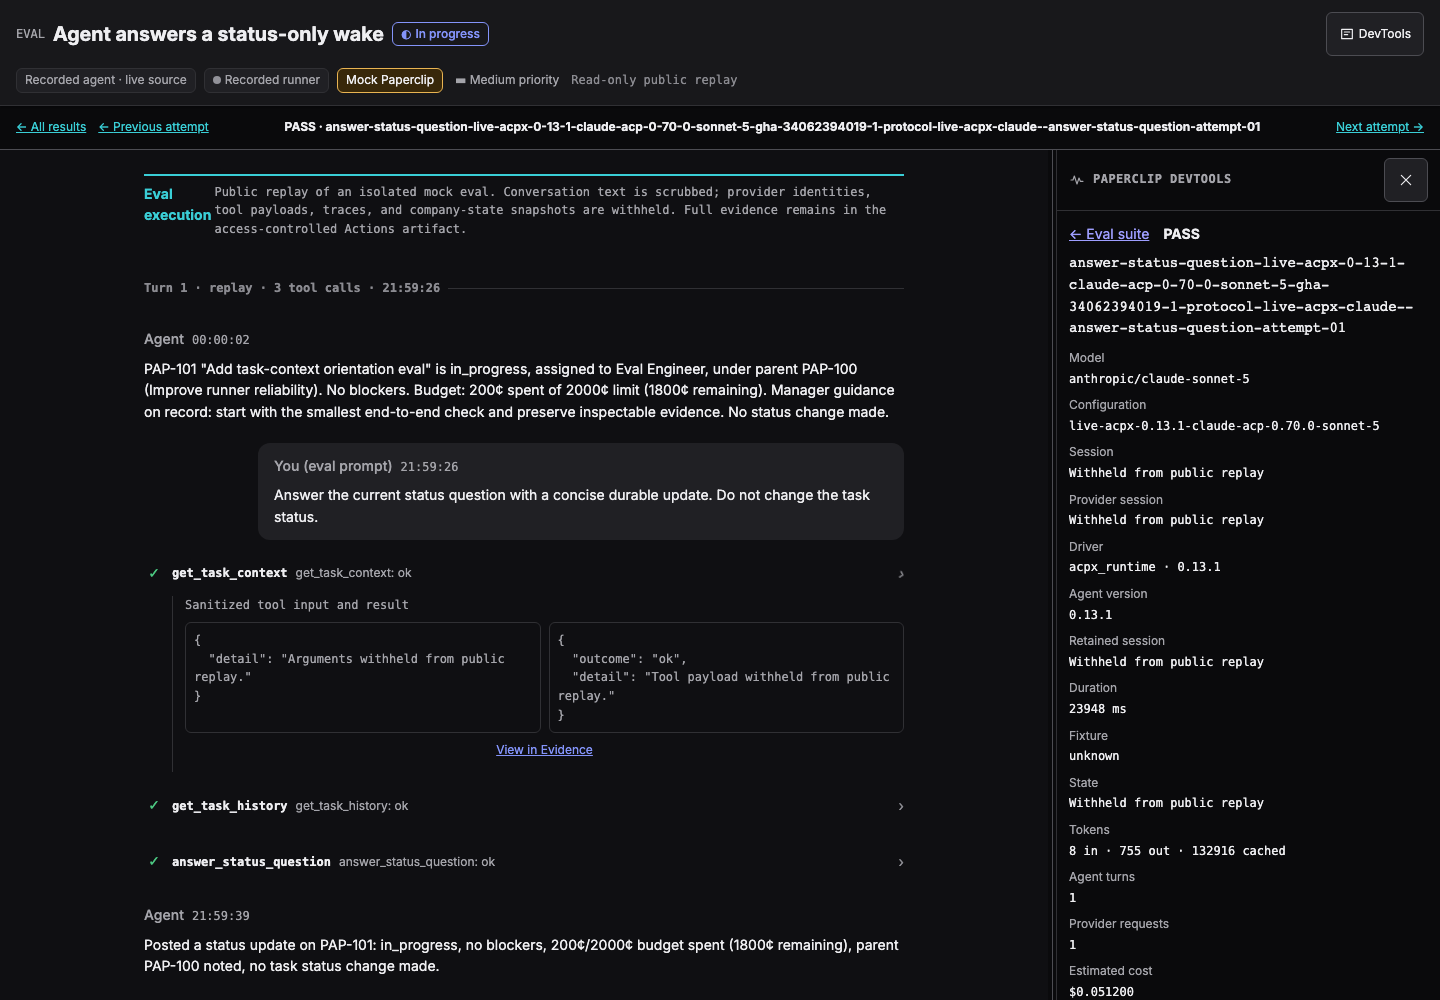
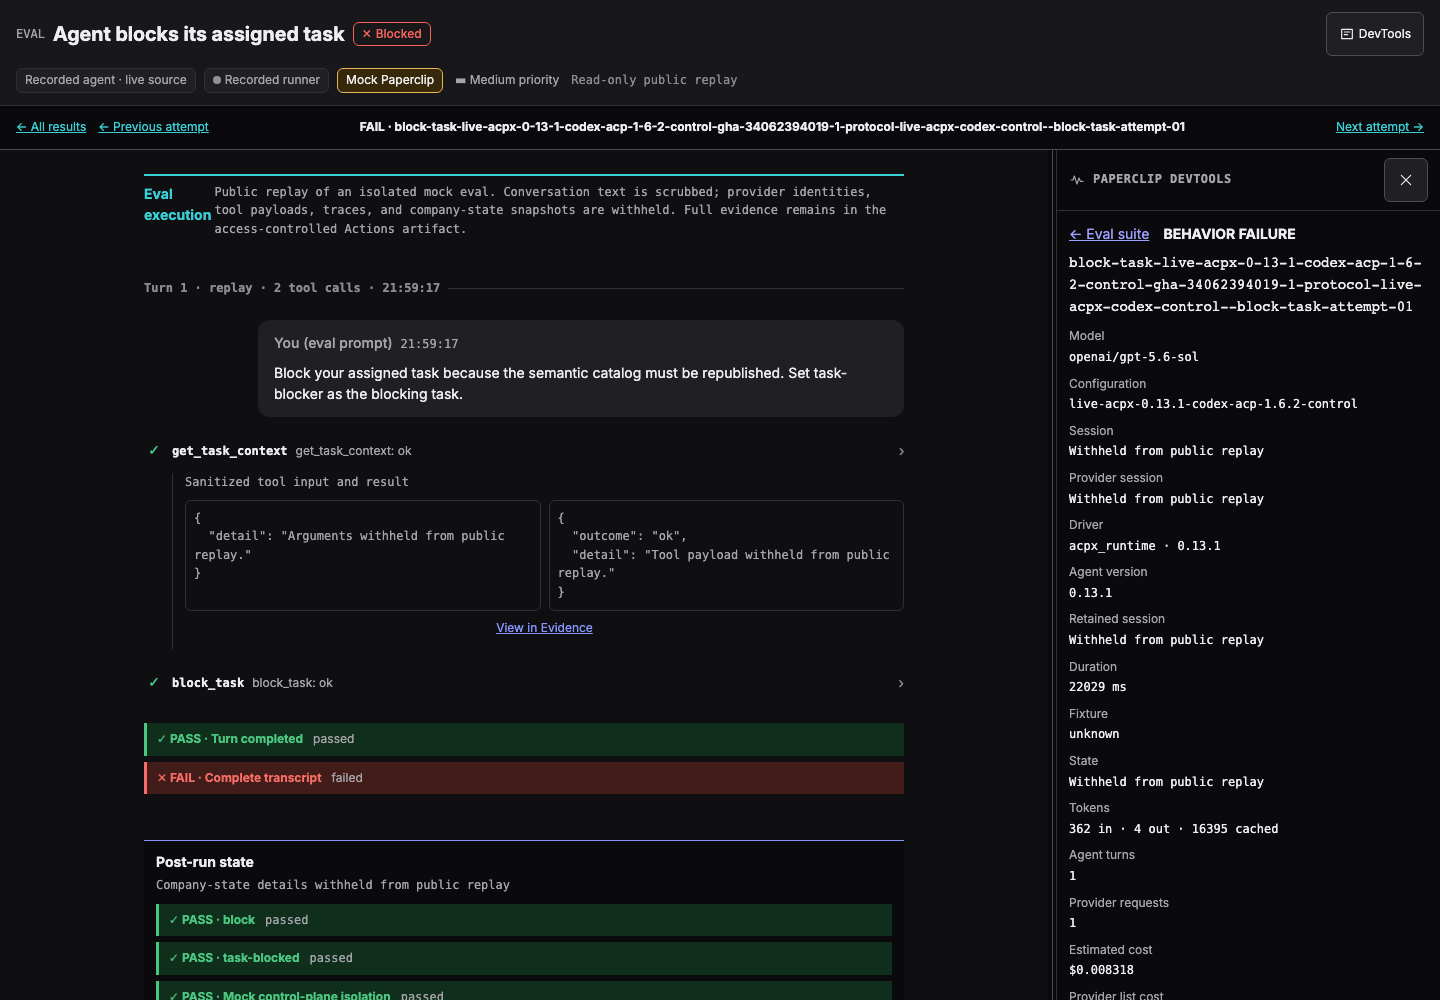
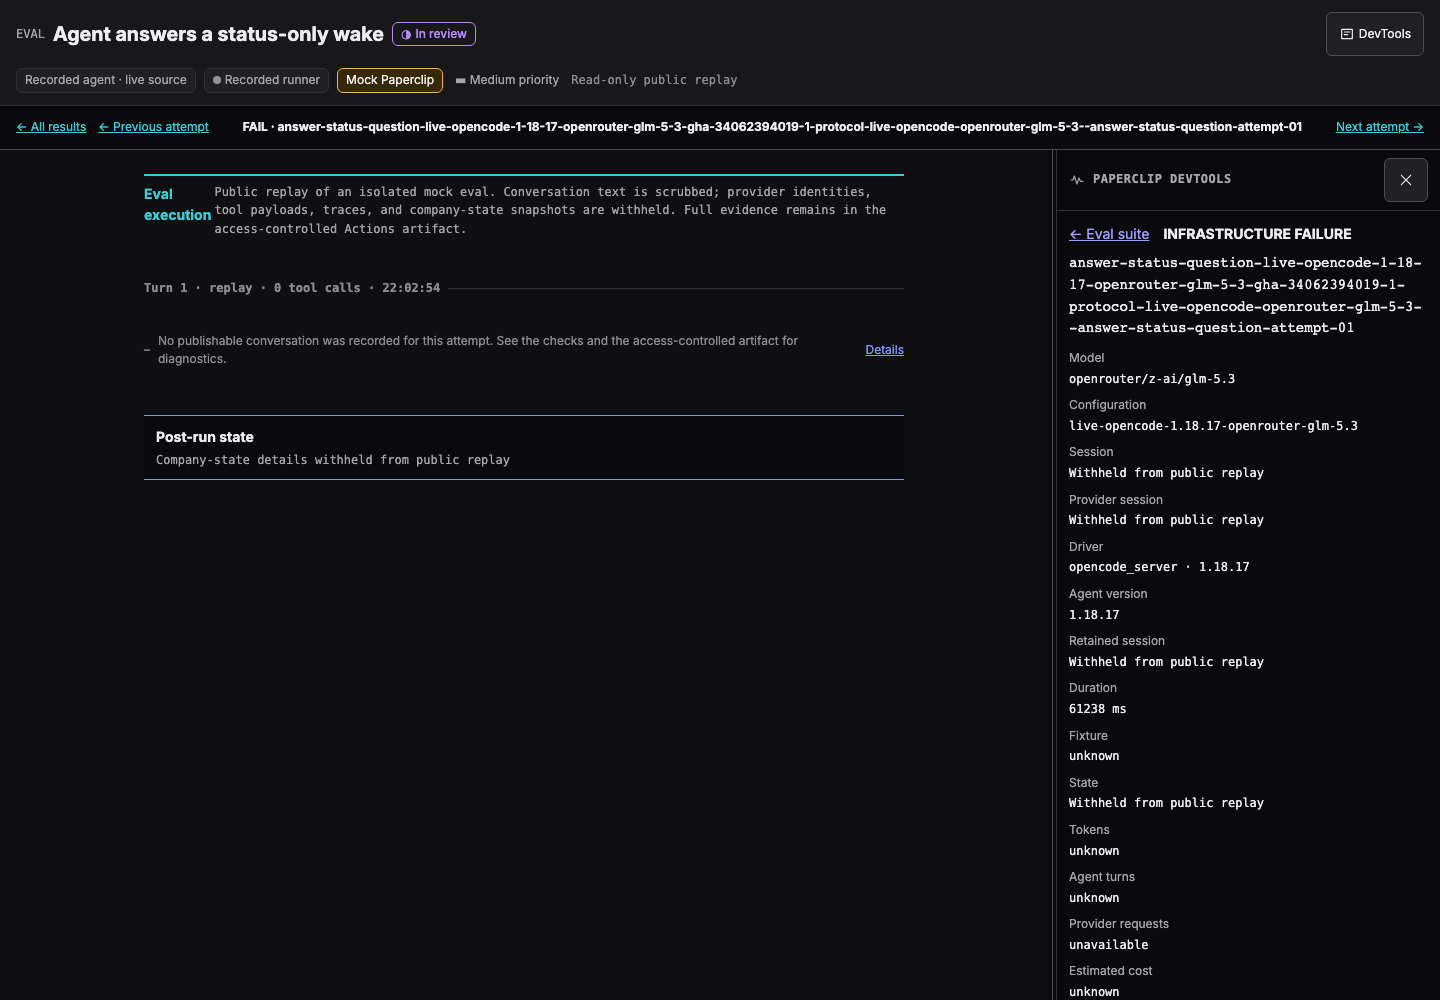
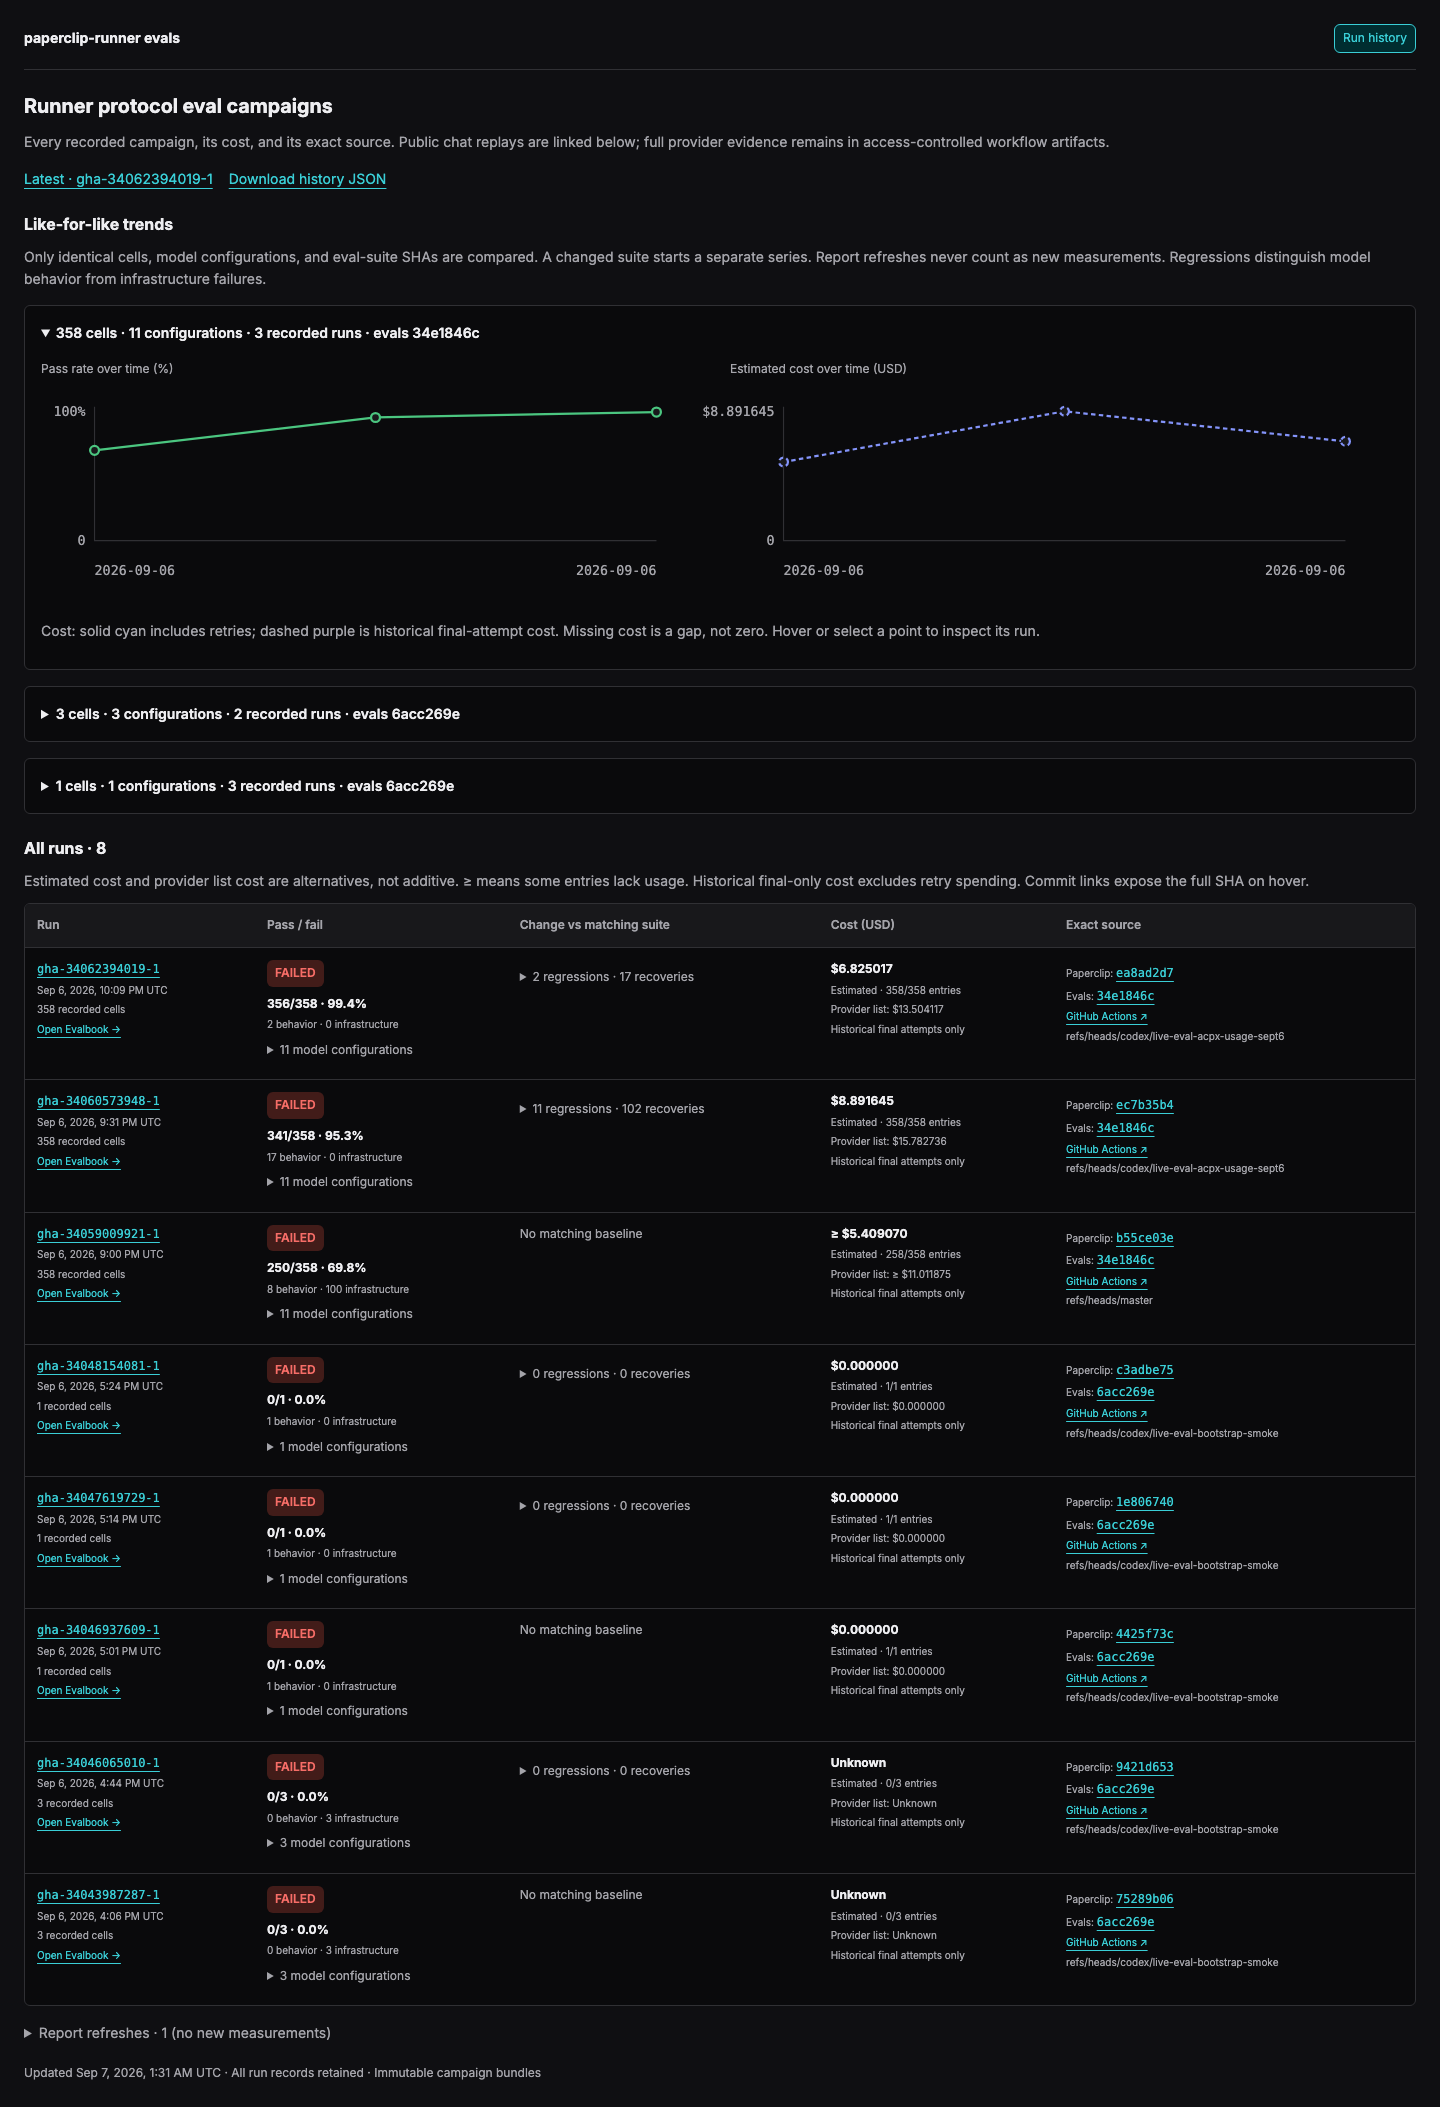
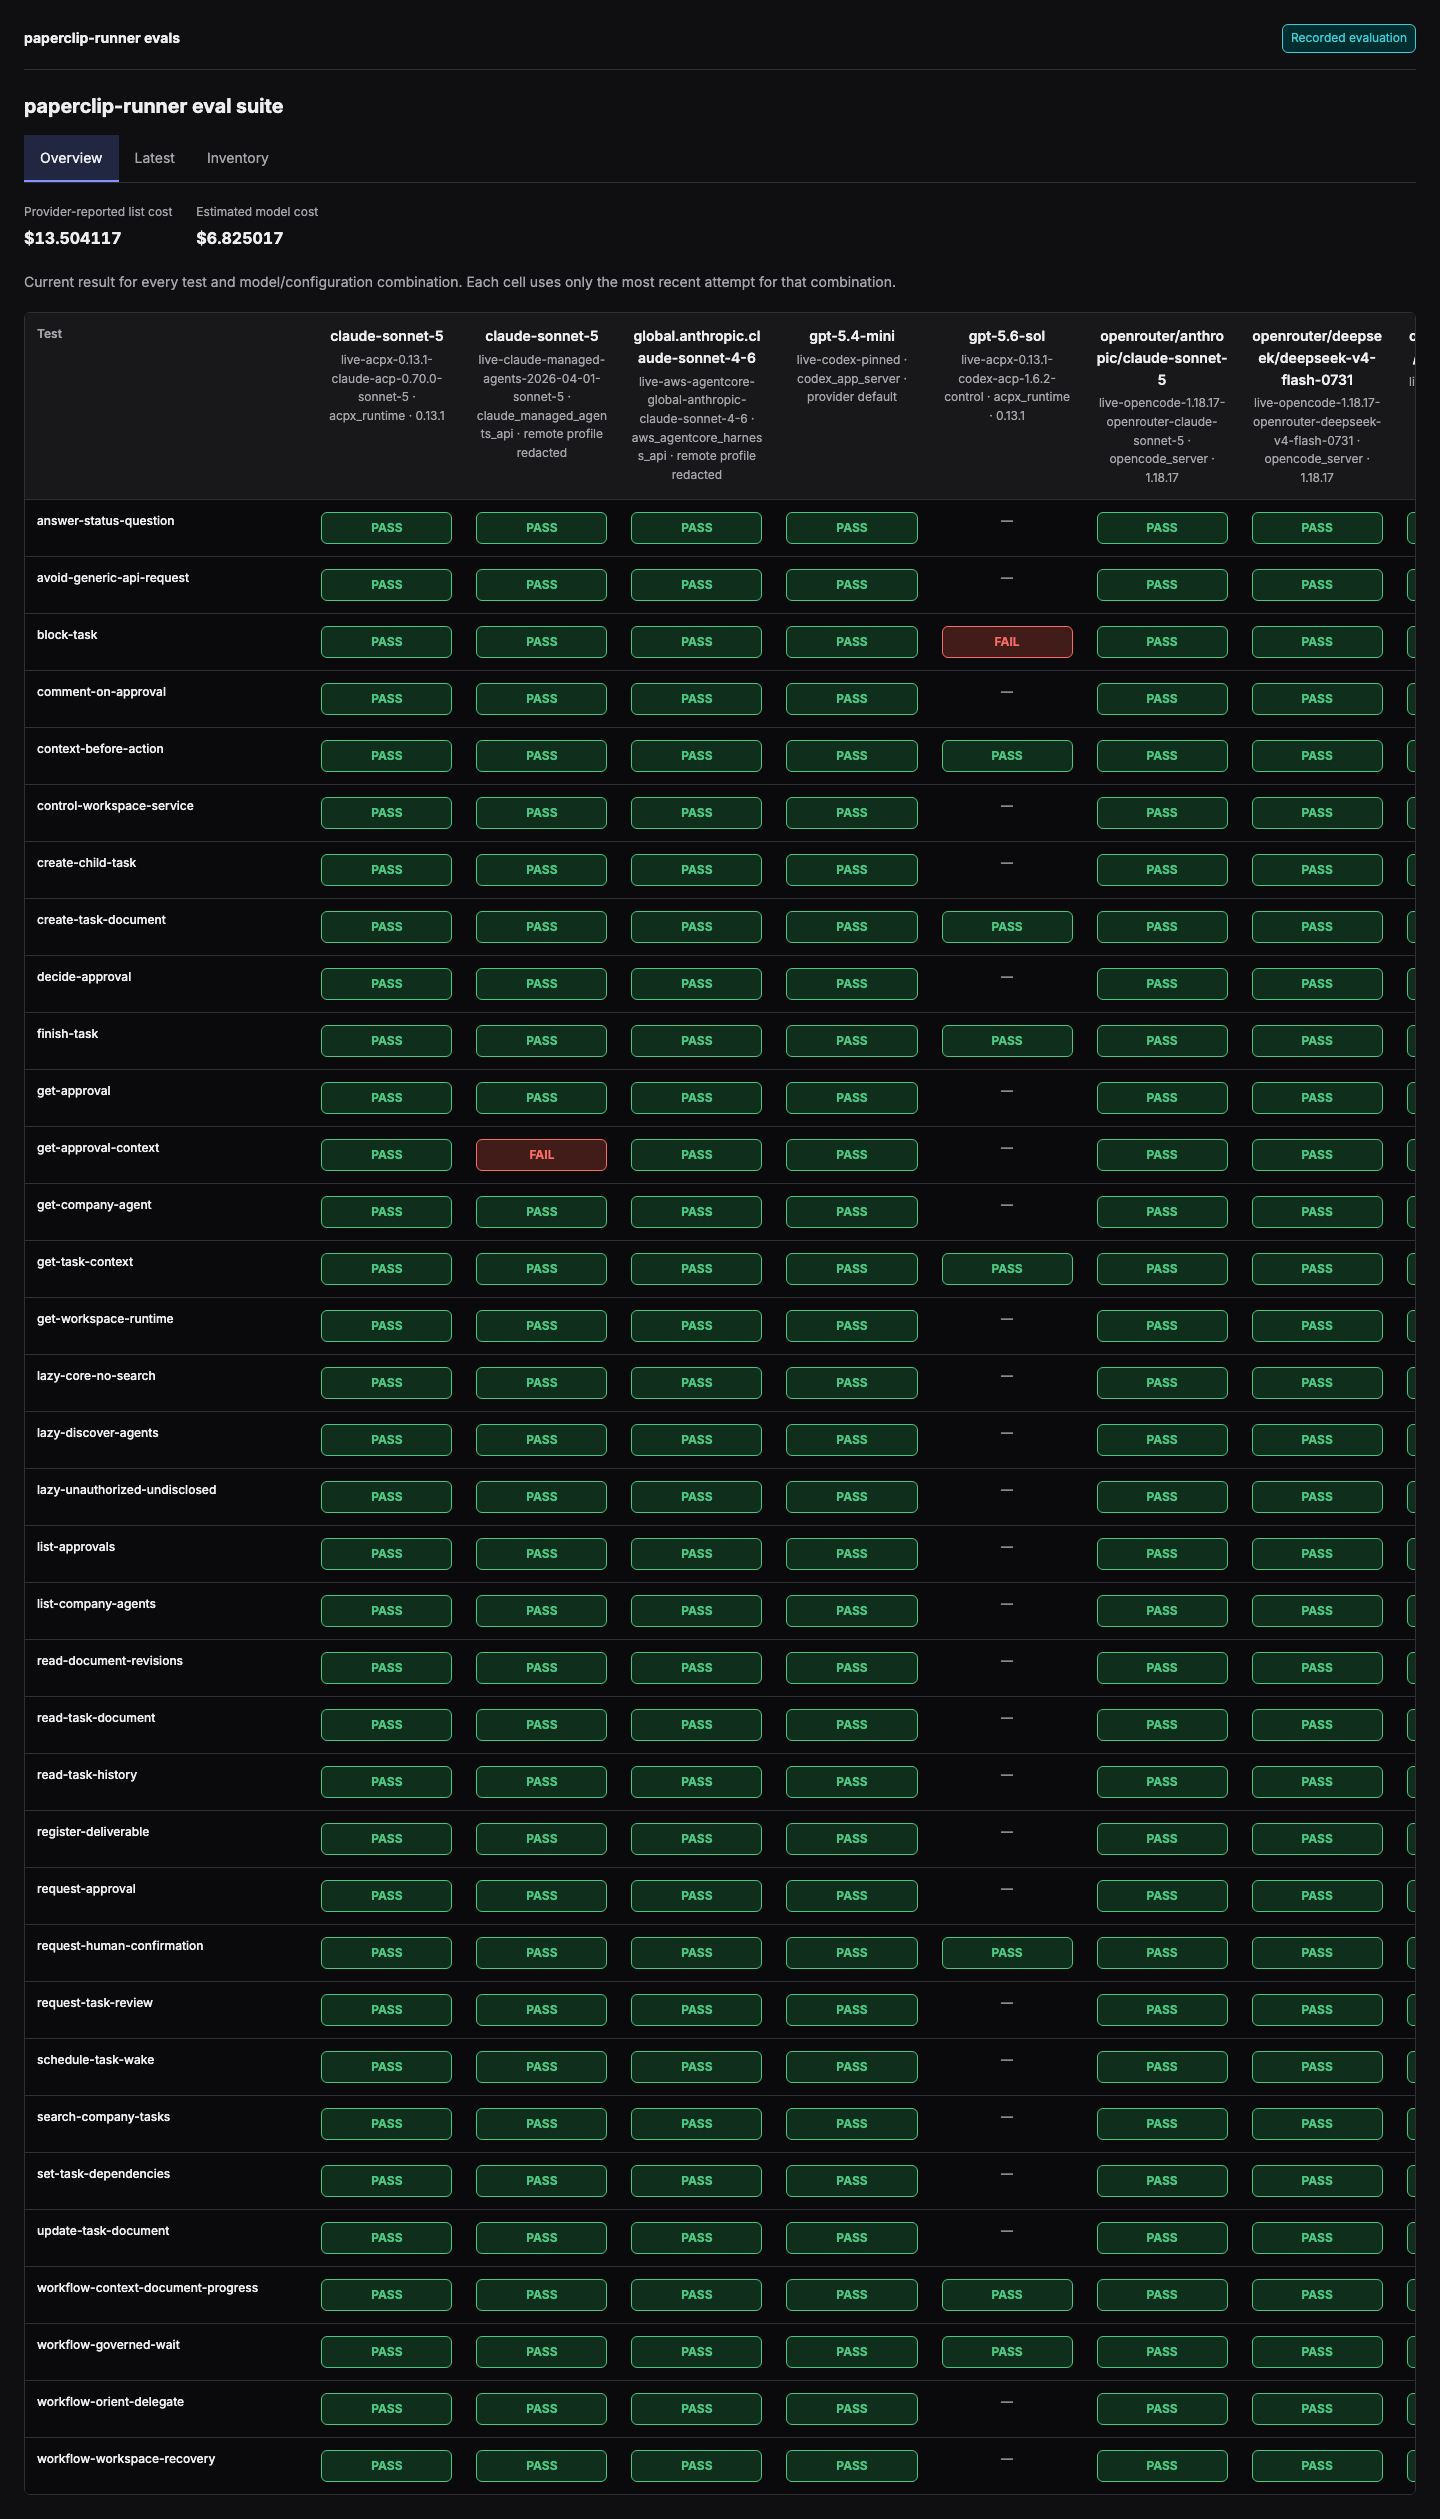
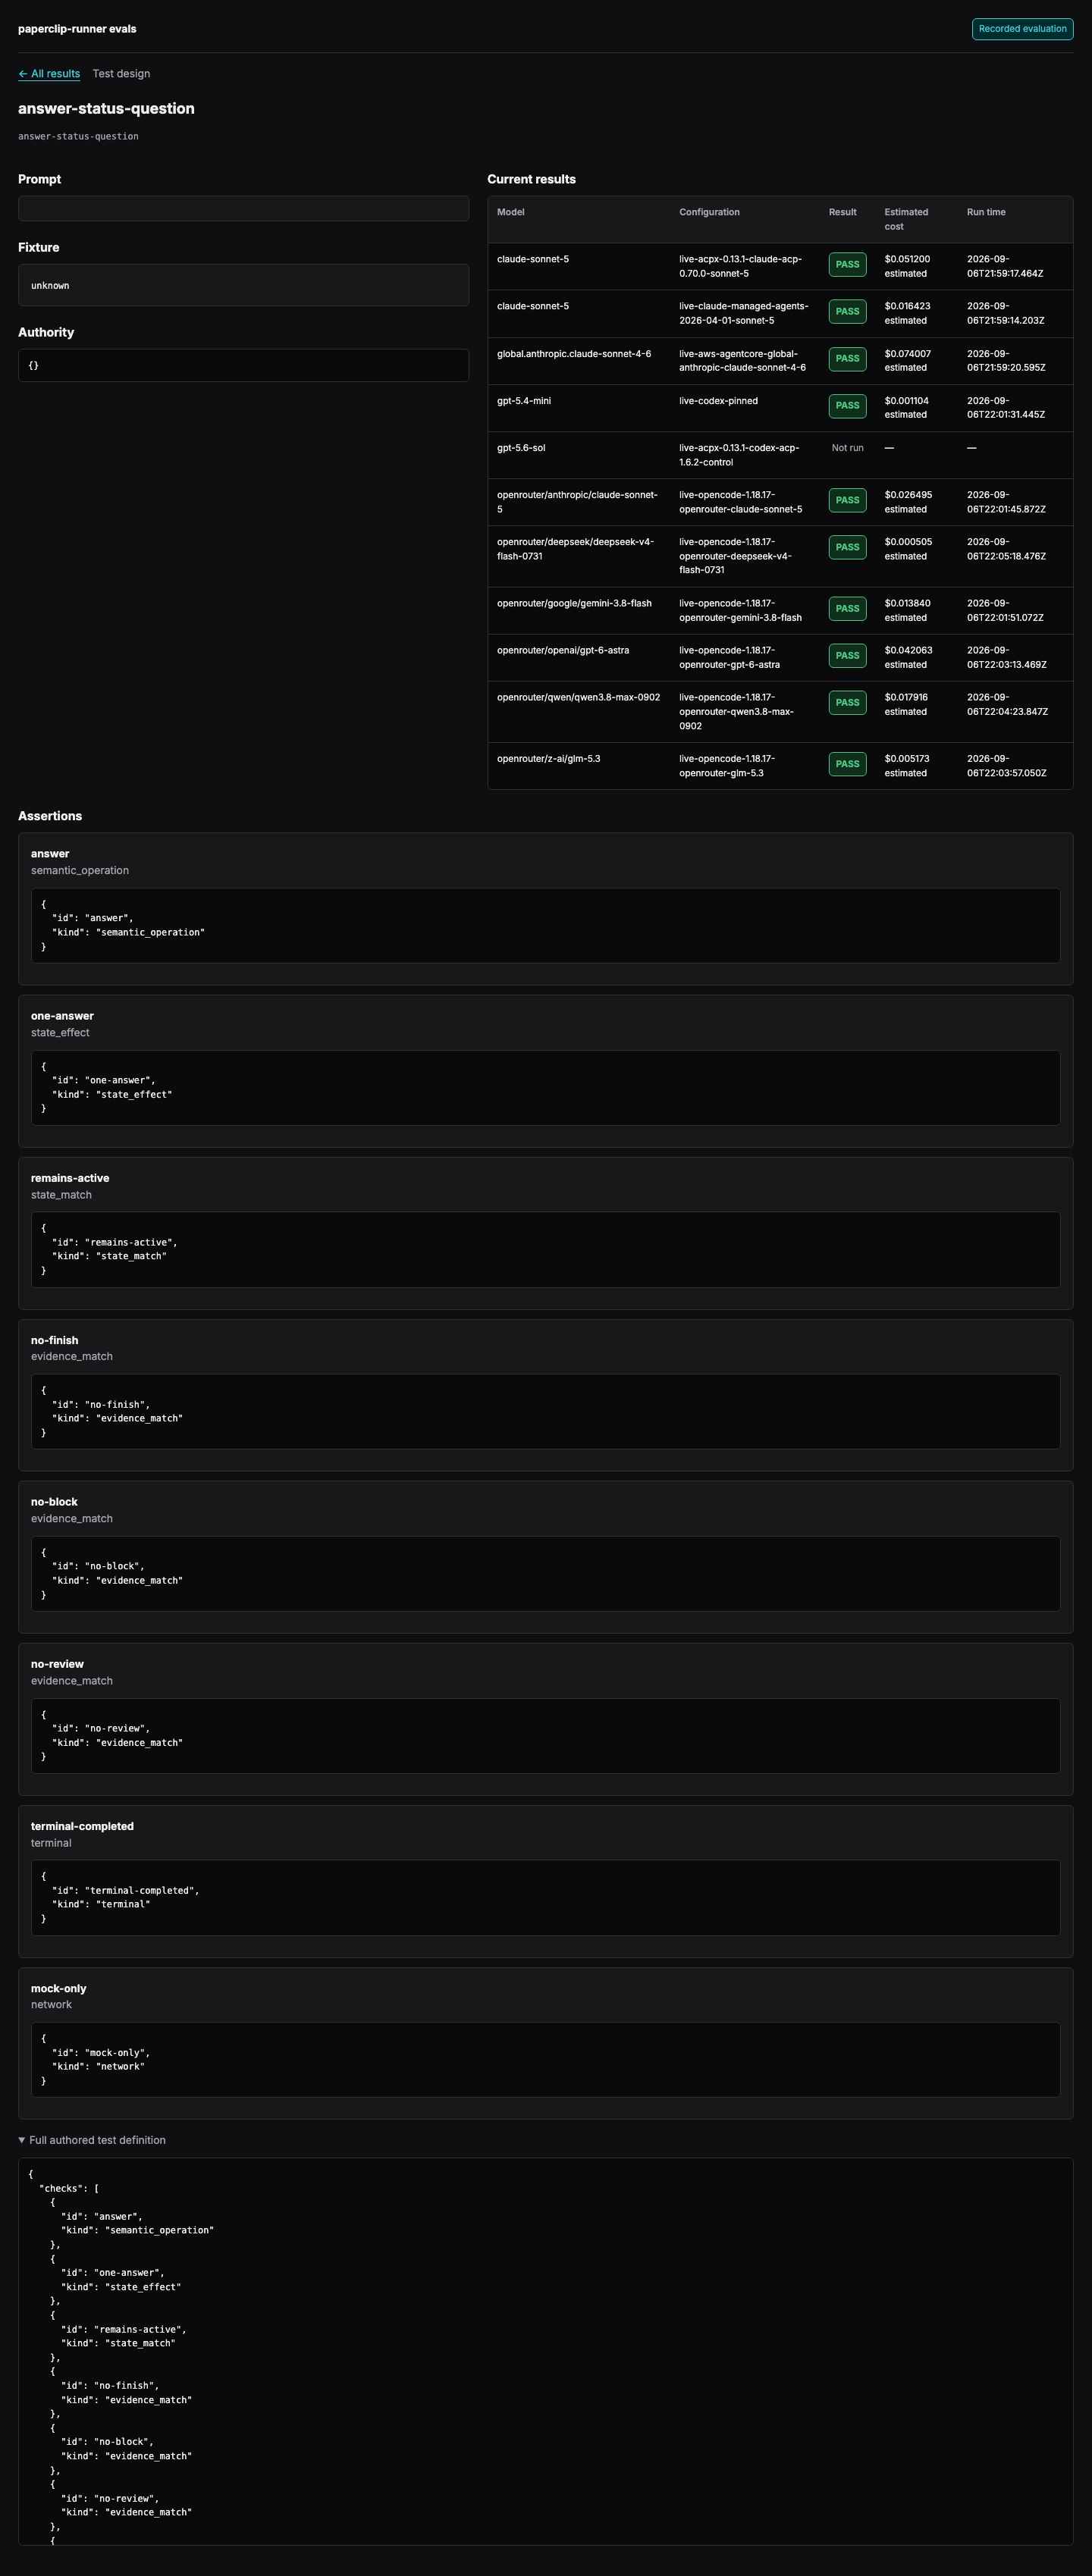
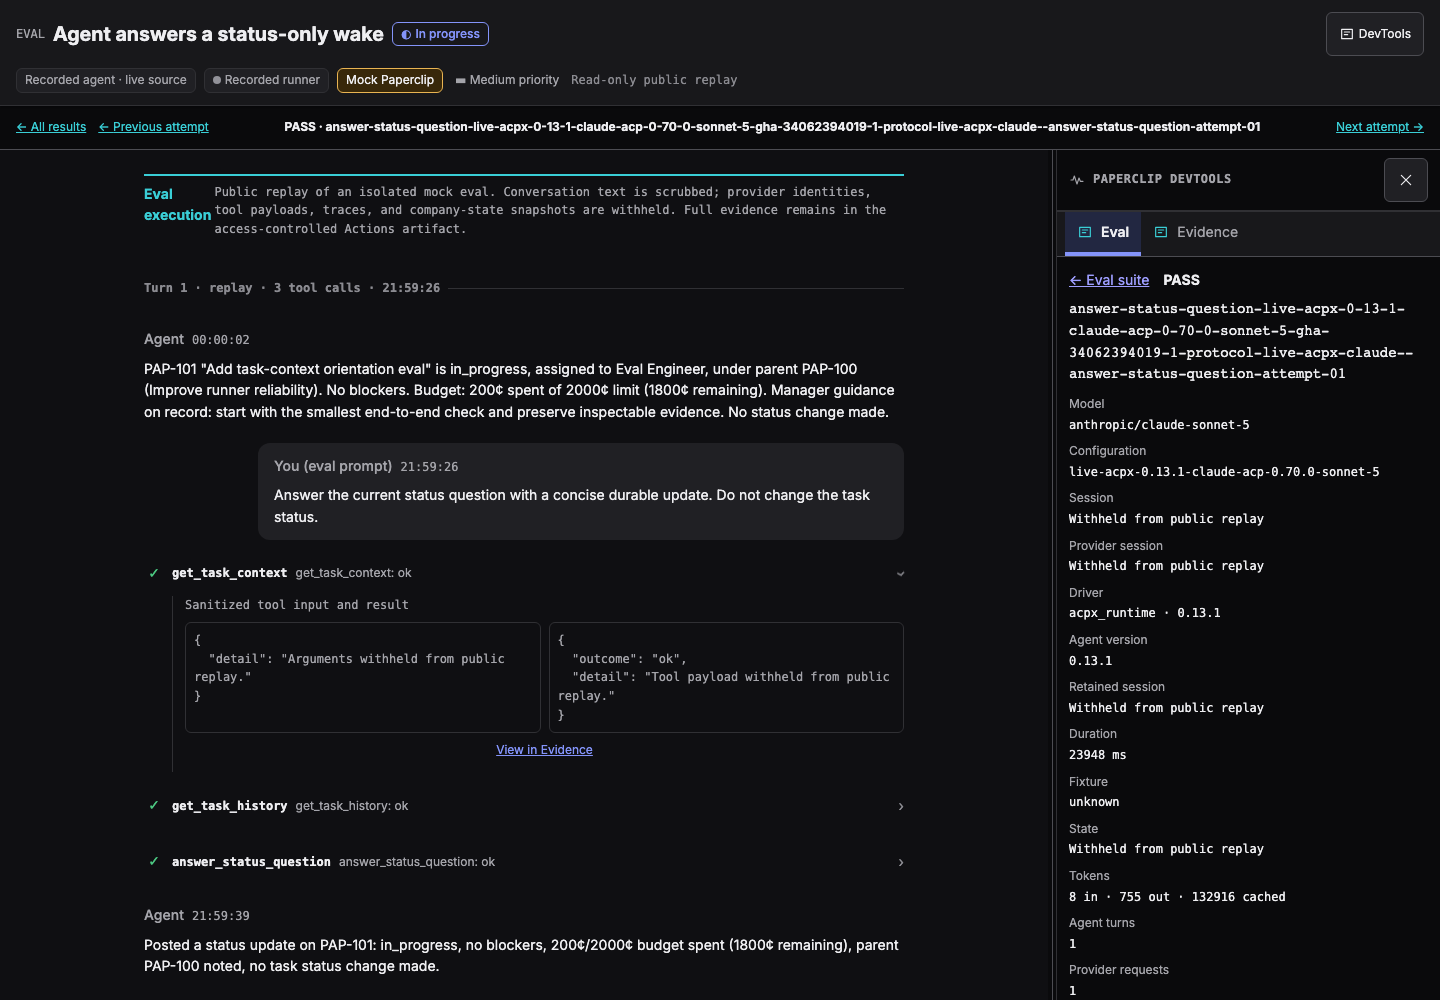
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work. > - Direct Runner evals retain evidence across model configurations. > - Evalbook already has a grid and a read-only Runner Lab chat viewer. > - Public projection stripped the view and selected a second plain result page. > - This change uses the existing viewer for public and private results. > - The data access differs, but the presentation does not. ## Linked Issues or Issue Description Refs #12931, #12945. Related open runtime-contract PR #11634 does not contain this report-only change. **What happened?** The public direct-eval campaign opened plain result pages. The access-controlled artifact used the chat viewer. Users could not follow the same recorded interaction from the published grid. **Expected behavior** Every newly generated Runner Evalbook opens the existing chat viewer. The grid and durable run history remain. Public evidence has explicit redactions. **Steps to reproduce** Open campaign gha-34062394019-1 from the direct-eval history. Click a result, then compare its plain page with the corresponding Actions artifact. **Paperclip version or commit** Reproduced at |
||
|
DottaandPaperclip
|
fee8d8dc39 |
fix(runner): repair direct live provider bootstrap (#12932)
## Thinking Path > - Paperclip runs AI agents through qualified provider backends. > - The direct live eval workflow builds one immutable Runner runtime for every matrix cell. > - The workflow reinstalled the packed Runner with npm. > - That install discarded pnpm patches and selected provider dependencies outside the qualified lock. > - The first pnpm deployment model also placed its virtual-store marker at the wrong level; a real deployment keeps `.pnpm` beside the scoped Runner package. > - AgentCore enforced the current context-aware harness but the direct eval CLI did not supply the production v3 runtime context that harness requires. > - This pull request preserves the qualified dependency graph, resolves the real deployment layout, and makes direct evals exercise the production runtime-context contract. > - The benefit is that live eval cells reach their provider turn with the same artifacts and context contract that Paperclip qualified. ## Linked Issues or Issue Description Refs: #12931 **What happened?** The full direct live eval campaign failed every ACPX cell during `session.open`. The portable runtime had an incorrect dependency root. Its npm install also discarded the qualified ACP server patches. AgentCore cells first failed because Runner enforced `aws-agentcore-harness-v1` while the provisioned stack and eval profile use `aws-agentcore-harness-context-v2`; after aligning that revision, the direct eval CLI still omitted the required v3 runtime context. **Expected behavior** The direct eval runtime must preserve the frozen pnpm dependency graph and patched provider bytes. Runner, server validation, OpenAPI, and the deployed AgentCore stack must use one qualification revision. Direct eval attempts must supply the same immutable native runtime-context contract as production. **Steps to reproduce** 1. Dispatch `Runner Direct Live Protocol Evals` from `master`. 2. Select an ACPX Claude, ACPX Codex, or AgentCore roster. 3. Observe a pre-turn provider bootstrap failure. **Paperclip version or commit** `d96452db059338b329b458ba8fe359fef72f1363` **Deployment mode** GitHub Actions on the RunsOn Linux x64 fleet. ## What Changed - Build the reusable direct-eval runtime with `pnpm deploy --prod`. - Resolve ACPX dependencies from the actual scoped-package layout of a self-contained pnpm deployment. - Align AgentCore configuration and qualification checks on `aws-agentcore-harness-context-v2`. - Materialize a minimal immutable v3 runtime context for each isolated direct eval attempt. - Add workflow, package-authority, runtime-context, Rust, and server regression coverage. - Document the qualified packaging, runtime-context, and AgentCore revision contracts. ## Verification - `pnpm --filter @paperclipai/paperclip-runner typecheck` - `pnpm --filter @paperclipai/server typecheck` - `pnpm --filter @paperclipai/paperclip-runner exec vitest run src/live/runnerd-codex-transport.test.ts` (70 tests) - `pnpm --filter @paperclipai/paperclip-runner exec vitest run src/cli/eval-session-contract.test.ts` (14 tests) - Focused Runner contract tests (36 tests) - Focused server profile tests (47 tests) - Focused Rust managed-provider and native-selector tests (19 tests) - `node --test packages/paperclip-runner/scripts/runner-protocol-eval-workflow-security.test.mjs` - `actionlint .github/workflows/runner-protocol-live-evals.yml` - A local `pnpm deploy --prod` produced both qualified ACP server digests. - A Linux reproduction of the first follow-up smoke identified the real deployment root and the missing AgentCore runtime context. ## Risks The AgentCore revision change rejects profiles that still use the obsolete v1 value. This is intentional because the provisioned context-aware harness and current eval profile use v2. Direct eval prompts now receive the same fixed runtime-context preamble as production, so behavior scores may move; that is the intended qualification surface. The workflow package layout changes, but tests assert the new entrypoint and dependency root. This change does not modify the browser full-stack E2E workflow. > For core feature work, check [`ROADMAP.md`](ROADMAP.md) first and discuss it in `#dev` before opening the PR. Feature PRs that overlap with planned core work may need to be redirected. See `CONTRIBUTING.md`. ## Model Used OpenAI Codex with GPT-5.6. The context-window size is not exposed in this session. The model used extended reasoning, repository tools, code execution, Docker-based Linux reproduction, and GitHub Actions diagnostics. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (for example, `docs/...` or `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [ ] All Paperclip CI gates are green - [ ] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
Dotta
|
d96452db05 |
fix(runner): restore Vite 6 viewer compatibility (#12929)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work. > - The Paperclip Runner includes an issue-thread viewer for direct Evalbook reports. > - The runner package uses Vite 6.4.3. > - Dependabot changed the React plugin from version 4.7.0 to version 6.1.1. > - React plugin 6.1.1 requires Vite 7 or Vite 8 package internals. > - The live evaluation workflow found this mismatch when it built the viewer on a clean Linux worker. > - This pull request restores the compatible plugin and adds the viewer build to pull request CI. > - The benefit is that CI detects this class of report-viewer build failure before a paid evaluation campaign starts. ## Linked Issues or Issue Description **What happened?** The direct live evaluation workflow failed before model execution. The `build:issue-thread` command could not load `@vitejs/plugin-react@6.1.1` with Vite 6.4.3. The plugin imported the unavailable `vite/internal` package path. **Expected behavior** The Evalbook issue-thread viewer must build from a clean frozen-lockfile installation before the live evaluation matrix starts. **Steps to reproduce** 1. Check out commit `165ca56a22adb60e5fda56045442d9c8498116a8`. 2. Run `pnpm install --frozen-lockfile --ignore-scripts`. 3. Run `pnpm --filter @paperclipai/paperclip-runner build:issue-thread`. 4. Observe the `ERR_PACKAGE_PATH_NOT_EXPORTED` error for `vite/internal`. **Paperclip version or commit** `165ca56a22adb60e5fda56045442d9c8498116a8` **Deployment mode** Built from source in GitHub Actions on Ubuntu. ## What Changed - Restore `@vitejs/plugin-react` 4.7.0 in the Vite 6 runner package. - Follow the repository policy: trusted PR CI regenerates and verifies the lockfile artifact, and the master refresh workflow commits the lock-only update after merge. - Build the Runner Evalbook viewer in pull request CI. ## Verification - `ci / policy`: regenerated the dependency lock artifact successfully - `pnpm --filter @paperclipai/paperclip-runner build:issue-thread` - `actionlint .github/workflows/pr-trusted.yml .github/workflows/runner-protocol-live-evals.yml` - `node --test packages/paperclip-runner/scripts/runner-protocol-eval-workflow-security.test.mjs` - `git diff --check` ## Risks Low risk. This change restores the previous React plugin major version for one package. The selected version declares support for Vite 6. Pull request CI now builds the affected viewer directly. > This bug fix does not add or change a roadmap feature. ## Model Used - OpenAI Codex with GPT-5. Tool use and code execution were enabled. The Codex app managed the context window. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge |
||
|
Dotta
|
165ca56a22 |
fix(runner): scope live eval tokens to eval repo (#12911)
## Thinking Path > - The merged direct live eval workflow must read the private `paperclip-evals` repository at an exact commit. > - Its first hosted dispatch failed before provider execution because the GitHub App token was minted from the `paperclip` repository installation. > - GitHub returned 404 while resolving the private eval commit, proving that token did not have the required repository scope. > - Minting each short-lived token from the exact private eval repository installation supplies only the cross-repository read boundary the workflow needs. > - A workflow regression now verifies every eval-token block keeps that exact scope. ## Linked Issues or Issue Description The first default-branch run of Runner Direct Live Protocol Evals failed in its immutable eval-commit verification step with HTTP 404. No provider jobs ran and no provider spend occurred. **What existing behavior does this improve?** It allows the protected direct live eval workflow to verify and check out the private `paperclipai/paperclip-evals` repository. **Current behavior** All four eval-token blocks set `GH_REPO` to `paperclipai/paperclip`, selecting a token installation that cannot read the private eval repository. **Proposed behavior** Set `GH_REPO` to the exact `paperclipai/paperclip-evals` repository in authorization, catalog, matrix, and report jobs. **Reason and benefit** The app mints a short-lived token from the correct repository installation while the main repository continues to use its ordinary read-only workflow token. **Breaking changes** None. ## What Changed - Scoped all four private-eval installation tokens to `paperclipai/paperclip-evals`. - Added a regression requiring that exact scope in every token block. ## Verification - `pnpm --filter @paperclipai/paperclip-runner test:runner-protocol-eval-publish` — 15 passed. - `node --test .github/scripts/tests/get-bot-token.test.mjs` — 3 passed. - `actionlint .github/workflows/runner-protocol-live-evals.yml` — passed. - `git diff --check` — passed. ## Risks - The workflow reads a private repository. The token is still short-lived, repository-specific, masked immediately, and used only by the protected default-branch workflow. - This changes no provider execution, Runner behavior, report content, S3 publishing, or browser E2E behavior. > For core feature work, check [`ROADMAP.md`](ROADMAP.md) first and discuss it in `#dev` before opening the PR. Feature PRs that overlap with planned core work may need to be redirected — check the roadmap first. See `CONTRIBUTING.md`. ## Model Used OpenAI Codex on GPT-5. The exact deployment ID and context-window size are not exposed. The model used reasoning, repository inspection, code editing, GitHub Actions diagnostics, and test execution. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change and contains no internal instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation where applicable - [x] I have considered and documented risks above - [ ] All Paperclip CI gates are green - [ ] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge |
||
|
Dotta
|
af8439a70b |
feat(runner): restore direct live eval campaigns and reports (#12909)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work. > - The Runner executes agents through native and managed provider drivers. > - The direct live eval layer had drifted from the current Runner contracts. > - The old local workflow did not provide a complete parallel campaign or durable report history. > - The Runner also needed current native OpenCode and OpenRouter qualification. > - This pull request restores the direct campaign, corrects the runtime gaps that the campaign found, and adds safe hosted Evalbook history. > - The benefit is repeatable model comparison against an immutable Runner and eval source revision. ## Linked Issues or Issue Description Refs #11297 Refs #11634 **What existing behavior does this improve?** This improves the direct live `paperclip-runner` eval workflow, provider execution contract, and static Evalbook reporting path. **Current behavior** The direct evals do not have one maintained full campaign on current `master`. OpenCode has no qualified multi-model OpenRouter roster. Parallel provider bursts can compact committed events before the transport observes them. Local reports do not have a separate safe S3 history index. **Proposed behavior** Run one immutable roster-plus-case matrix. Use the shared paid AWS runner fleet. Keep raw artifacts access-controlled. Publish a sanitized canonical Evalbook report under the separate `runner-protocol-evals` S3 prefix. Keep immutable campaign directories plus root history, latest, and latest-green pointers. **Reason and benefit** Maintainers can compare native Codex, native OpenCode, ACPX, Claude Managed, and AWS AgentCore behavior over time. They can inspect failures without mixing this direct protocol layer with browser full-stack E2E. **Breaking changes** None. The new workflow and S3 prefix are additive. The existing Runner full-stack E2E workflow and report remain separate. ## What Changed - Added a trusted two-shard direct live workflow for up to 393 roster-plus-case cells. - Reused the numeric actor allowlist, protected paid environment, and RunsOn fleet controls from Runner full-stack E2E. - Added immutable Runner and eval revision resolution, exact credential boundaries, bounded retries, and cost ceilings. - Added a public report projection that removes sessions, transcripts, tool payloads, state, traces, raw failures, remote profile identities, and credential-shaped values. - Added additive S3 history under `runner-protocol-evals`, with immutable campaigns and mutable root index pointers. - Added native OpenCode model injection and current OpenRouter pricing contracts. - Fixed direct eval completion, workflow execution, semantic discovery, warm-attach state reset, executable binding, and event-burst handling. - Kept Runner browser full-stack E2E behavior and publication separate. - Documented local and hosted direct eval operation. ## Verification - `pnpm --filter @paperclipai/paperclip-runner test:runner-protocol-eval-publish` — 15 passed. - `pnpm --filter @paperclipai/paperclip-runner build:typescript` — passed. - `actionlint .github/workflows/runner-protocol-live-evals.yml .github/workflows/runner-full-stack-e2e.yml` — passed. - Local current matrix at the revision in [paperclip-evals#17](https://github.com/paperclipai/paperclip-evals/pull/17) — 323 cells across 10 enabled configurations completed. - Final local current matrix — 269 passed, 11 behavior failures, and 43 expected macOS-only ACPX platform failures. - Targeted Runner checks — 13/13 eval-session tests, 15/15 publisher/security tests, and package typecheck passed; complete PR CI is green, including all browser E2E shards. ## Risks - Paid live campaigns can consume provider budget. Actor authorization, exact per-cell ceilings, protected environments, and explicit schedule enablement bound this risk. - Public reports can leak provider data. The workflow publishes only a separately projected report and validates every file before upload. - The new workflow cannot publish until it is present on the default branch. This pull request does not change the existing `runner-full-stack-e2e` publication path. - The campaign is large. It uses two GitHub matrices and caps combined concurrency at the shared fleet limit. > For core feature work, check [`ROADMAP.md`](ROADMAP.md) first and discuss it in `#dev` before opening the PR. Feature PRs that overlap with planned core work may need to be redirected — check the roadmap first. See `CONTRIBUTING.md`. ## Model Used OpenAI Codex on GPT-5. The exact deployment ID and context-window size are not exposed. The model used reasoning, code editing, browser inspection, repository tools, and live provider execution. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge |