mirror of
https://github.com/paperclipai/paperclip.git
synced 2026-11-04 02:32:07 +01:00
572bef4ba7679451ac1543db25cb8ebd533bf919
8
Commits
| Author | SHA1 | Message | Date | |
|---|---|---|---|---|
 DottaandPaperclip |
57e977be72 |
feat: integrate Pi 1.0 into the experimental Runner (#14921)
## Thinking Path > - Paperclip manages AI agents and their work. > - The experimental Runner owns provider processes and durable sessions. > - Pi needs working task execution and human controls. > - The five-PR stack must preserve changes already on master. > - Each layer now carries the complete integrated source for a safe sequential fallback. > - This PR belongs to native GitHub stack #15602, ending at #14956. ## Linked Issues or Issue Description Refs #14436, #14631, #14743 and #14956. Ship Pi 1.0 through the experimental Paperclip Runner. The five PRs are #14921, #14922, #14923, #14924 and #14956. The user authorized the complete merge after checks pass. Existing `pi_local` execution is unchanged. Accounting and wider provider/platform qualification remain deferred. ## What Changed - Recover missing final replies after workspace finalization changes owners, using accepted-turn evidence without rerunning work or granting external-chat publication. - Preserve the admitted Pi instruction root across warm runs, while retaining changed-root rejection. - Give Pi a bounded 15-second default shutdown grace so stop, drain acknowledgement and durable suspension can complete. Explicit deadlines and other providers retain their existing behavior. - Integrate the Pi 1.0 runtime and master contracts. - Use Pi profile 22. Preserve explicit caller-selected models and exact native thinking levels. Keep Pi's wrapper, helper, extension and question/control behavior unchanged from the qualified profile-19 runtime. - Preserve master's Dot lifecycle and consent fields, configured task environment, status guards and current Codex/Claude dependency versions. Cursor stays qualified. Copilot stays pending; profile 17 binds the changed shared protocol validation sources. - Exclude general AWS IAM credentials from Pi static/custom provider bindings and selected task projections; preserve the provider-scoped Bedrock bearer key. Profile 21 is retained as historical provenance. Rust and cloud install probes use the current declaration. - Patch bundled brace-expansion 5.0.9 to the exact official 5.0.12 payload. Pin the patch and complete runtime closures. Include the patch in normal installed setup tooling. Keep the upstream Pi shrinkwrap as provenance and permit only this exact security correction. - Include current attestation files in the Docker build context. Keep the repository lockfile unchanged from master. CI and private image builds resolve manifest changes before their frozen installation. ## Verification - Full local `pnpm -r typecheck` passes, including Runner Rust, server and UI. Focused integration checks pass: 194 Runner admission/environment tests, 63 profile/credential tests with one expected skip, 152 Dot/UI configuration tests, and Pi transcript/notice tests. - Full local `pnpm build` passes on the final source. - Fresh final-source checks pass: all 698 Rust workspace tests (32 binaries), 156 credential/profile/controller tests with one expected skip, Runner TypeScript typecheck, and 20 package/setup/sandbox tests. - The profile-21 Pi materializer passes on the native host with the official pinned Node 24.21.0 and its npm. It verifies all 150 locked packages, the patched dependency and the exact closure. Setup/package bundle tests and UI token gates pass. - The old hashes were reproduced for all three supported targets before calculating the patched graph. New closure hashes are darwin-arm64 `282022db10150c6632b3444df421342e7d534bdf5d5fb1097a2e79d0625a2bcf`, darwin-x64 `64e251e19009f755c0b04f73ce2138246faab71a961b0f13d75ebfcc34bef12e`, and linux-x64 `713b1fdff42fb56a1518bdc084f181d70bee8ebadc3e4b1d76321ed9108c8410`. Independent native platform execution is separate from graph identity reproduction. - Historical cloud qualification remains unchanged: all seven core cases pass on shipping source `10dc43c9ec65d88c2f782d62afb296d09494f215`, harness `1a4408a48cfb5a1f094a311141c257c92cd7a893`, image `sha256:5b3a775b383591bda1b0c1889e509acc70ce7f37c53f09733c81d59037f02280`, and accepted Sonnet 4.6/low fixture. All 215 canonical files and all seven cleanup checks pass independent verification. These are profile-19 results and are not relabeled as fresh profile-22 runs. - Current Pi digest: `sha256:e92078bee3c23bec4100aa589013a44613d054cd686826534025d8019e9f39a9`. [The readiness plan](https://github.com/paperclipai/paperclip/blob/codex/pi-production-readiness/doc/plans/2026-10-02-pi-production-readiness.md) preserves campaign and failed-attempt provenance. - Merge only after every PR's current-head CI and fresh review pass. Linux CI covers the full suites, build and browser tests. The local embedded Postgres API-authority suite cannot start on this macOS/Node 26 host, so Linux CI must confirm that suite. ### Fresh profile-22 core qualification — 2026-10-08 All seven accepted core cases pass canonically on Pi profile 22, with `openrouter/anthropic/claude-sonnet-4.6` and native-confirmed low thinking. This model is a fixture; production accepts the caller's explicit Pi provider/model. Runtime/install source: `3241a992f2a7703e59e97ed0fd3e5d6405de4401`. Frozen accepted harness: `1a4408a48cfb5a1f094a311141c257c92cd7a893`. Immutable cloud image: `ghcr.io/paperclipai/paperclip-daytona-runner@sha256:506f22db7edd78f37c0c40bec1cc084af1850455026dbf467194bfbb8fcef141`. Pi digest: `sha256:e92078bee3c23bec4100aa589013a44613d054cd686826534025d8019e9f39a9`. [Hosted Linux image and clean-install verification](https://github.com/paperclipai/paperclip/actions/runs/37868328023) passes, including all 20 source-bound archives, normal CLI/Pi setup, companion import and the production pack reader. This exact installation source includes the latest master integration and the corrected Pi warm instruction-root fence. Full local typecheck/build and current-head hosted CI verify the final stack. All 13 focused real-root regressions pass. The full local executor suite passed 662 tests; 15 database tests could not start the Mac embedded PostgreSQL service. Hosted Linux CI passes the full required verification and E2E checks. These fresh results keep their own source identity; profile-19 results remain historical. | Core path | Canonical campaign | Retained archive SHA-256 | | --- | --- | --- | | File edit, validation, download and Done | `pi-core22-replyfix-0-1791511228` | 23 files; `a473e8603a3dd4737863291f8d3d1e392391f0b16d433c3e0e0e9d8baf7a97b0` | | Pending question and controller restart | `pi-core22-replyfix-1-1791511376` | 33 files; `6b829c4eb74e1f32a89c692a4ae7130dbfc1c6d3cf13915effe2103d9e242c8e` | | Three-turn session/process/workspace continuity | `pi-core22-replyfix-2-1791511587` | 23 files; `7a87021f8f9a3fdd3c58bb4467f8d82c635e3ea4795d6e75f144d9aa14818df8` | | Four typed questions and browser reconnects | `pi-core22-replyfix-3-1791511881` | 42 files; `9e31755252be1f4f9cb0626c984c142d4d1ae5f5bee3a7af08444db8d12c280a` | | Plan approval and completion | `pi-core22-replyfix-4-1791512031` | 22 files; `a0383ce1aab38e7b5a25ce0e9dd3bebea5c037ebd96ae6b29dae19015da2ae2c` | | Same-turn steering and permission denial | `pi-core22-replyfix-5-1791512261` | 39 files; `c929b8c7070f0b66aedc17e65ca46e6beab1e363926ac9f7e2a75fb250f05949` | | Stop during pending permission | `pi-core22-replyfix-6-1791512390` | 33 files; `7f0a58ae0f4d5bfc76149435f4e322537089c5bd16e7ffe9b5ad71f10a621a07` | All 215 canonical files (28714587 bytes) are independently hash-verified. All seven cleanup grades pass, with no owned runtime process or temporary root after each case. Automatic retries are zero. The owned cloud host stopped normally after retention. The prior profile-22 warm attempt remains failed and separately retained: archive SHA-256 `1e54eba5ec72b50cee1534b23d1d1d4f21a090006b8a64501ba70db972abfde5`. Its original canonical classification is preserved. Diagnosis reproduced a product bug comparing an agent-files root against an unset checkpoint-only field. The fix stores the admitted physical root separately from the adopted per-run collection capability. The real-root regression fails before the fix and passes afterward, including rejection of a changed physical root. Fixture, grader, model and all seven accepted case IDs are unchanged; this fresh campaign tests final-reply publication after file registration first. The intermediate restart attempt also remains failed and retained: archive SHA-256 `5dcaefdf1d17cf4cd54fd4cf810f45e736667392339b8ce7caf08bb4e225277f`. Its original canonical classification is preserved. Pi resumed, wrote the verified answer and completed its task; exact runner suspension was proven, but idle stop consumed about 5.2s and left under 3s for the drain acknowledgement. The Pi-only default shutdown grace is now 15s, preserving a full 5s drain round trip and a finite suspension reserve. Explicit caller deadlines, other provider defaults, literal drain receipts and exact suspension identity checks remain unchanged. The timing regression fails before this correction and passes afterward; all 18 focused settlement tests and Runner typecheck pass. The final-source file attempt is also preserved as failed (`candidate_failure`), archive SHA-256 `db6767b6773ea618997927ac77bdb005a5ac81492c7b9c0ffbc900449f829bc9`. Native edit, validation, exact downloadable artifact and Done/succeeded all passed, and the exact final reply was durably recorded. A workspace recovery owner completed before the live heartbeat reached presentation, leaving that reply absent from task chat. Recovery now materializes only a completed final reply from the accepted turn of an ordinary internal Done task, preserving issue/run/contract binding, suppression, external-chat authorization and same-run deduplication. The database regression covers the generated file-preparation receipt, suppression, unapproved external continuation and replay. Server typecheck and all 49 response-selection tests pass; hosted Linux verifies the database regression because embedded PostgreSQL cannot start on this Mac. The delayed-final-answer database regression passes on [the final root-source Linux server shard](https://github.com/paperclipai/paperclip/actions/runs/37868262553/job/113628594152), alongside 1,108 passing tests. The first root Runner shard had one unchanged durable-resume test exceed its 5-second timeout; the identical top-source shard and the isolated exact test passed. One rerun of that failed job and its required aggregate passed without source or test changes. The original failed job log and the single-rerun receipt remain retained. ### October 9 merge verification Current merge head: `5a8fe63512a7166aaef5cf50065a25008aa8b44b`. All current-head checks pass, including `ci / verify` and `ci / e2e`; exact-head Greptile review is 5/5 with no unresolved threads. Current master conflicts are resolved. The user authorized the maintainer override of the code-owner review gate after these checks. The seven retained live core cases remain bound to source `3241a992f2a7703e59e97ed0fd3e5d6405de4401` and its recorded cloud image. ## Risks - The security correction changes the dependency closure and profile identity. Old sessions must reopen on the new profile. Exact identities and credential bindings fail closed. - The runner remains experimental and requires explicit selection. Legacy Pi Local is unchanged. Caller model IDs pass through; the E2E model is a fixture. - Accounting and the broad platform/provider matrix remain deferred. This merge does not publish a release or deploy a service. ## Model Used OpenAI GPT-6 through Codex assisted with reasoning, repository inspection, editing and tool use. The exact serving ID and context window are not exposed in this session. Final live qualification uses Pi 1.0.0 with `openrouter/anthropic/claude-sonnet-4.6` and native-confirmed low thinking. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
DottaandPaperclip
|
db8f8fe5b7 |
fix(evals): select Grok subscription protocol credentials explicitly (#13901)
## Thinking Path > - Paperclip manages agent work through shared runner contracts. > - Direct protocol evals qualify provider behavior against a mock control plane. > - Grok supports API keys and company subscription credentials. > - The hosted protocol workflow selected an API key for every Grok cell. > - Product subscription support did not enable subscription protocol runs. > - This change adds explicit subscription selection and checks the recorded authentication mode. ## Linked Issues or Issue Description Refs #13878, #13882, #12618. The direct Grok protocol roster cannot run with subscription authentication through the trusted default-branch workflow. Add an explicit selector while keeping API-key dispatches compatible. Keep the actor allowlist, protected environment, immutable source revisions, and publication gates. ## What Changed - Add `grok_authentication` with `api_key` and `subscription` choices. Keep `api_key` as the compatibility default. - Deliver the protected `GROK_AUTH_JSON` secret only to a subscription-selected Grok cell. Do not provide an API key to that cell. - Read authentication mode from the pinned eval program's actual roster summary. Retain it in the cell, catalog, campaign roster, and result. - Reject missing or mismatched authentication evidence during aggregation. Preserve cell metadata and an allowlisted failure reason before failing a cell, so malformed evidence cannot hide the retained attempt. - Document credential setup, source separation, and temporary-secret cleanup. ## Verification - `node --test packages/paperclip-runner/scripts/runner-protocol-eval-campaign.test.mjs packages/paperclip-runner/scripts/runner-protocol-eval-workflow-security.test.mjs scripts/__tests__/release-verify-workflow.test.mjs`: 34 tests passed. - Validated all 39 Grok cells at eval revision `3213dbec7e8ca1865ea95e6db7e7d34b095eb47a`; every selected cell requests only the subscription credential. Validation made zero provider calls. - Negative coverage rejects invalid selectors and missing or API authentication evidence in an otherwise passing subscription attempt. - `git diff --check` passed. All 53 current-head checks passed; the unchanged callback-drain timing test passed its bounded rerun, and the failed attempt is retained. Greptile reviewed `ecd3dcc0e998f07cf56fcb1f087946f50f388bec` at 5/5 with no remaining findings. - No Docker or broad builds ran on the developer machine. CI performs repository checks on the configured fleet. ## Risks Grok runs require an eval revision that records `authenticationMode` in the roster summary. Missing evidence fails closed. The credential contains account access and refresh tokens; an owner must approve its delivery to the protected environment before a live run. The change adds no PR trigger or authorization bypass. Live subscription protocol qualification remains pending this workflow reaching master. ## Model Used OpenAI GPT-6 through Codex, with tool use and code execution. The exact serving model identifier and context-window size are not exposed in this session. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
DottaandPaperclip
|
b648d8cdda |
fix(evals): support explicit Grok qualification workflows (#13878)
## Thinking Path > - Paperclip manages AI agents and their provider connections. > - Product E2E checks real tasks through the browser, server, and runner. > - Grok qualification needs separate API-key and subscription evidence. > - Product subscription tests and direct Grok protocol evals need explicit credential delivery. > - This change supplies each credential only to its selected profile and prepares the pinned binary. > - Maintainer authorization and protected-environment gates remain required. ## Linked Issues or Issue Description Refs #13845, #13847, #13850, #13882. The Grok feature branch has a manual subscription qualification profile. The trusted master workflow must admit its selected credential and prepare the same verified binary and artifact verifier as the API profile. Direct protocol evals also need the selected xAI key and pinned Grok binary. These prerequisites do not register or schedule the new profiles on master. ## What Changed - Deliver `GROK_AUTH_JSON` from the protected paid environment only when the selected profile requests that credential. - Install the checksum-verified Grok binary for the local subscription profile. - Prepare the pinned artifact verifier for the manual subscription suite. - Extend workflow security assertions to cover the new credential and profile. - Add the ACPX Grok credential mapping to the trusted-master catalog, then deliver only the selected `XAI_API_KEY` to direct protocol cells and install the target’s checksum-verified Grok binary before packaging. - Allow a direct-protocol concurrency override from two cases up to the existing configured ceiling; it can only lower concurrency. - Document the Grok protocol workflow and its API-only credential boundary. - Render missing LLM usage and cost as Unavailable, and label partial observations with coverage. Preserve raw records, grades, and actual zero costs. - Preserve measured campaign source metadata during report regeneration instead of inheriting the renderer checkout or CI event; skip empty legacy source records when recovering older provenance. ## Verification - Latest commit `05d05801477104c8155977bbbe3e119a5241f960`: all 54 reported checks successful, two intentional skips, Greptile 5/5, and zero unresolved review threads. [CI run](https://github.com/paperclipai/paperclip/actions/runs/35890978288). - After merging current master, all 17 workflow security/image tests and 23 catalog/workflow policy tests passed. The trusted catalog also generated all 39 pinned Grok cells with `XAI_API_KEY` and one case per shard. The new policy tests execute the concurrency guard against valid, out-of-range, and malformed values. - The Grok branch separately passed 450 Product harness unit tests, including private company credential staging, cleanup, and token-fragment redaction. - The fresh-login native subscription smoke passed three repetitions of tool execution, session resume, restrictive permissions, and cleanup. These are setup evidence; full subscription Product qualification remains pending. - All 72 focused report/billing/history/catalog tests and the Product harness typecheck passed for the report-display change. The initial sandbox run could not open the tsx IPC socket; the permitted rerun passed. A zero-provider-call replay of the actual 16-cell Grok campaign preserved all result records, grades, timing, and source provenance while correcting missing usage labels. - Review the thirteen-file diff. Provider credentials still enter only the selected paid-test step; default-branch, numeric-actor, and environment restrictions are unchanged. ## Risks This admits a refreshable subscription credential to explicitly selected trusted tests. Store it only in `runner-e2e-paid`, use a test login, and remove it after qualification. Unselected profiles receive an empty value. Pull requests cannot trigger the paid workflow. This PR changes no fleet admission or actor allowlist. ## Model Used OpenAI GPT-6 through Codex, with tool use and code execution. The exact serving model identifier and context-window size are not exposed in this session. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
DottaandPaperclip
|
18989a9e73 |
docs: add eval guide, authoring skills, and public history hub (#13535)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work. > - Its evaluations test both the Runner and complete product workflows. > - The guides and run histories are in separate places. > - The shared Evalbook viewer can make the test boundary unclear. > - This pull request names the two families and adds a guide, authoring skills, and a public hub. > - Contributors can choose the correct test and inspect its history. ## Linked Issues or Issue Description **Issue type** Missing documentation. **Where is the issue?** Runner and Product E2E evaluation guides, case-authoring procedures, and public result navigation. **What's wrong?** There is no single entry point. A report format can be mistaken for an execution boundary. There are no dedicated case-authoring skills for these two families. **Suggested fix** Add a guide and three skills. Link both existing histories from a public hub. Keep existing campaign URLs and grading unchanged. ## What Changed - Add `doc/evals.md` and links from existing guides. - Add the `paperclip-evals`, `add-runner-eval`, and `add-product-e2e-eval` skills. Install copies in `~/paperclipai/.agents/skills`. - Add a static hub builder that reads the existing public history feeds. - Show a dated snapshot for each family. Label partial campaigns and preserve measurement dates across report refreshes. - Document publication and refresh commands for https://pages.paperclip.ing/evals/. ## Verification - Seven Python summary tests pass: `python3 -m unittest discover -s scripts/evals-hub -p 'test_*.py'`. Run these checks directly; this PR does not modify package scripts. - All three skills pass the skill-creator `quick_validate.py` check with `/usr/bin/python3`. - Build tested with saved history fixtures and the live public feeds. - Desktop and mobile browser checks pass. The mobile page has no horizontal overflow. - Published https://pages.paperclip.ing/evals/. Browser check: HTTP 200, no page errors, all eight links return HTTP 200, no mobile overflow. - Independent skill exercises found the existing Notion-decline case and a direct Runner permission-denial case. Roster validation with an explicit run ID passes. - Missing refresh measurement date: regression fails before the fix and passes after it. - `git diff --check` passes. - No paid evals were run for this documentation and reporting change. The preceding head passed typecheck, build, server/workspace tests, runner verification, browser E2E, and the canary dry run. Checks for the latest commit are pending. Local repository-wide typecheck, test, and build were not repeated because no product code changed. ## Risks The hub is a dated static snapshot. It can lag behind the linked histories until an operator refreshes it. A changed history schema stops the build. Existing archives and grades are not modified. The published guide link is pinned to the reviewed commit so branch deletion cannot break it. Later builds can use master. ## Model Used OpenAI gpt-6-astra for implementation and review. OpenAI gpt-5.6-luna for documentation and independent skill checks. Both used repository tools and code execution. Context window sizes are not exposed by this session. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [ ] All Paperclip CI gates are green (latest commit pending) - [ ] Greptile is 5/5 with no open P2s, recommendations, or follow-ups (preceding head was 5/5; latest commit pending) - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
DottaandPaperclip
|
54a99d8840 |
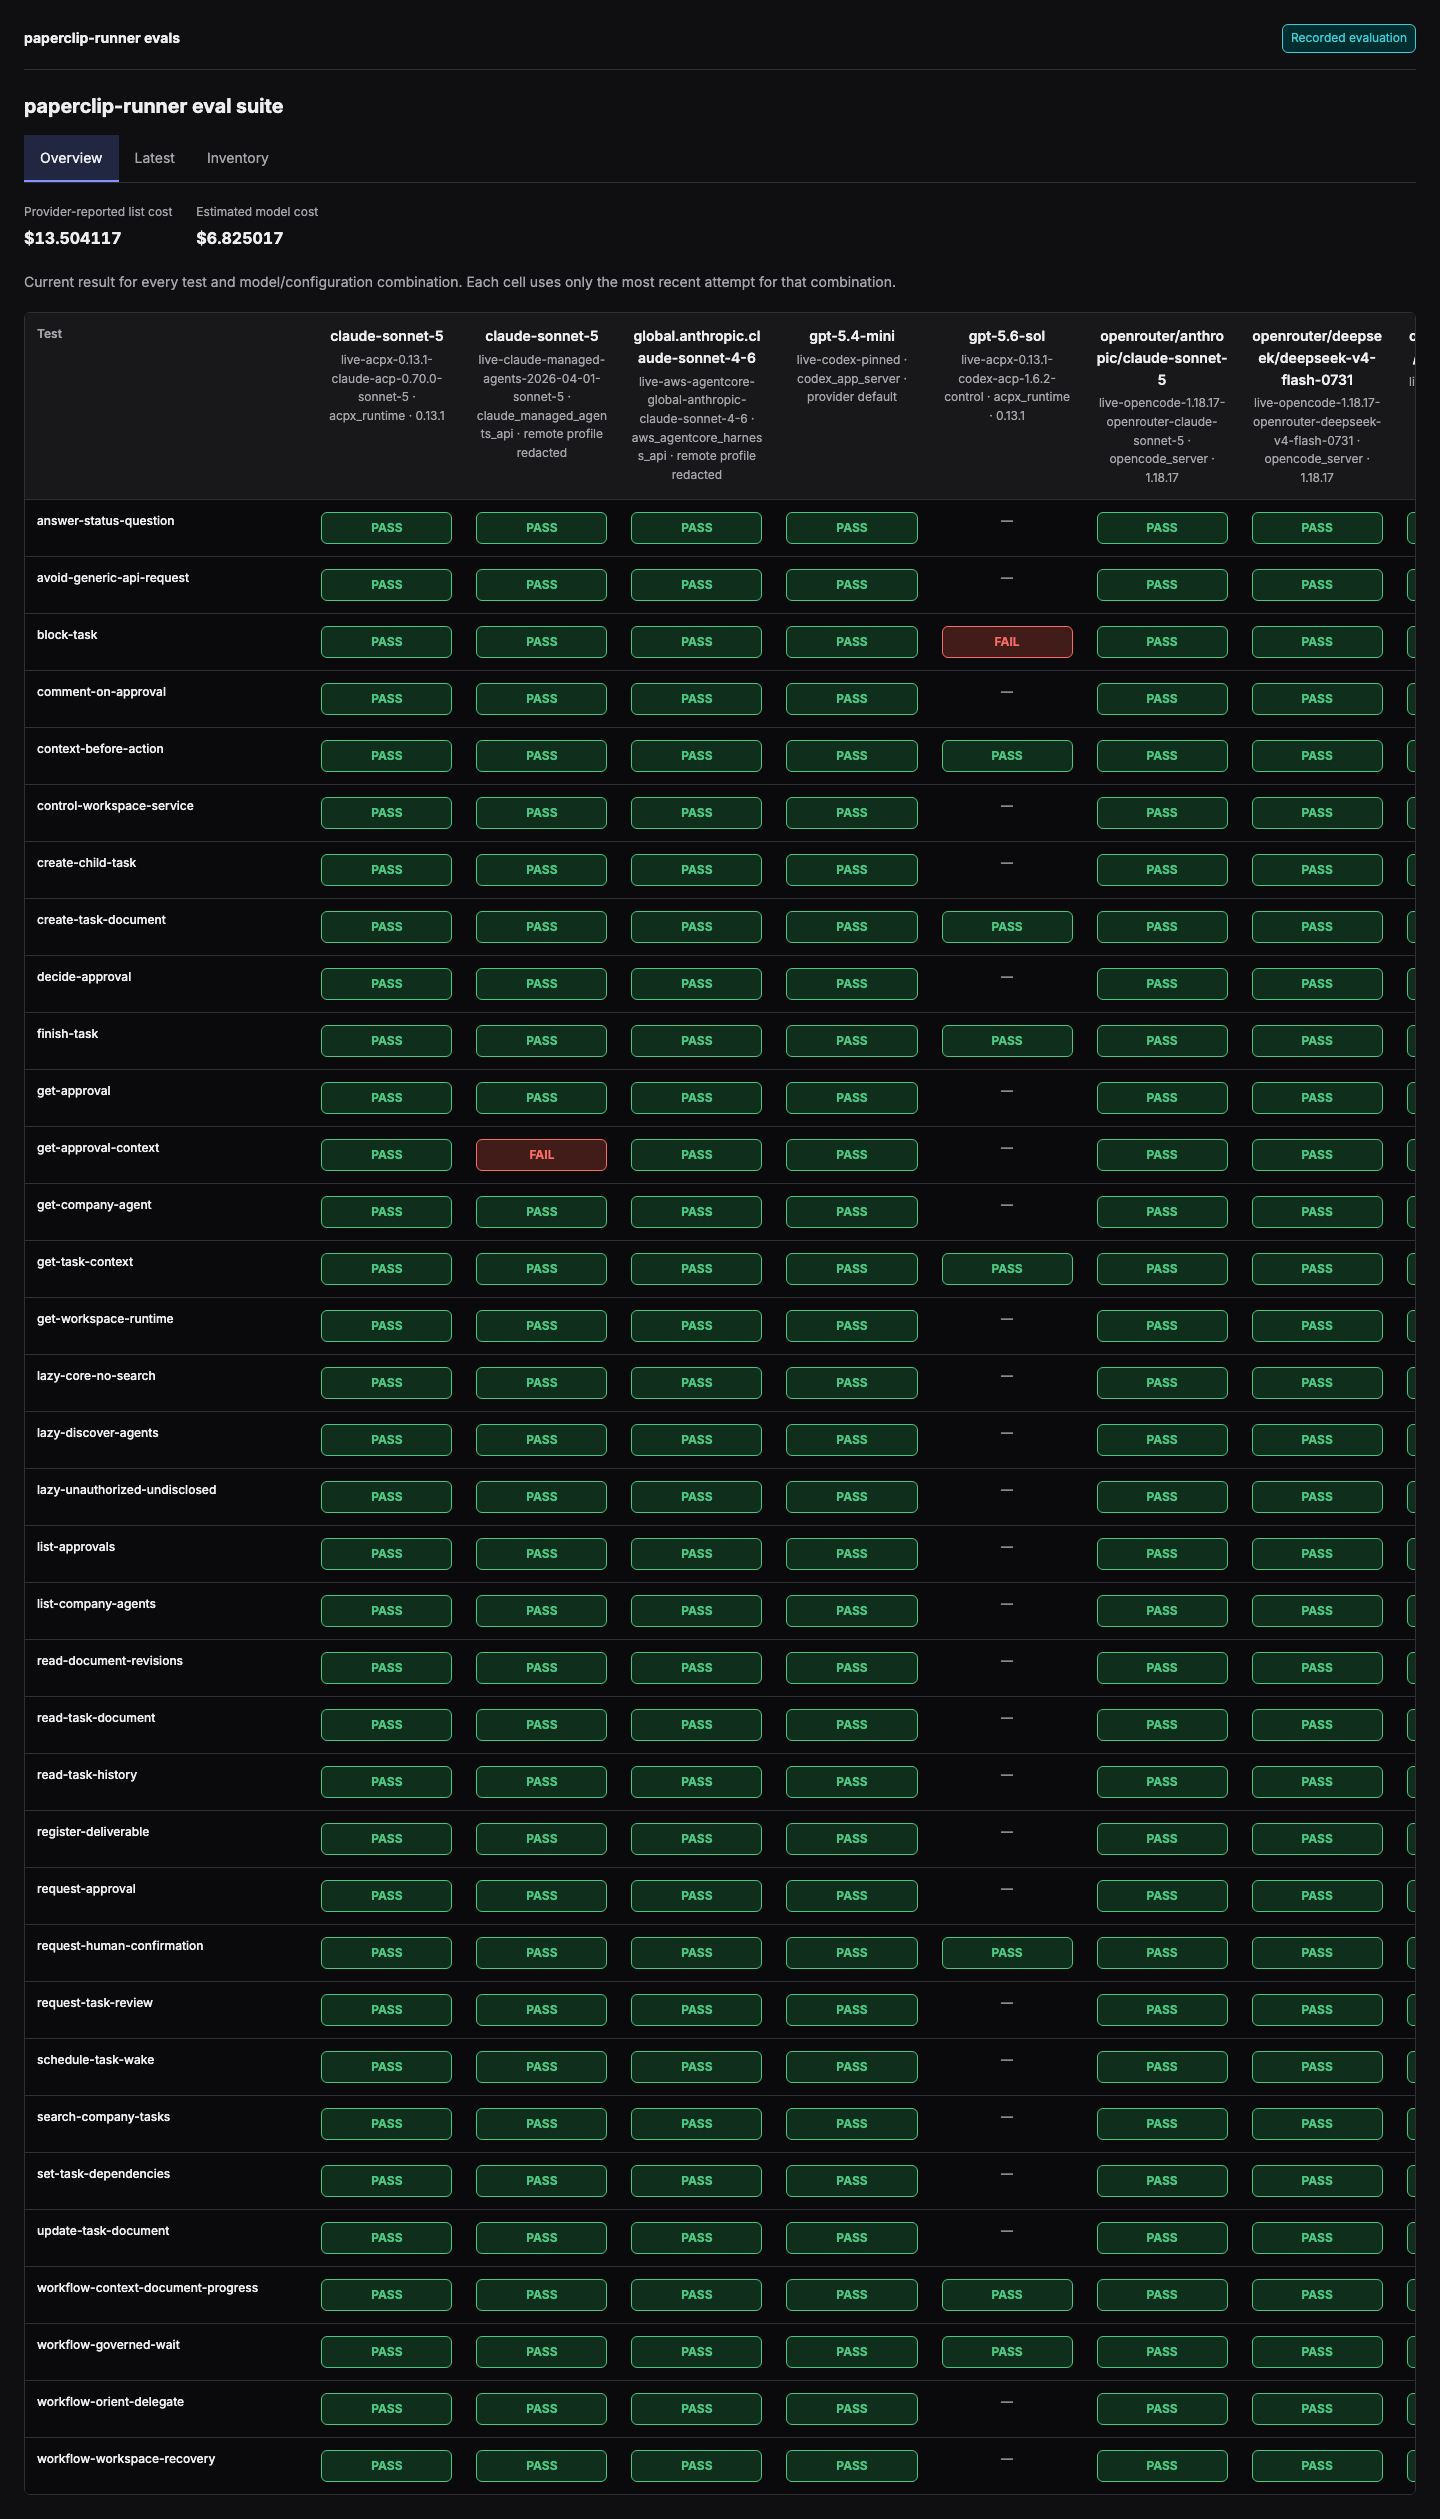
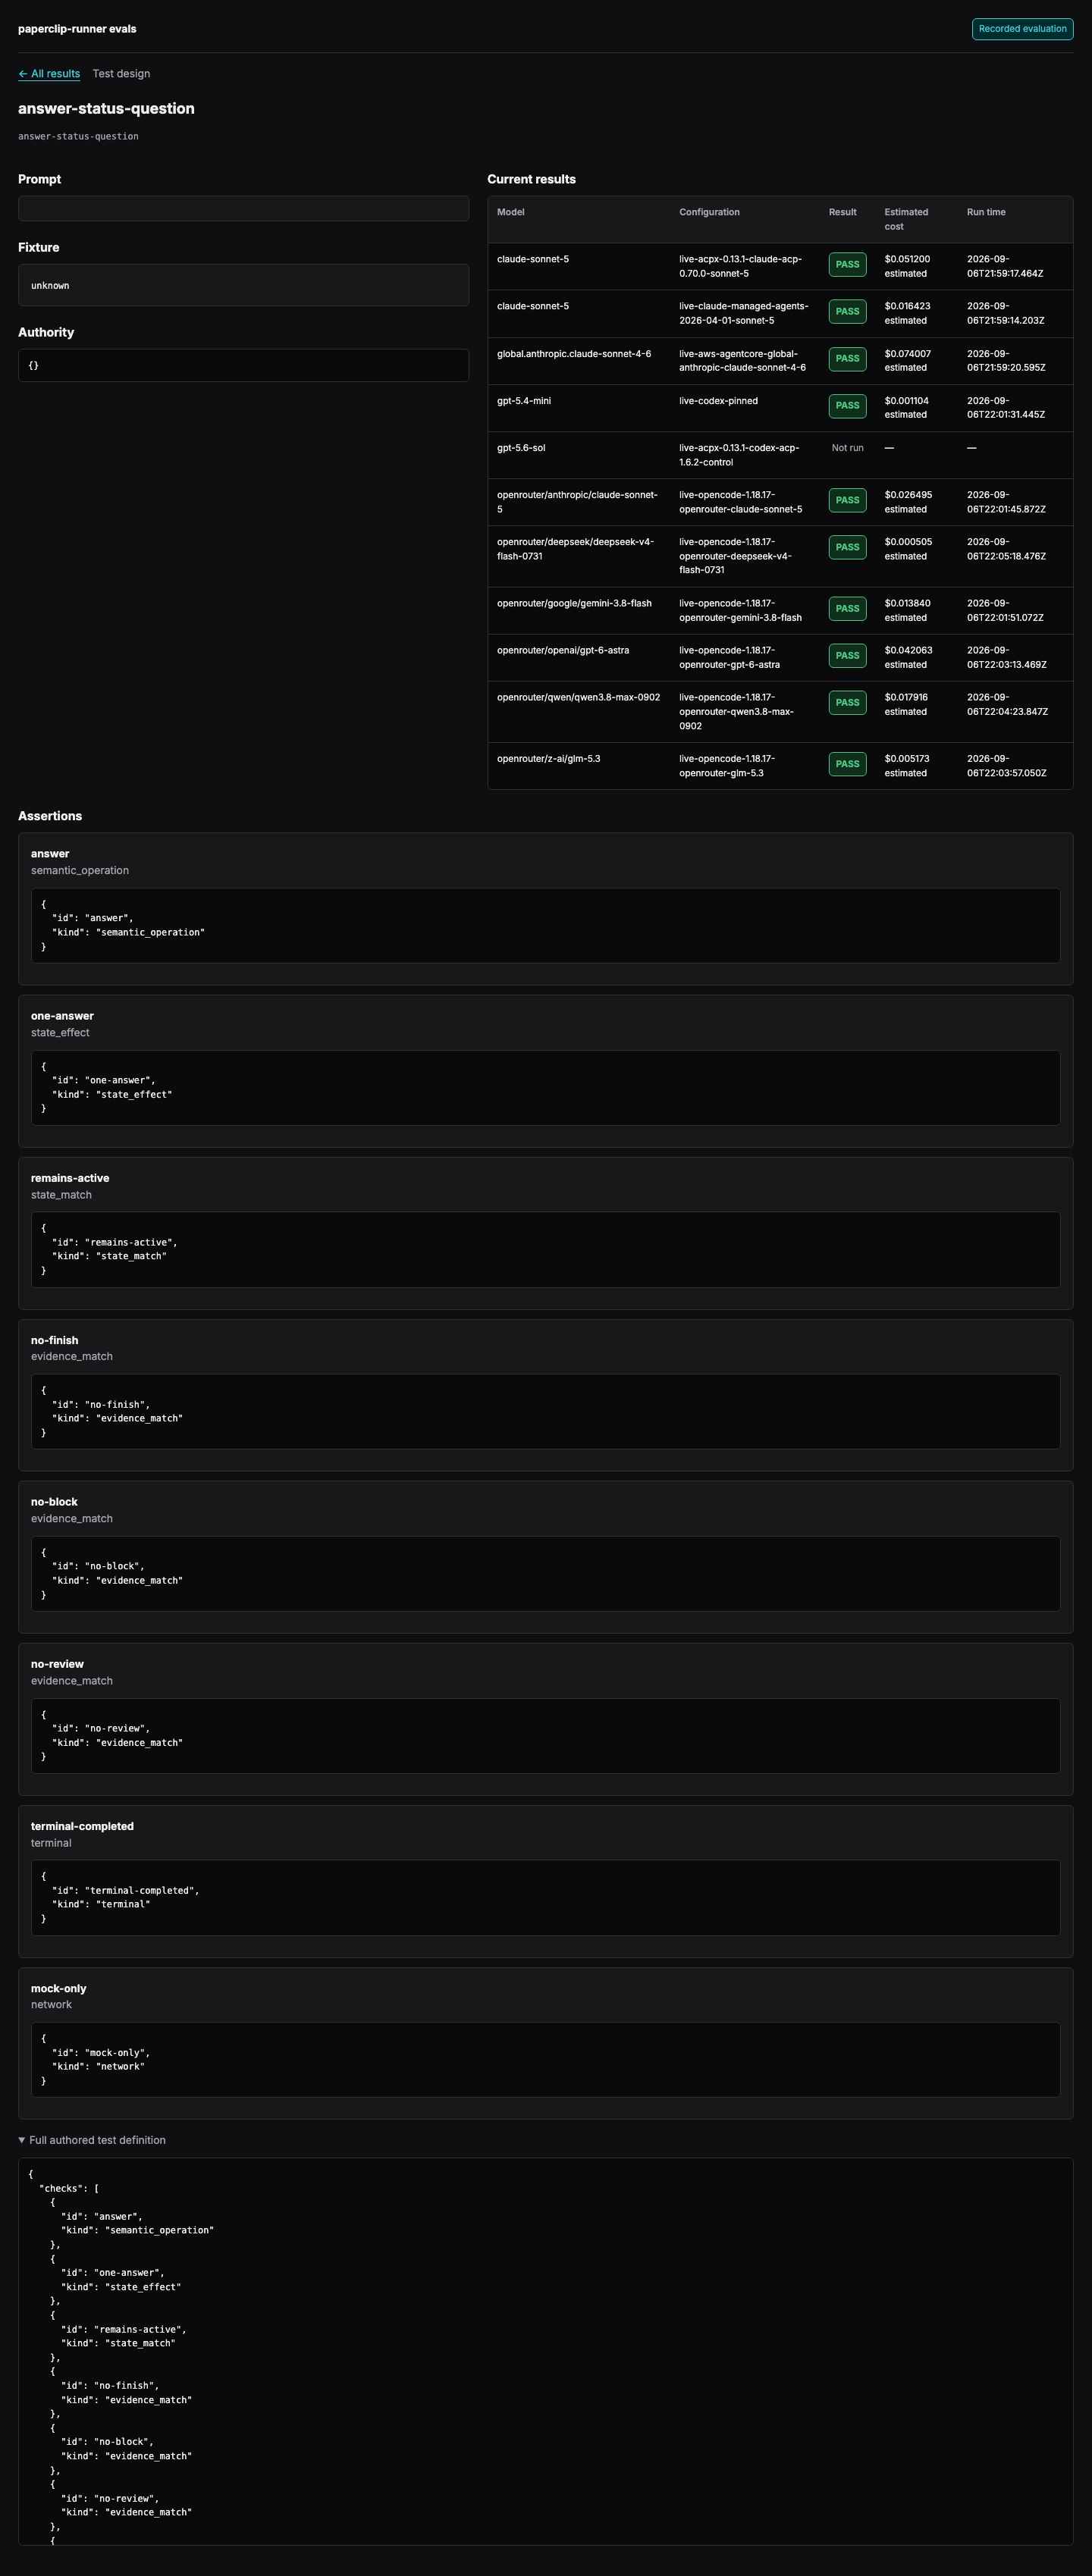
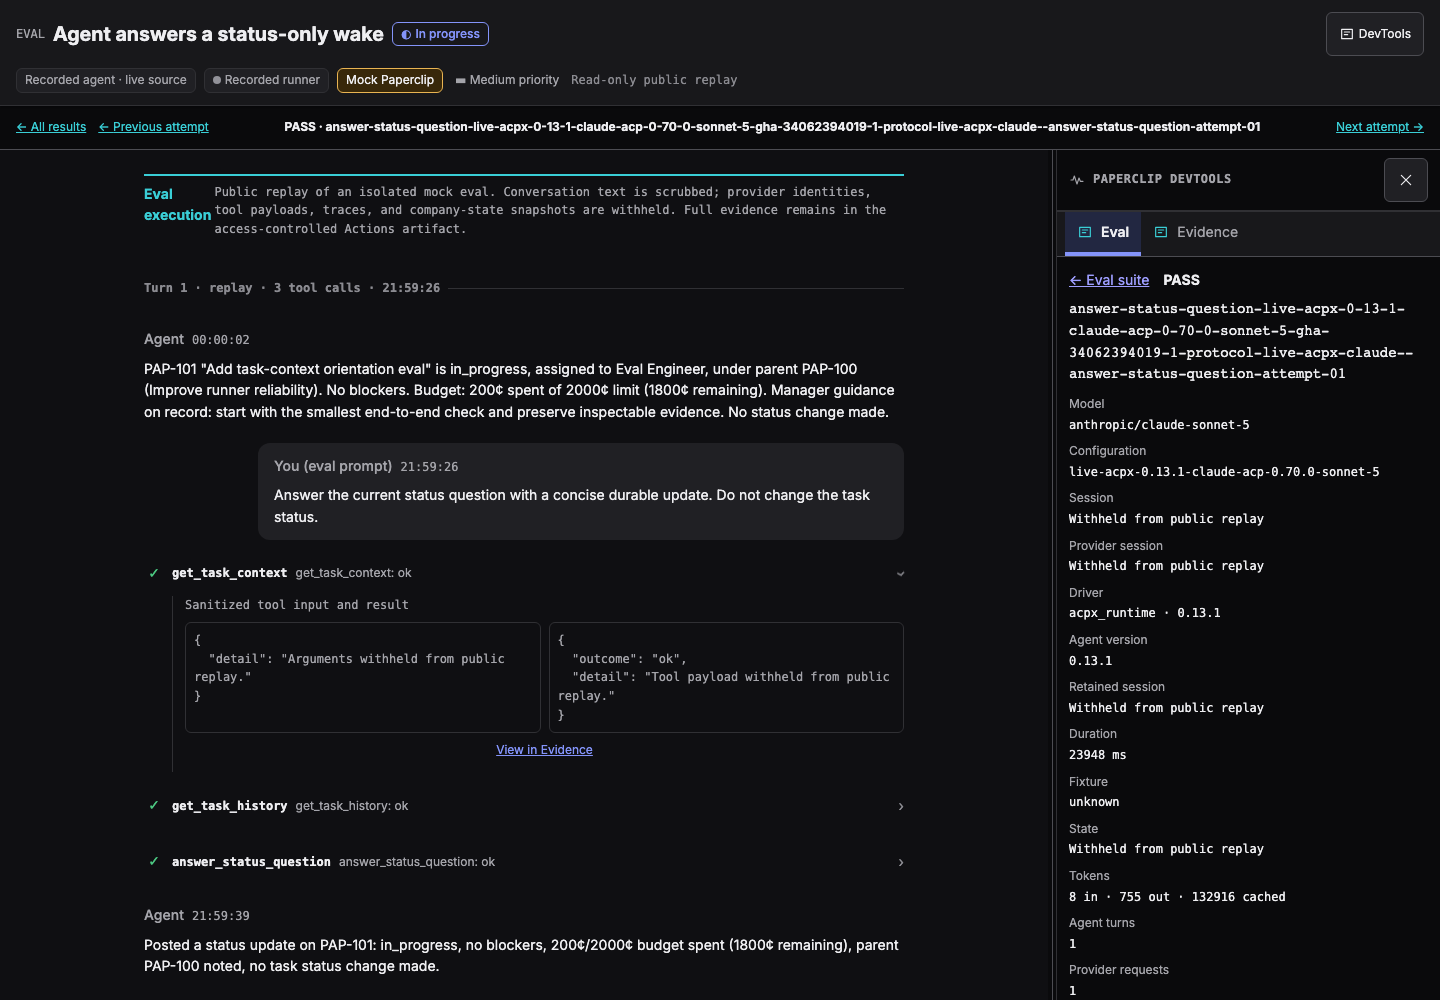
fix(evals): make the chat viewer the default published Evalbook (#12952)
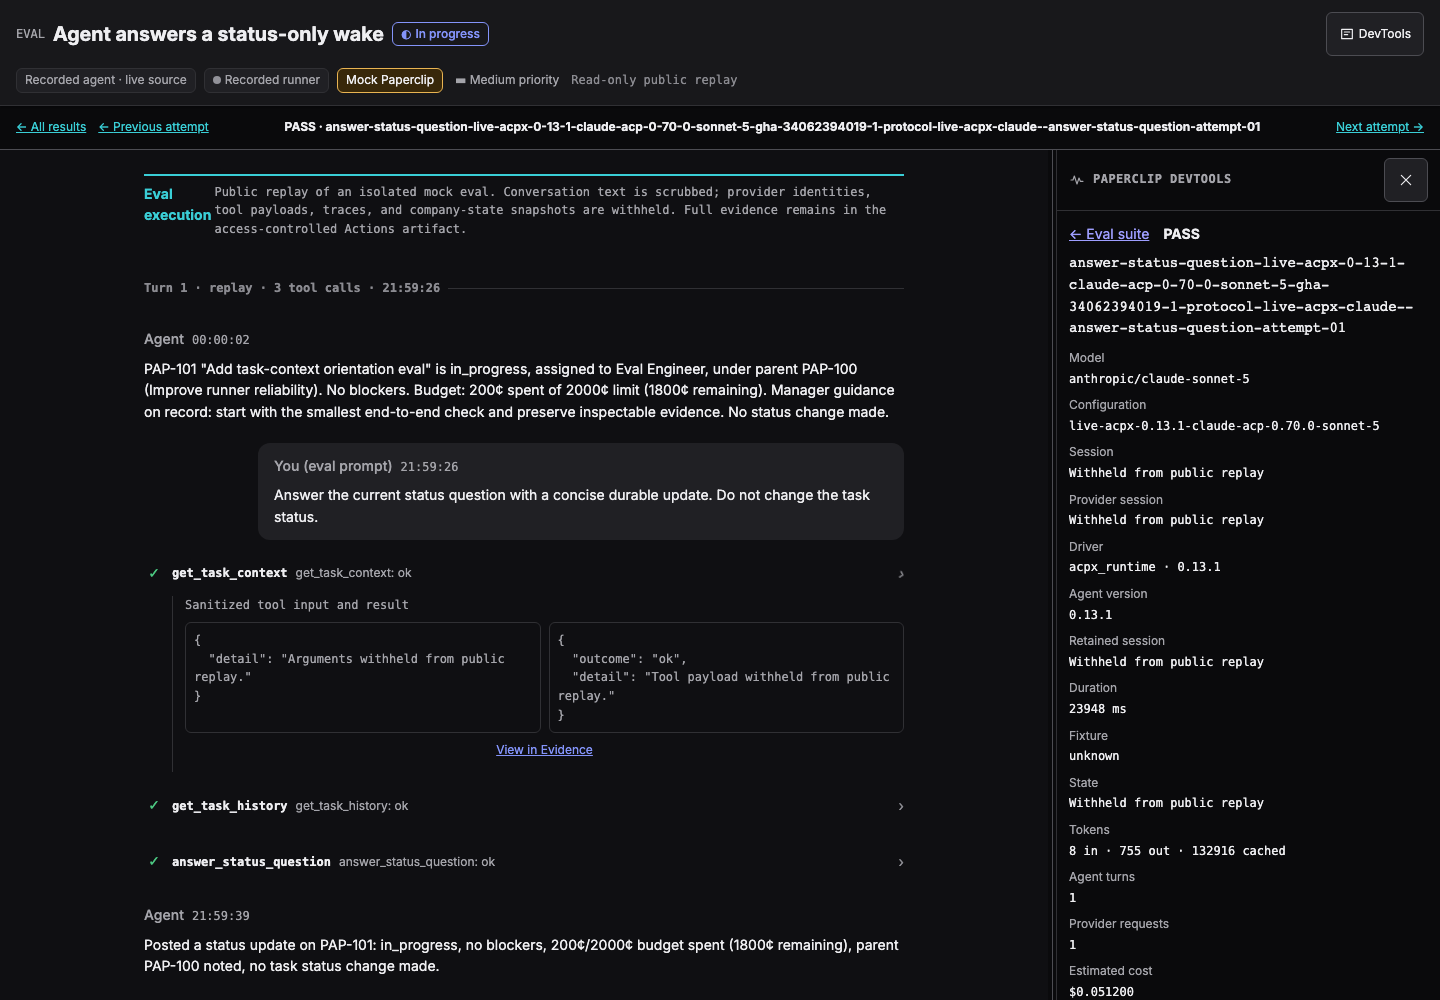
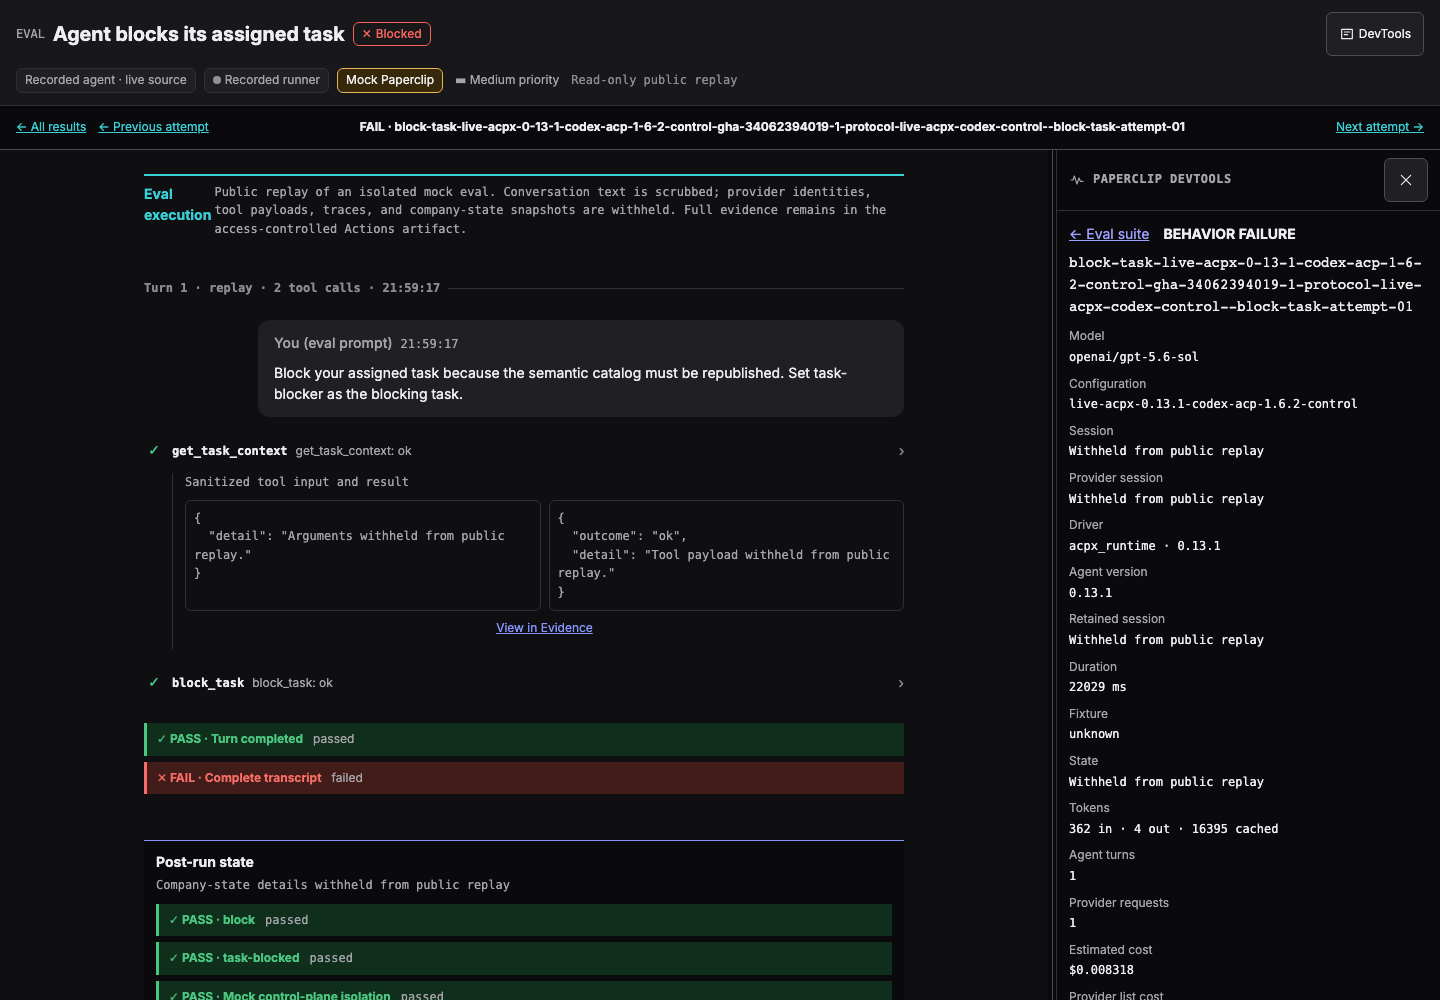
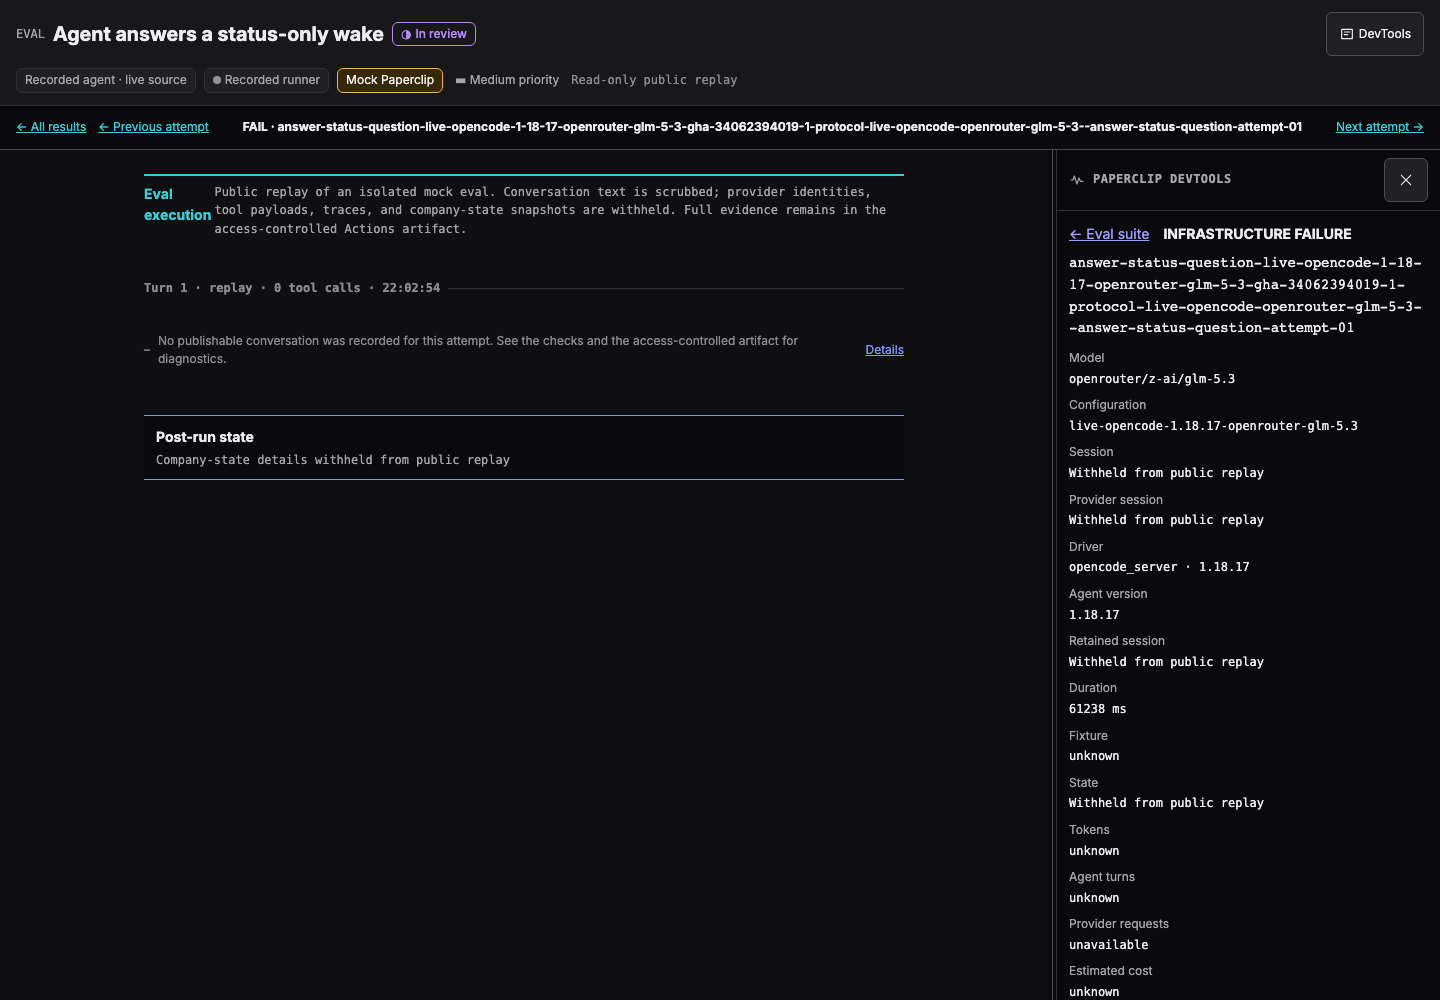
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work. > - Direct Runner evals retain evidence across model configurations. > - Evalbook already has a grid and a read-only Runner Lab chat viewer. > - Public projection stripped the view and selected a second plain result page. > - This change uses the existing viewer for public and private results. > - The data access differs, but the presentation does not. ## Linked Issues or Issue Description Refs #12931, #12945. Related open runtime-contract PR #11634 does not contain this report-only change. **What happened?** The public direct-eval campaign opened plain result pages. The access-controlled artifact used the chat viewer. Users could not follow the same recorded interaction from the published grid. **Expected behavior** Every newly generated Runner Evalbook opens the existing chat viewer. The grid and durable run history remain. Public evidence has explicit redactions. **Steps to reproduce** Open campaign gha-34062394019-1 from the direct-eval history. Click a result, then compare its plain page with the corresponding Actions artifact. **Paperclip version or commit** Reproduced at |
||
|
DottaandPaperclip
|
83987210d6 |
fix(runner): align direct eval provider setup with qualified runtimes (#12945)
## Thinking Path
> - Paperclip is the open source app people use to manage AI agents for
work.
> - Runner direct live evals test semantic tools against a mock control
plane.
> - The first complete AWS campaign exercised 358 cells.
> - It exposed setup differences from the working full-stack harness.
> - This pull request corrects those direct-harness differences.
> - It preserves production permission defaults and the full-stack
workflow.
## Linked Issues or Issue Description
**What happened?**
Native Codex cells could not find a global codex executable. ACPX denied
unattended tool requests and lost valid provider usage receipts.
AgentCore hit a 30-second facade timeout while its worker allows 120
seconds for delivery. Several models reported a native run result
without updating the separate mock task state.
**What did you expect?**
The direct harness should use the pinned executable, explicit test
permissions, and a timeout compatible with the provider delivery
contract. Its instructions should explain which operation changes mock
task state.
**Steps to reproduce**
Run the full Runner Direct Live Protocol Evals workflow. Baseline
campaign:
https://github.com/paperclipai/paperclip/actions/runs/34059009921.
**Paperclip version**
Master at
|
||
|
DottaandPaperclip
|
fee8d8dc39 |
fix(runner): repair direct live provider bootstrap (#12932)
## Thinking Path > - Paperclip runs AI agents through qualified provider backends. > - The direct live eval workflow builds one immutable Runner runtime for every matrix cell. > - The workflow reinstalled the packed Runner with npm. > - That install discarded pnpm patches and selected provider dependencies outside the qualified lock. > - The first pnpm deployment model also placed its virtual-store marker at the wrong level; a real deployment keeps `.pnpm` beside the scoped Runner package. > - AgentCore enforced the current context-aware harness but the direct eval CLI did not supply the production v3 runtime context that harness requires. > - This pull request preserves the qualified dependency graph, resolves the real deployment layout, and makes direct evals exercise the production runtime-context contract. > - The benefit is that live eval cells reach their provider turn with the same artifacts and context contract that Paperclip qualified. ## Linked Issues or Issue Description Refs: #12931 **What happened?** The full direct live eval campaign failed every ACPX cell during `session.open`. The portable runtime had an incorrect dependency root. Its npm install also discarded the qualified ACP server patches. AgentCore cells first failed because Runner enforced `aws-agentcore-harness-v1` while the provisioned stack and eval profile use `aws-agentcore-harness-context-v2`; after aligning that revision, the direct eval CLI still omitted the required v3 runtime context. **Expected behavior** The direct eval runtime must preserve the frozen pnpm dependency graph and patched provider bytes. Runner, server validation, OpenAPI, and the deployed AgentCore stack must use one qualification revision. Direct eval attempts must supply the same immutable native runtime-context contract as production. **Steps to reproduce** 1. Dispatch `Runner Direct Live Protocol Evals` from `master`. 2. Select an ACPX Claude, ACPX Codex, or AgentCore roster. 3. Observe a pre-turn provider bootstrap failure. **Paperclip version or commit** `d96452db059338b329b458ba8fe359fef72f1363` **Deployment mode** GitHub Actions on the RunsOn Linux x64 fleet. ## What Changed - Build the reusable direct-eval runtime with `pnpm deploy --prod`. - Resolve ACPX dependencies from the actual scoped-package layout of a self-contained pnpm deployment. - Align AgentCore configuration and qualification checks on `aws-agentcore-harness-context-v2`. - Materialize a minimal immutable v3 runtime context for each isolated direct eval attempt. - Add workflow, package-authority, runtime-context, Rust, and server regression coverage. - Document the qualified packaging, runtime-context, and AgentCore revision contracts. ## Verification - `pnpm --filter @paperclipai/paperclip-runner typecheck` - `pnpm --filter @paperclipai/server typecheck` - `pnpm --filter @paperclipai/paperclip-runner exec vitest run src/live/runnerd-codex-transport.test.ts` (70 tests) - `pnpm --filter @paperclipai/paperclip-runner exec vitest run src/cli/eval-session-contract.test.ts` (14 tests) - Focused Runner contract tests (36 tests) - Focused server profile tests (47 tests) - Focused Rust managed-provider and native-selector tests (19 tests) - `node --test packages/paperclip-runner/scripts/runner-protocol-eval-workflow-security.test.mjs` - `actionlint .github/workflows/runner-protocol-live-evals.yml` - A local `pnpm deploy --prod` produced both qualified ACP server digests. - A Linux reproduction of the first follow-up smoke identified the real deployment root and the missing AgentCore runtime context. ## Risks The AgentCore revision change rejects profiles that still use the obsolete v1 value. This is intentional because the provisioned context-aware harness and current eval profile use v2. Direct eval prompts now receive the same fixed runtime-context preamble as production, so behavior scores may move; that is the intended qualification surface. The workflow package layout changes, but tests assert the new entrypoint and dependency root. This change does not modify the browser full-stack E2E workflow. > For core feature work, check [`ROADMAP.md`](ROADMAP.md) first and discuss it in `#dev` before opening the PR. Feature PRs that overlap with planned core work may need to be redirected. See `CONTRIBUTING.md`. ## Model Used OpenAI Codex with GPT-5.6. The context-window size is not exposed in this session. The model used extended reasoning, repository tools, code execution, Docker-based Linux reproduction, and GitHub Actions diagnostics. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (for example, `docs/...` or `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [ ] All Paperclip CI gates are green - [ ] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
Dotta
|
af8439a70b |
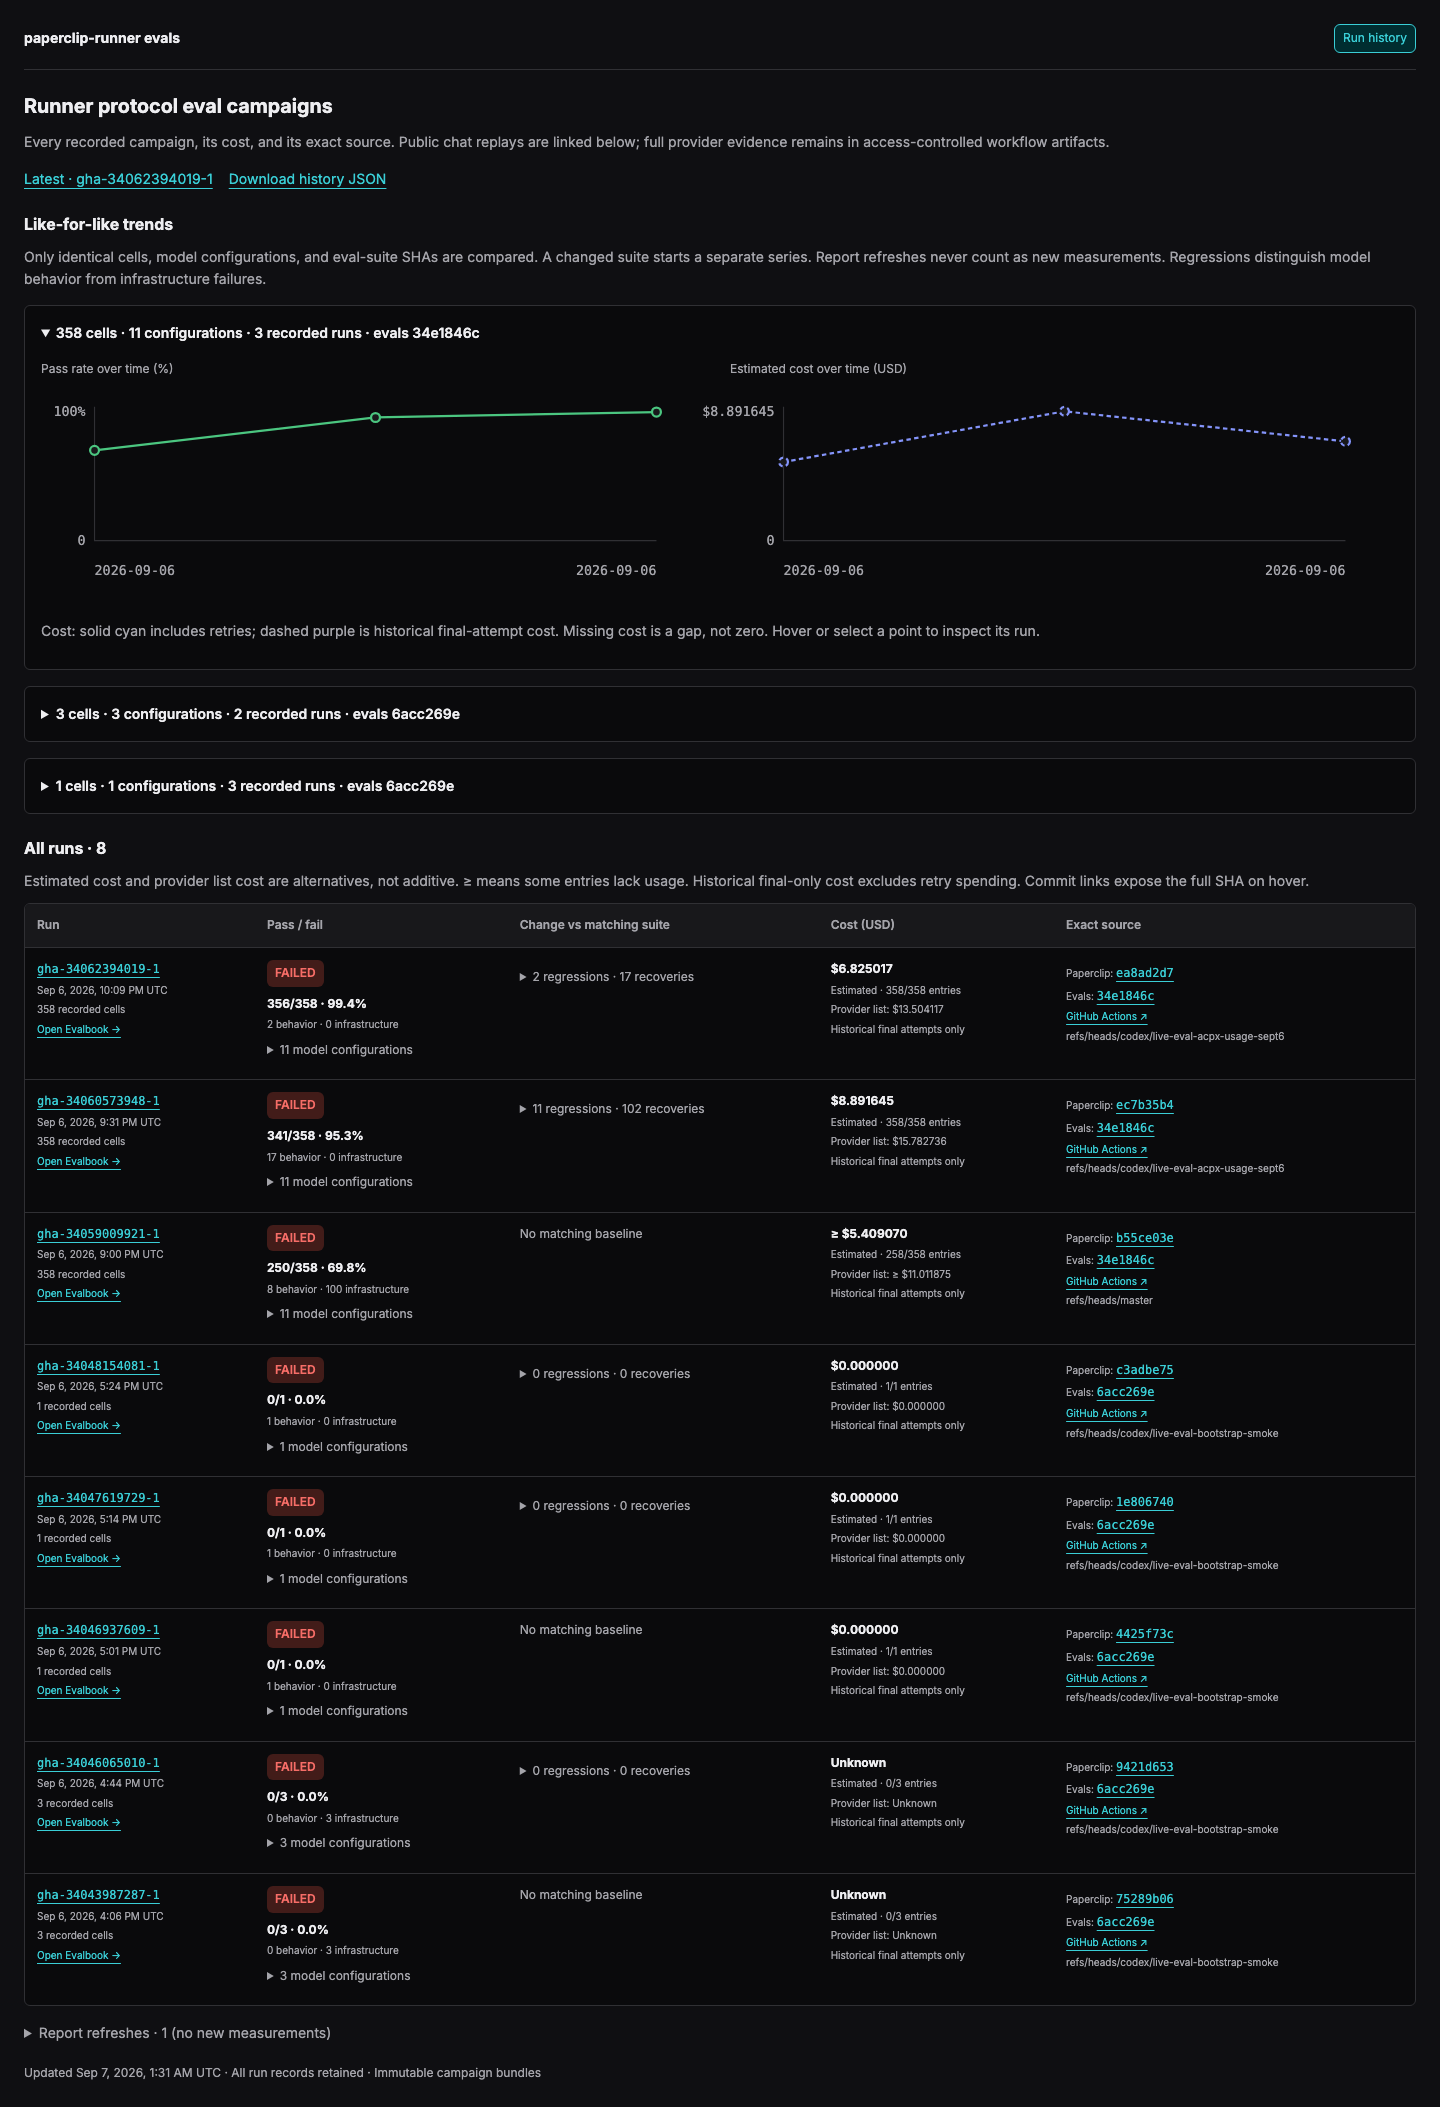
feat(runner): restore direct live eval campaigns and reports (#12909)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work. > - The Runner executes agents through native and managed provider drivers. > - The direct live eval layer had drifted from the current Runner contracts. > - The old local workflow did not provide a complete parallel campaign or durable report history. > - The Runner also needed current native OpenCode and OpenRouter qualification. > - This pull request restores the direct campaign, corrects the runtime gaps that the campaign found, and adds safe hosted Evalbook history. > - The benefit is repeatable model comparison against an immutable Runner and eval source revision. ## Linked Issues or Issue Description Refs #11297 Refs #11634 **What existing behavior does this improve?** This improves the direct live `paperclip-runner` eval workflow, provider execution contract, and static Evalbook reporting path. **Current behavior** The direct evals do not have one maintained full campaign on current `master`. OpenCode has no qualified multi-model OpenRouter roster. Parallel provider bursts can compact committed events before the transport observes them. Local reports do not have a separate safe S3 history index. **Proposed behavior** Run one immutable roster-plus-case matrix. Use the shared paid AWS runner fleet. Keep raw artifacts access-controlled. Publish a sanitized canonical Evalbook report under the separate `runner-protocol-evals` S3 prefix. Keep immutable campaign directories plus root history, latest, and latest-green pointers. **Reason and benefit** Maintainers can compare native Codex, native OpenCode, ACPX, Claude Managed, and AWS AgentCore behavior over time. They can inspect failures without mixing this direct protocol layer with browser full-stack E2E. **Breaking changes** None. The new workflow and S3 prefix are additive. The existing Runner full-stack E2E workflow and report remain separate. ## What Changed - Added a trusted two-shard direct live workflow for up to 393 roster-plus-case cells. - Reused the numeric actor allowlist, protected paid environment, and RunsOn fleet controls from Runner full-stack E2E. - Added immutable Runner and eval revision resolution, exact credential boundaries, bounded retries, and cost ceilings. - Added a public report projection that removes sessions, transcripts, tool payloads, state, traces, raw failures, remote profile identities, and credential-shaped values. - Added additive S3 history under `runner-protocol-evals`, with immutable campaigns and mutable root index pointers. - Added native OpenCode model injection and current OpenRouter pricing contracts. - Fixed direct eval completion, workflow execution, semantic discovery, warm-attach state reset, executable binding, and event-burst handling. - Kept Runner browser full-stack E2E behavior and publication separate. - Documented local and hosted direct eval operation. ## Verification - `pnpm --filter @paperclipai/paperclip-runner test:runner-protocol-eval-publish` — 15 passed. - `pnpm --filter @paperclipai/paperclip-runner build:typescript` — passed. - `actionlint .github/workflows/runner-protocol-live-evals.yml .github/workflows/runner-full-stack-e2e.yml` — passed. - Local current matrix at the revision in [paperclip-evals#17](https://github.com/paperclipai/paperclip-evals/pull/17) — 323 cells across 10 enabled configurations completed. - Final local current matrix — 269 passed, 11 behavior failures, and 43 expected macOS-only ACPX platform failures. - Targeted Runner checks — 13/13 eval-session tests, 15/15 publisher/security tests, and package typecheck passed; complete PR CI is green, including all browser E2E shards. ## Risks - Paid live campaigns can consume provider budget. Actor authorization, exact per-cell ceilings, protected environments, and explicit schedule enablement bound this risk. - Public reports can leak provider data. The workflow publishes only a separately projected report and validates every file before upload. - The new workflow cannot publish until it is present on the default branch. This pull request does not change the existing `runner-full-stack-e2e` publication path. - The campaign is large. It uses two GitHub matrices and caps combined concurrency at the shared fleet limit. > For core feature work, check [`ROADMAP.md`](ROADMAP.md) first and discuss it in `#dev` before opening the PR. Feature PRs that overlap with planned core work may need to be redirected — check the roadmap first. See `CONTRIBUTING.md`. ## Model Used OpenAI Codex on GPT-5. The exact deployment ID and context-window size are not exposed. The model used reasoning, code editing, browser inspection, repository tools, and live provider execution. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge |