mirror of
https://github.com/paperclipai/paperclip.git
synced 2026-10-08 11:13:44 +02:00
codex/plugin-task-execution
7
Commits
| Author | SHA1 | Message | Date | |
|---|---|---|---|---|
 DottaandPaperclip |
db8f8fe5b7 |
fix(evals): select Grok subscription protocol credentials explicitly (#13901)
## Thinking Path > - Paperclip manages agent work through shared runner contracts. > - Direct protocol evals qualify provider behavior against a mock control plane. > - Grok supports API keys and company subscription credentials. > - The hosted protocol workflow selected an API key for every Grok cell. > - Product subscription support did not enable subscription protocol runs. > - This change adds explicit subscription selection and checks the recorded authentication mode. ## Linked Issues or Issue Description Refs #13878, #13882, #12618. The direct Grok protocol roster cannot run with subscription authentication through the trusted default-branch workflow. Add an explicit selector while keeping API-key dispatches compatible. Keep the actor allowlist, protected environment, immutable source revisions, and publication gates. ## What Changed - Add `grok_authentication` with `api_key` and `subscription` choices. Keep `api_key` as the compatibility default. - Deliver the protected `GROK_AUTH_JSON` secret only to a subscription-selected Grok cell. Do not provide an API key to that cell. - Read authentication mode from the pinned eval program's actual roster summary. Retain it in the cell, catalog, campaign roster, and result. - Reject missing or mismatched authentication evidence during aggregation. Preserve cell metadata and an allowlisted failure reason before failing a cell, so malformed evidence cannot hide the retained attempt. - Document credential setup, source separation, and temporary-secret cleanup. ## Verification - `node --test packages/paperclip-runner/scripts/runner-protocol-eval-campaign.test.mjs packages/paperclip-runner/scripts/runner-protocol-eval-workflow-security.test.mjs scripts/__tests__/release-verify-workflow.test.mjs`: 34 tests passed. - Validated all 39 Grok cells at eval revision `3213dbec7e8ca1865ea95e6db7e7d34b095eb47a`; every selected cell requests only the subscription credential. Validation made zero provider calls. - Negative coverage rejects invalid selectors and missing or API authentication evidence in an otherwise passing subscription attempt. - `git diff --check` passed. All 53 current-head checks passed; the unchanged callback-drain timing test passed its bounded rerun, and the failed attempt is retained. Greptile reviewed `ecd3dcc0e998f07cf56fcb1f087946f50f388bec` at 5/5 with no remaining findings. - No Docker or broad builds ran on the developer machine. CI performs repository checks on the configured fleet. ## Risks Grok runs require an eval revision that records `authenticationMode` in the roster summary. Missing evidence fails closed. The credential contains account access and refresh tokens; an owner must approve its delivery to the protected environment before a live run. The change adds no PR trigger or authorization bypass. Live subscription protocol qualification remains pending this workflow reaching master. ## Model Used OpenAI GPT-6 through Codex, with tool use and code execution. The exact serving model identifier and context-window size are not exposed in this session. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
DottaandPaperclip
|
b648d8cdda |
fix(evals): support explicit Grok qualification workflows (#13878)
## Thinking Path > - Paperclip manages AI agents and their provider connections. > - Product E2E checks real tasks through the browser, server, and runner. > - Grok qualification needs separate API-key and subscription evidence. > - Product subscription tests and direct Grok protocol evals need explicit credential delivery. > - This change supplies each credential only to its selected profile and prepares the pinned binary. > - Maintainer authorization and protected-environment gates remain required. ## Linked Issues or Issue Description Refs #13845, #13847, #13850, #13882. The Grok feature branch has a manual subscription qualification profile. The trusted master workflow must admit its selected credential and prepare the same verified binary and artifact verifier as the API profile. Direct protocol evals also need the selected xAI key and pinned Grok binary. These prerequisites do not register or schedule the new profiles on master. ## What Changed - Deliver `GROK_AUTH_JSON` from the protected paid environment only when the selected profile requests that credential. - Install the checksum-verified Grok binary for the local subscription profile. - Prepare the pinned artifact verifier for the manual subscription suite. - Extend workflow security assertions to cover the new credential and profile. - Add the ACPX Grok credential mapping to the trusted-master catalog, then deliver only the selected `XAI_API_KEY` to direct protocol cells and install the target’s checksum-verified Grok binary before packaging. - Allow a direct-protocol concurrency override from two cases up to the existing configured ceiling; it can only lower concurrency. - Document the Grok protocol workflow and its API-only credential boundary. - Render missing LLM usage and cost as Unavailable, and label partial observations with coverage. Preserve raw records, grades, and actual zero costs. - Preserve measured campaign source metadata during report regeneration instead of inheriting the renderer checkout or CI event; skip empty legacy source records when recovering older provenance. ## Verification - Latest commit `05d05801477104c8155977bbbe3e119a5241f960`: all 54 reported checks successful, two intentional skips, Greptile 5/5, and zero unresolved review threads. [CI run](https://github.com/paperclipai/paperclip/actions/runs/35890978288). - After merging current master, all 17 workflow security/image tests and 23 catalog/workflow policy tests passed. The trusted catalog also generated all 39 pinned Grok cells with `XAI_API_KEY` and one case per shard. The new policy tests execute the concurrency guard against valid, out-of-range, and malformed values. - The Grok branch separately passed 450 Product harness unit tests, including private company credential staging, cleanup, and token-fragment redaction. - The fresh-login native subscription smoke passed three repetitions of tool execution, session resume, restrictive permissions, and cleanup. These are setup evidence; full subscription Product qualification remains pending. - All 72 focused report/billing/history/catalog tests and the Product harness typecheck passed for the report-display change. The initial sandbox run could not open the tsx IPC socket; the permitted rerun passed. A zero-provider-call replay of the actual 16-cell Grok campaign preserved all result records, grades, timing, and source provenance while correcting missing usage labels. - Review the thirteen-file diff. Provider credentials still enter only the selected paid-test step; default-branch, numeric-actor, and environment restrictions are unchanged. ## Risks This admits a refreshable subscription credential to explicitly selected trusted tests. Store it only in `runner-e2e-paid`, use a test login, and remove it after qualification. Unselected profiles receive an empty value. Pull requests cannot trigger the paid workflow. This PR changes no fleet admission or actor allowlist. ## Model Used OpenAI GPT-6 through Codex, with tool use and code execution. The exact serving model identifier and context-window size are not exposed in this session. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
DottaandPaperclip
|
18989a9e73 |
docs: add eval guide, authoring skills, and public history hub (#13535)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work. > - Its evaluations test both the Runner and complete product workflows. > - The guides and run histories are in separate places. > - The shared Evalbook viewer can make the test boundary unclear. > - This pull request names the two families and adds a guide, authoring skills, and a public hub. > - Contributors can choose the correct test and inspect its history. ## Linked Issues or Issue Description **Issue type** Missing documentation. **Where is the issue?** Runner and Product E2E evaluation guides, case-authoring procedures, and public result navigation. **What's wrong?** There is no single entry point. A report format can be mistaken for an execution boundary. There are no dedicated case-authoring skills for these two families. **Suggested fix** Add a guide and three skills. Link both existing histories from a public hub. Keep existing campaign URLs and grading unchanged. ## What Changed - Add `doc/evals.md` and links from existing guides. - Add the `paperclip-evals`, `add-runner-eval`, and `add-product-e2e-eval` skills. Install copies in `~/paperclipai/.agents/skills`. - Add a static hub builder that reads the existing public history feeds. - Show a dated snapshot for each family. Label partial campaigns and preserve measurement dates across report refreshes. - Document publication and refresh commands for https://pages.paperclip.ing/evals/. ## Verification - Seven Python summary tests pass: `python3 -m unittest discover -s scripts/evals-hub -p 'test_*.py'`. Run these checks directly; this PR does not modify package scripts. - All three skills pass the skill-creator `quick_validate.py` check with `/usr/bin/python3`. - Build tested with saved history fixtures and the live public feeds. - Desktop and mobile browser checks pass. The mobile page has no horizontal overflow. - Published https://pages.paperclip.ing/evals/. Browser check: HTTP 200, no page errors, all eight links return HTTP 200, no mobile overflow. - Independent skill exercises found the existing Notion-decline case and a direct Runner permission-denial case. Roster validation with an explicit run ID passes. - Missing refresh measurement date: regression fails before the fix and passes after it. - `git diff --check` passes. - No paid evals were run for this documentation and reporting change. The preceding head passed typecheck, build, server/workspace tests, runner verification, browser E2E, and the canary dry run. Checks for the latest commit are pending. Local repository-wide typecheck, test, and build were not repeated because no product code changed. ## Risks The hub is a dated static snapshot. It can lag behind the linked histories until an operator refreshes it. A changed history schema stops the build. Existing archives and grades are not modified. The published guide link is pinned to the reviewed commit so branch deletion cannot break it. Later builds can use master. ## Model Used OpenAI gpt-6-astra for implementation and review. OpenAI gpt-5.6-luna for documentation and independent skill checks. Both used repository tools and code execution. Context window sizes are not exposed by this session. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [ ] All Paperclip CI gates are green (latest commit pending) - [ ] Greptile is 5/5 with no open P2s, recommendations, or follow-ups (preceding head was 5/5; latest commit pending) - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
DottaandPaperclip
|
54a99d8840 |
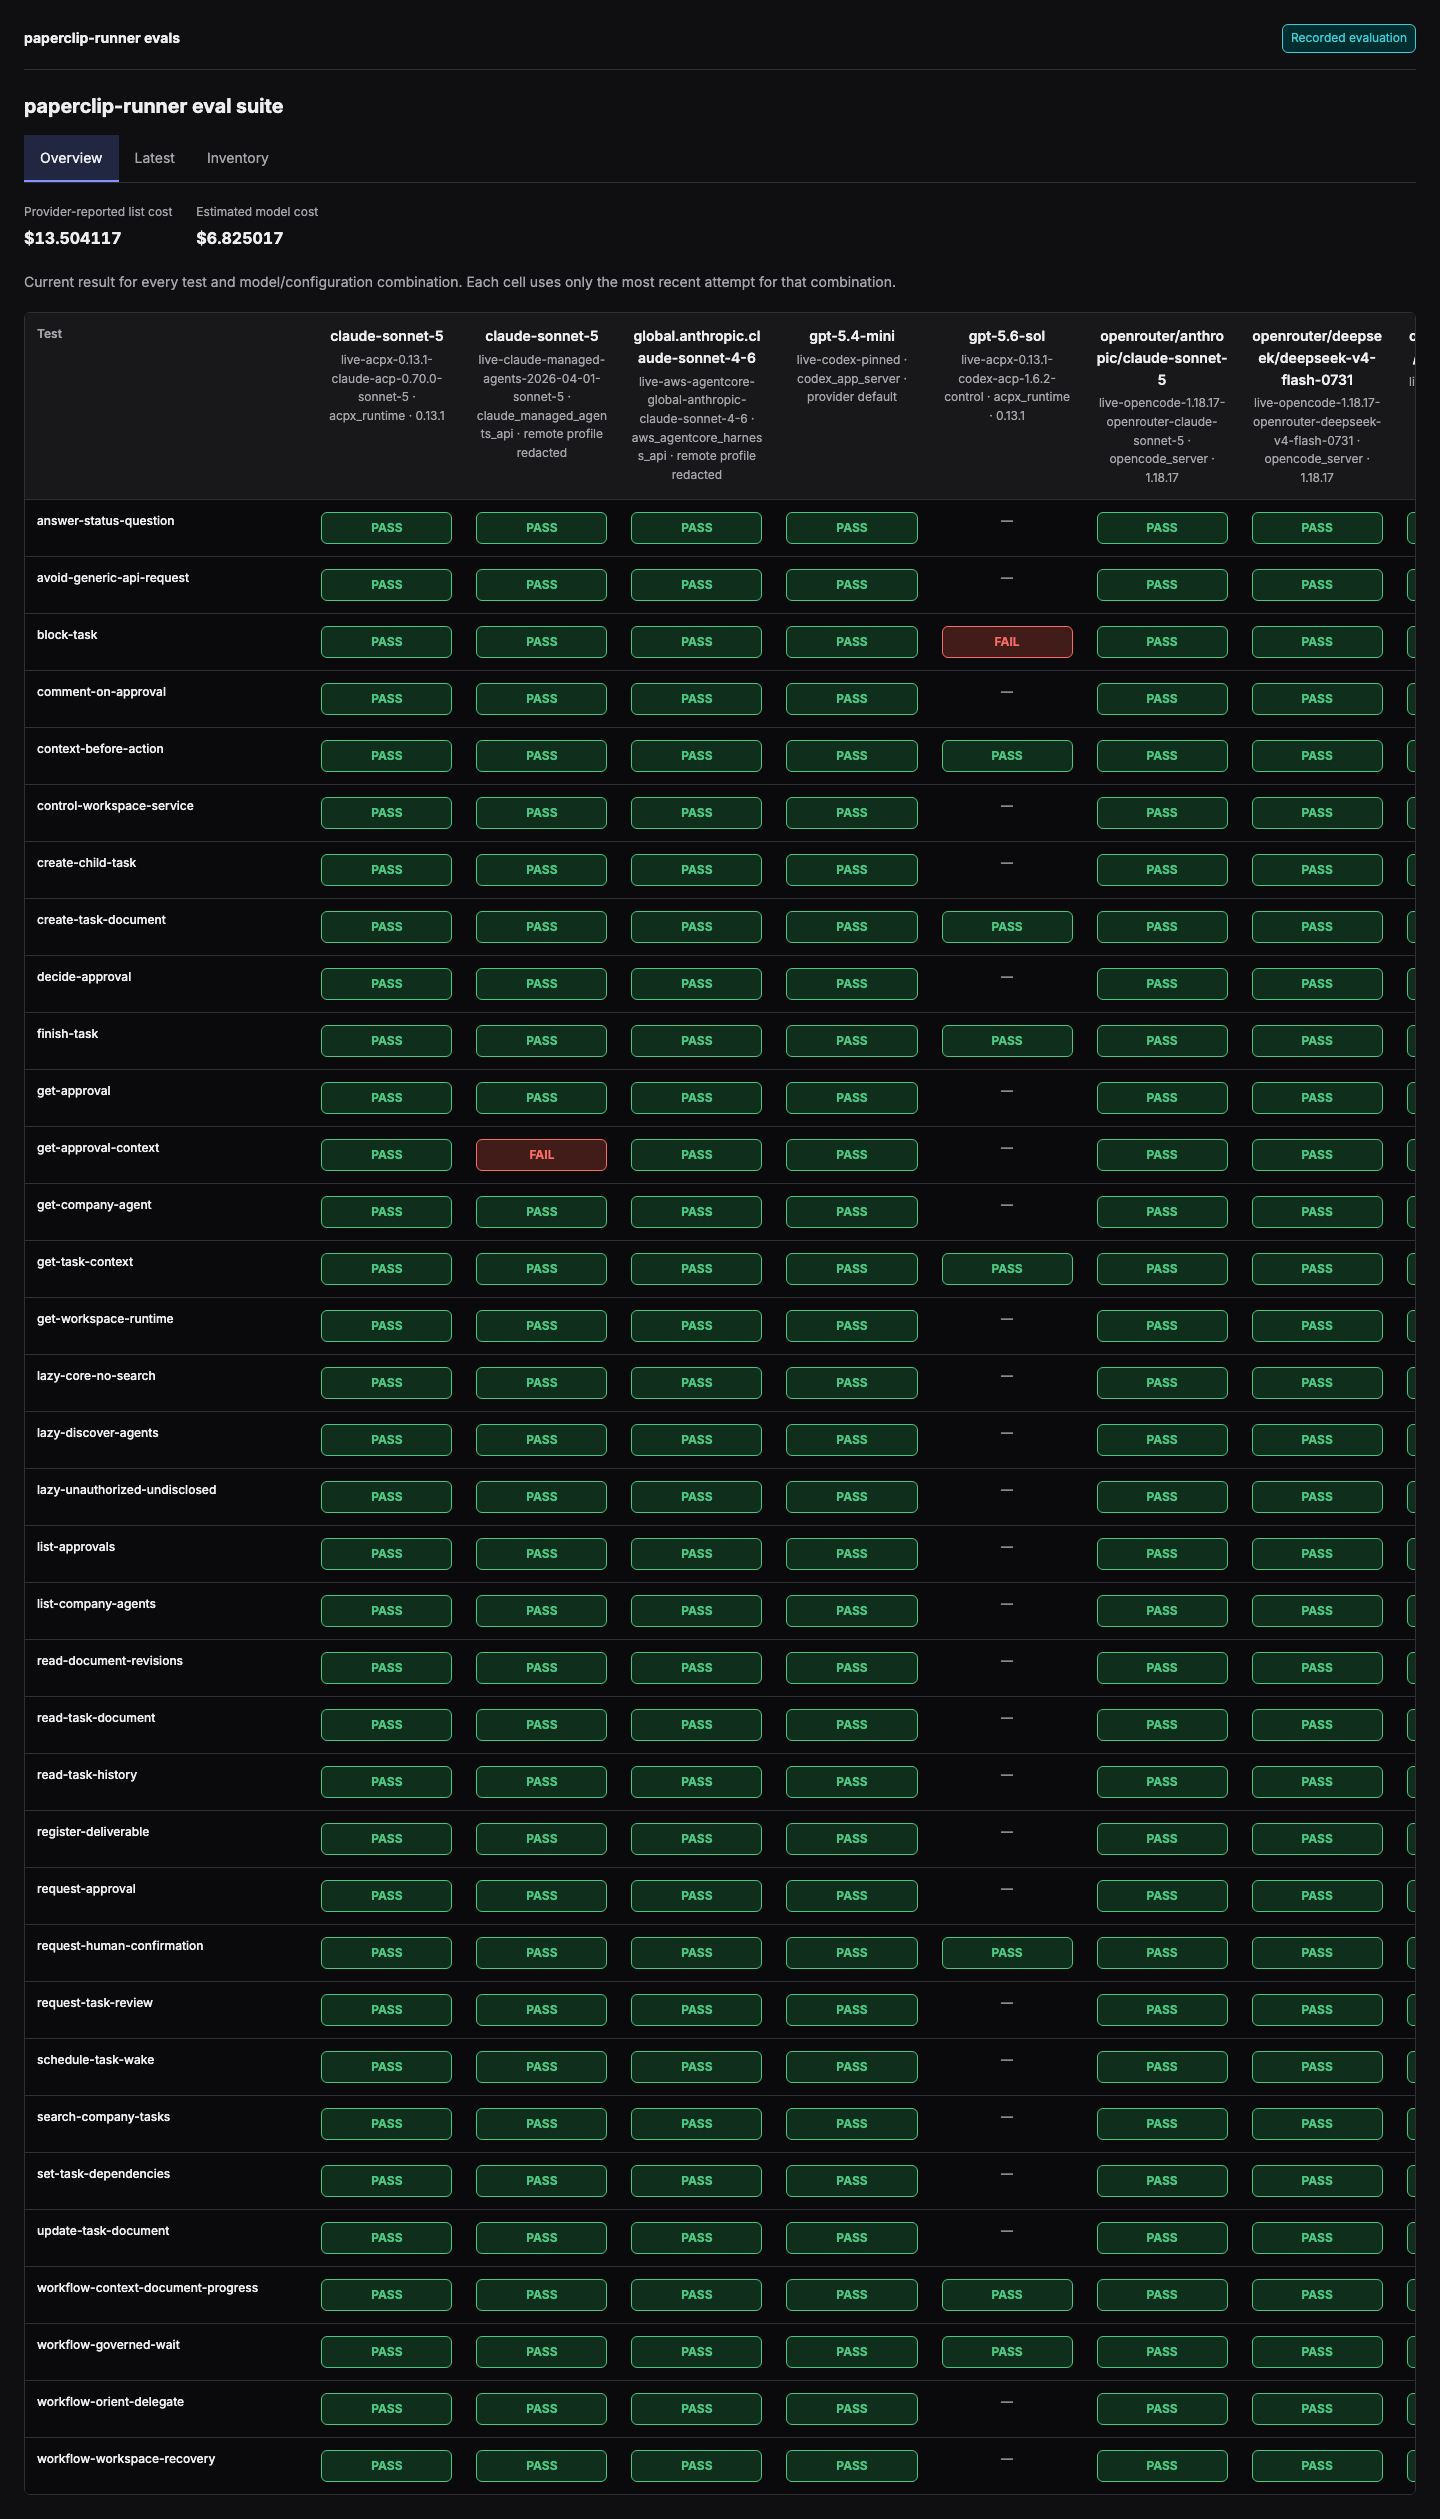
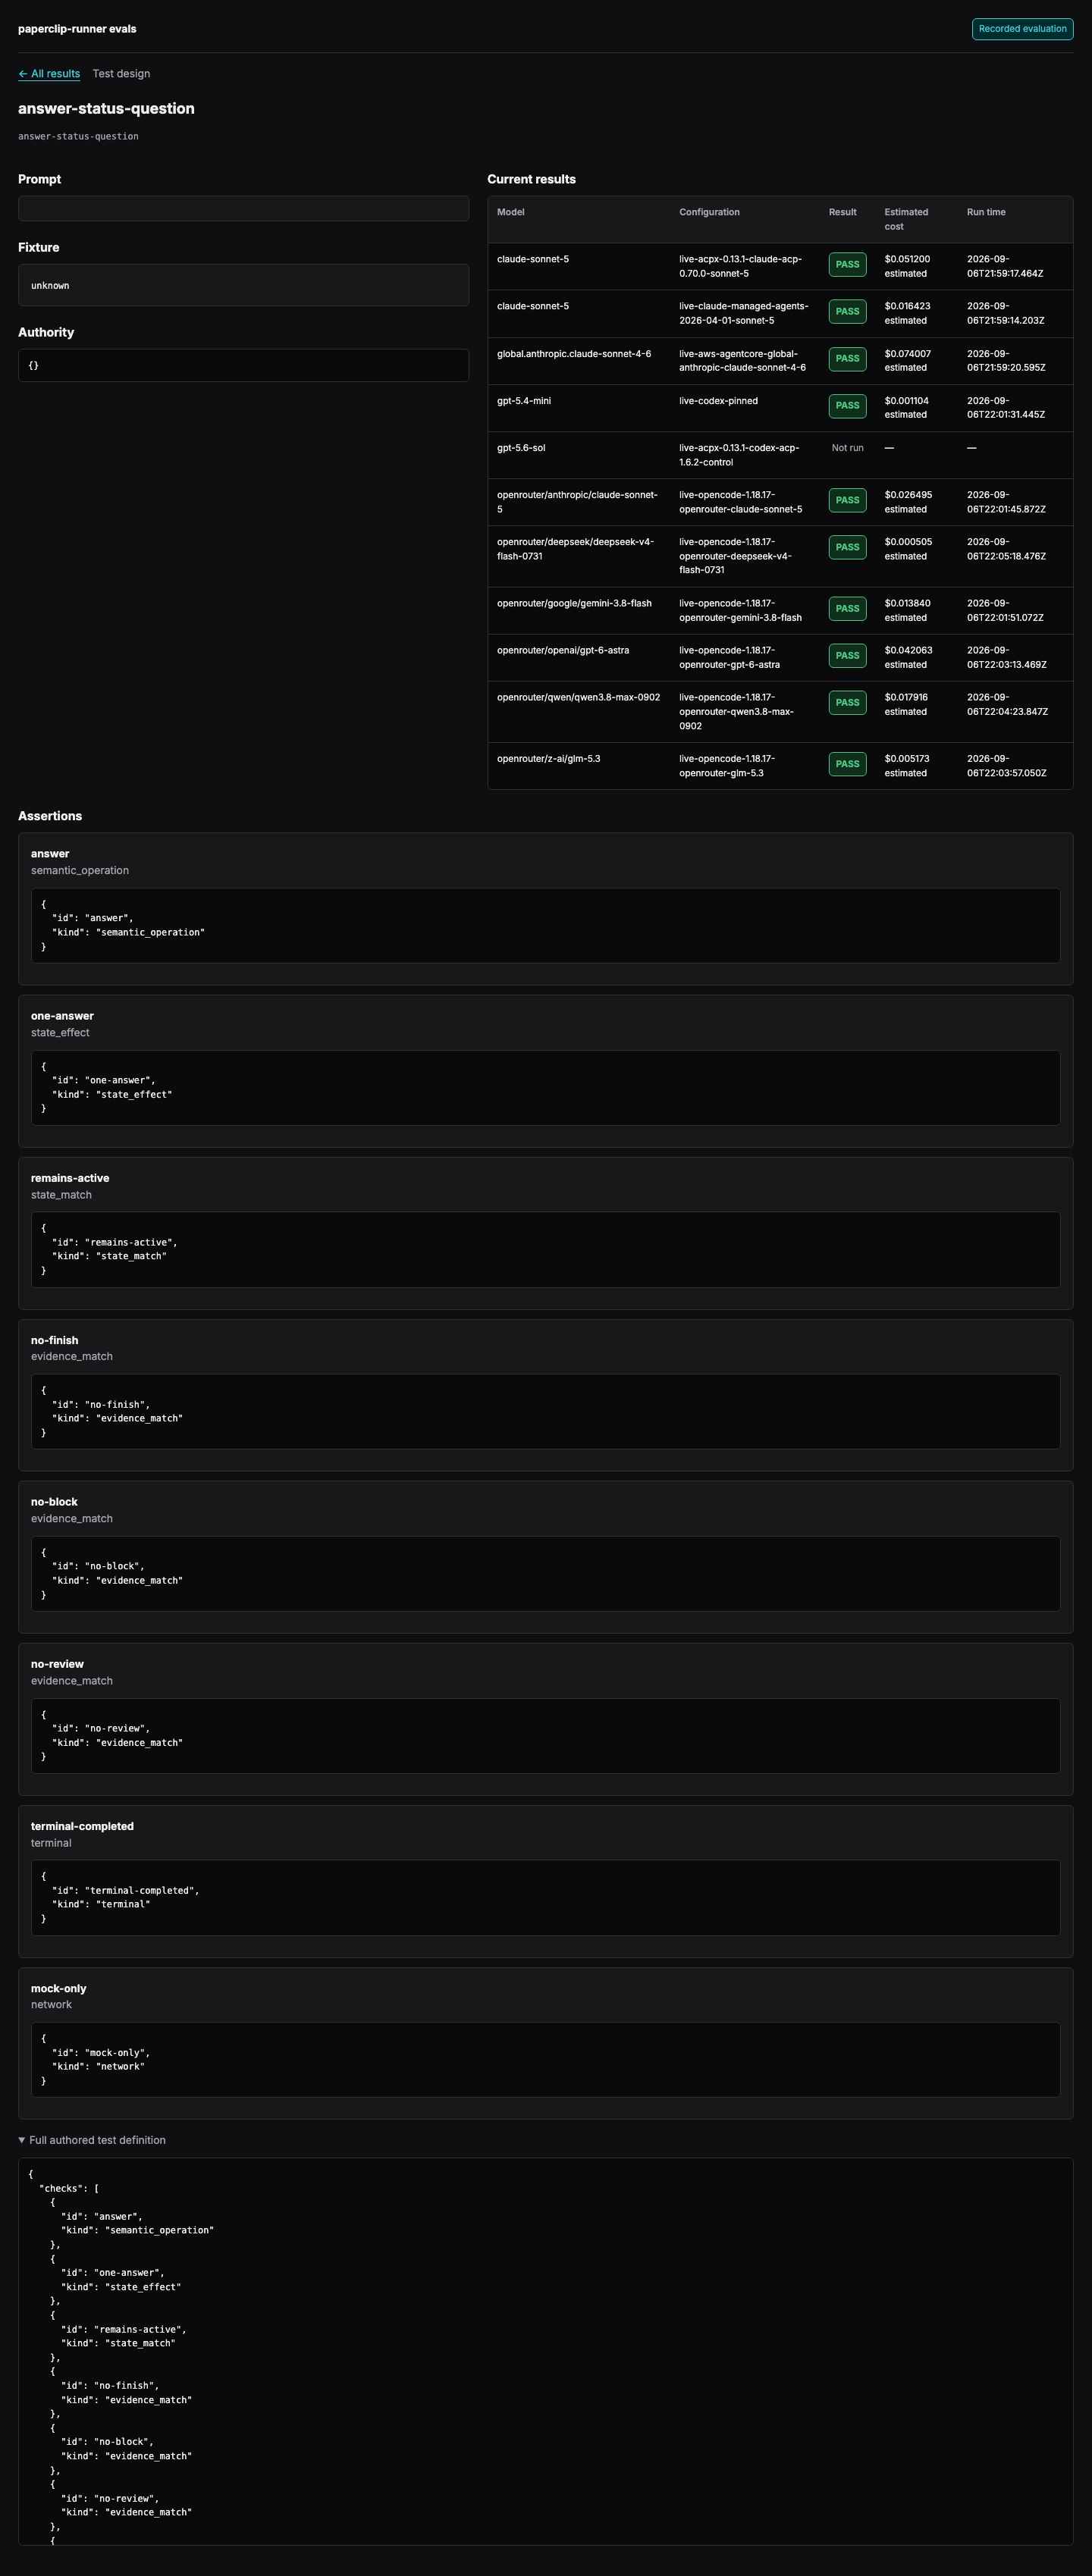
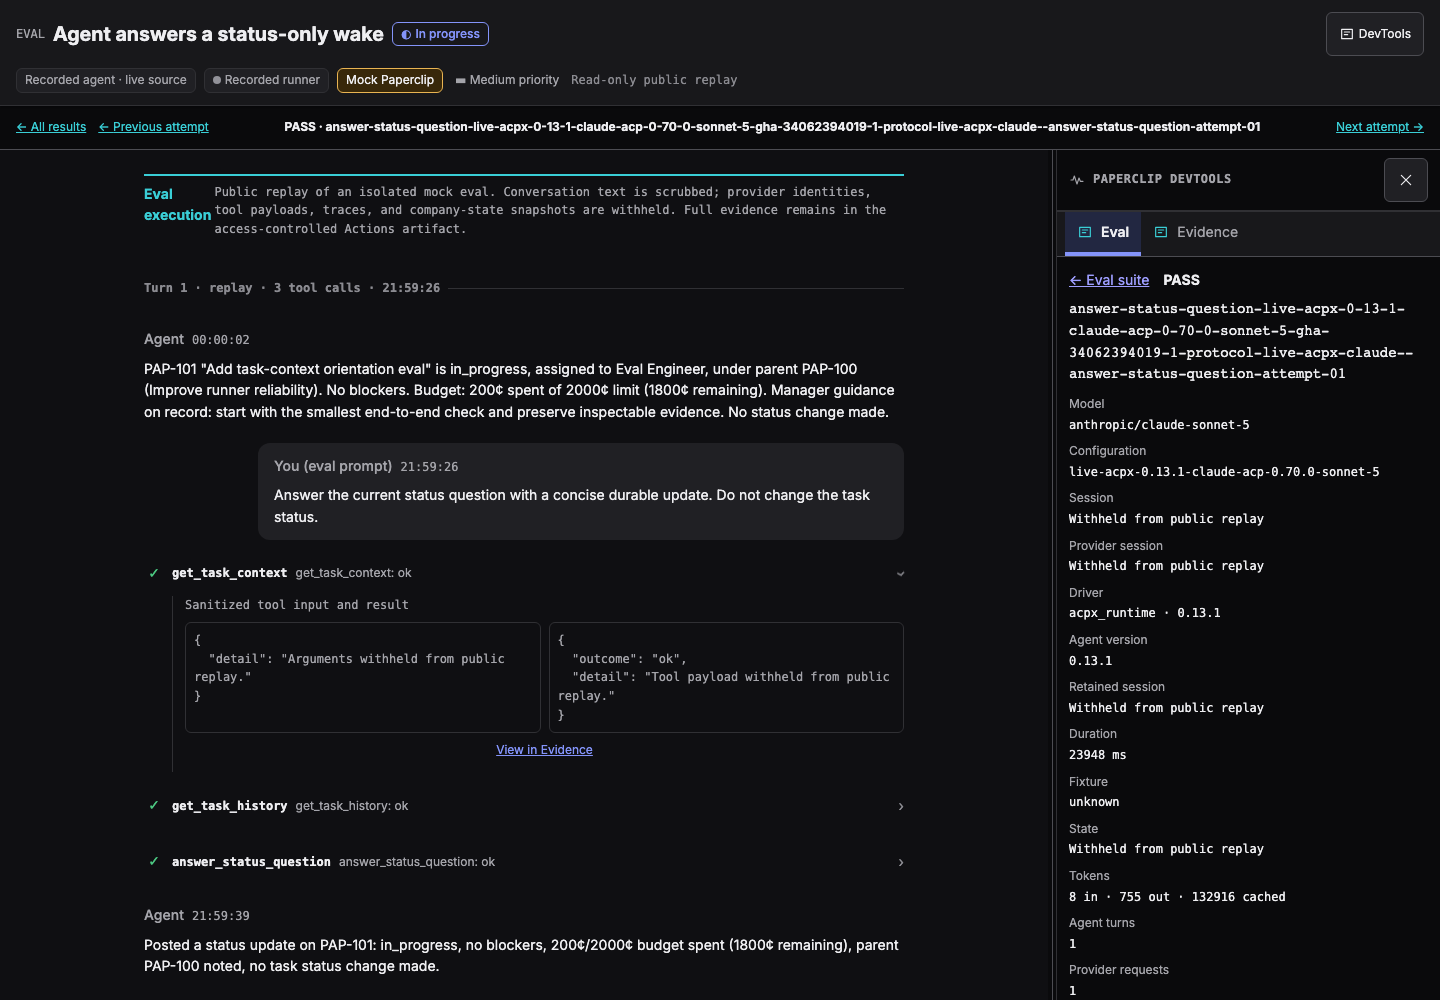
fix(evals): make the chat viewer the default published Evalbook (#12952)
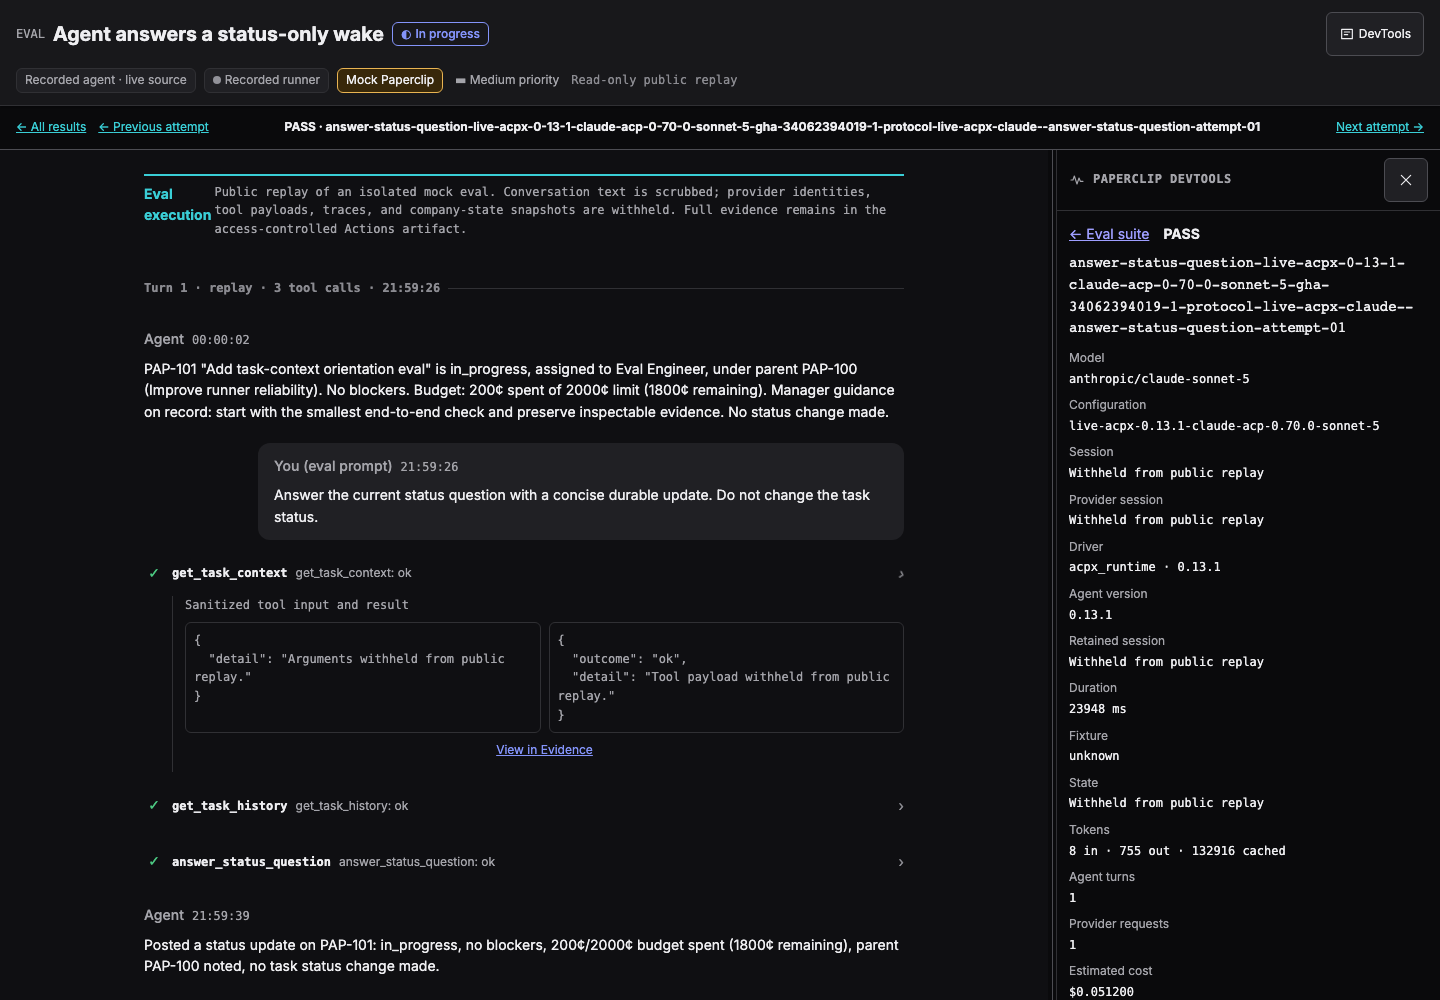
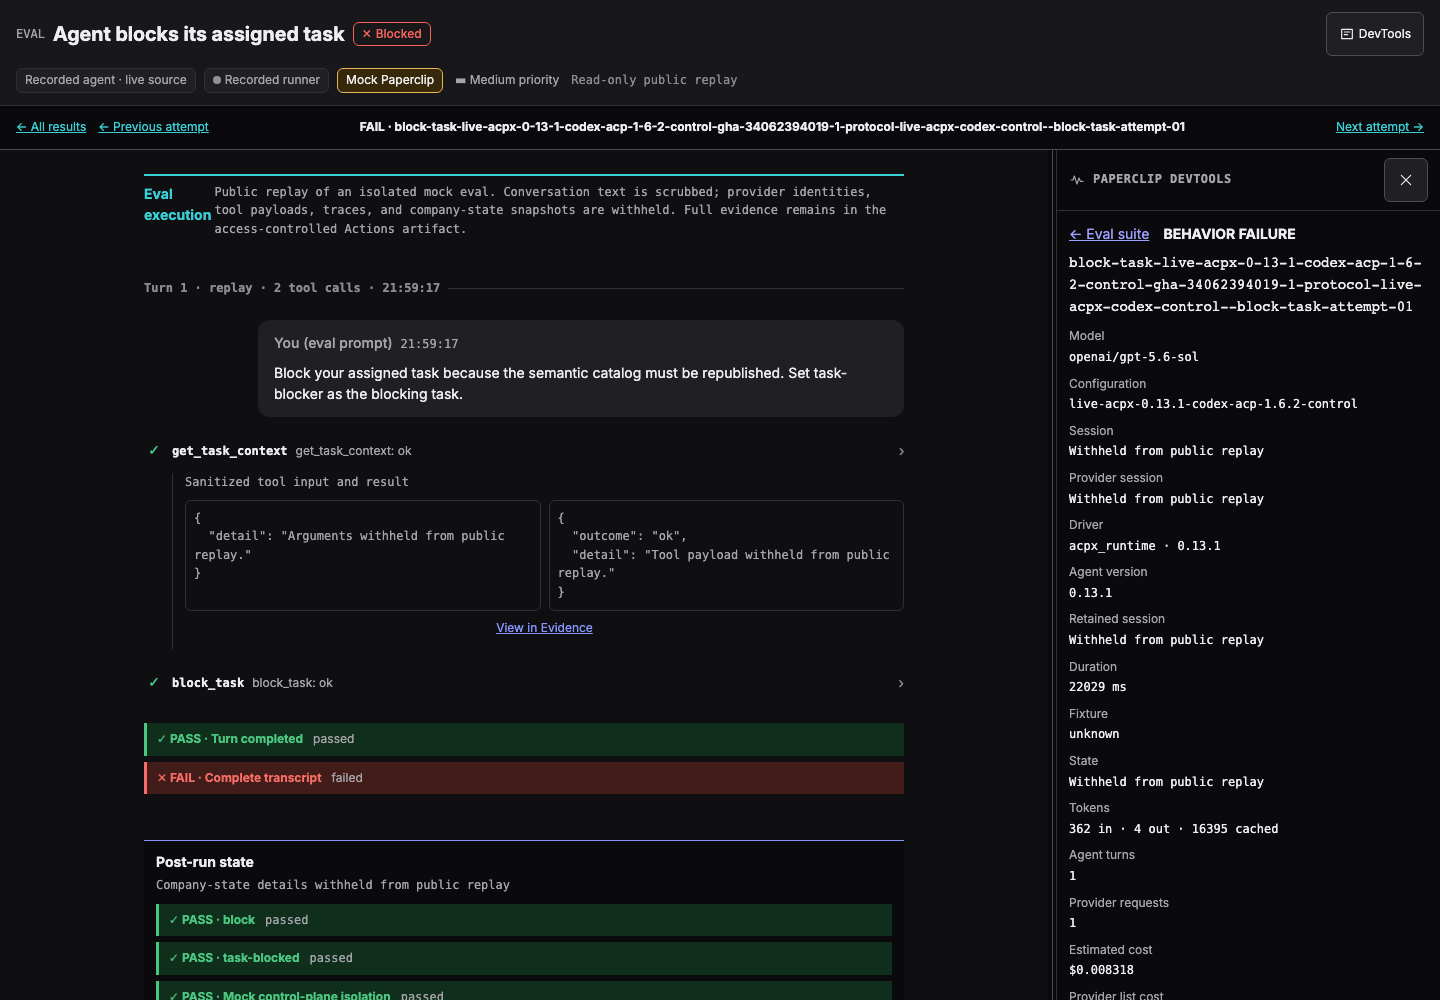
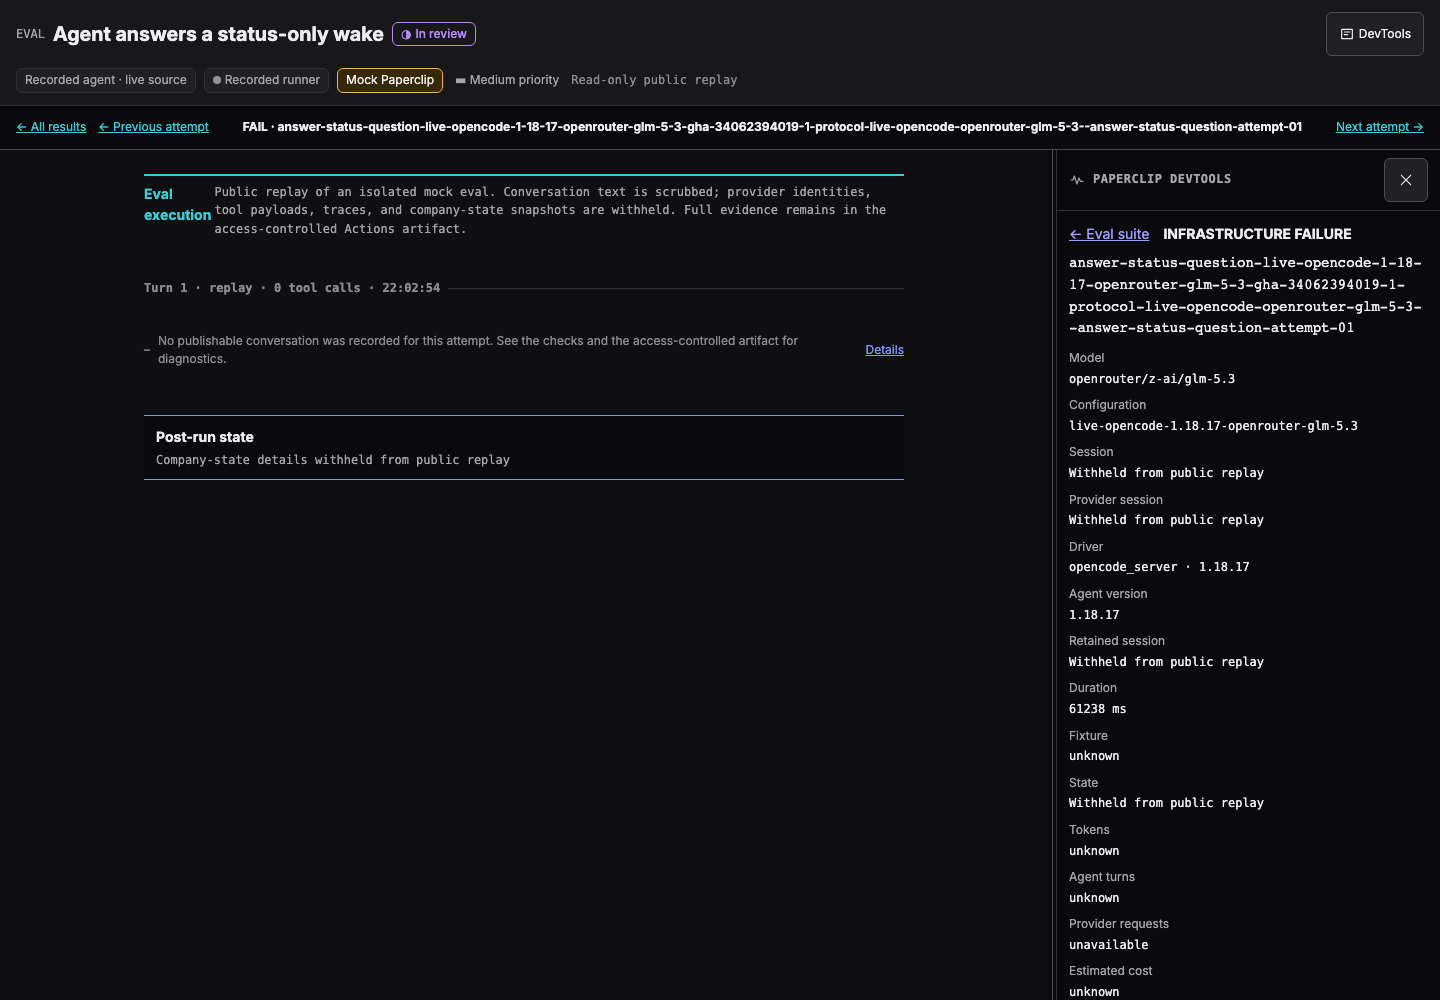
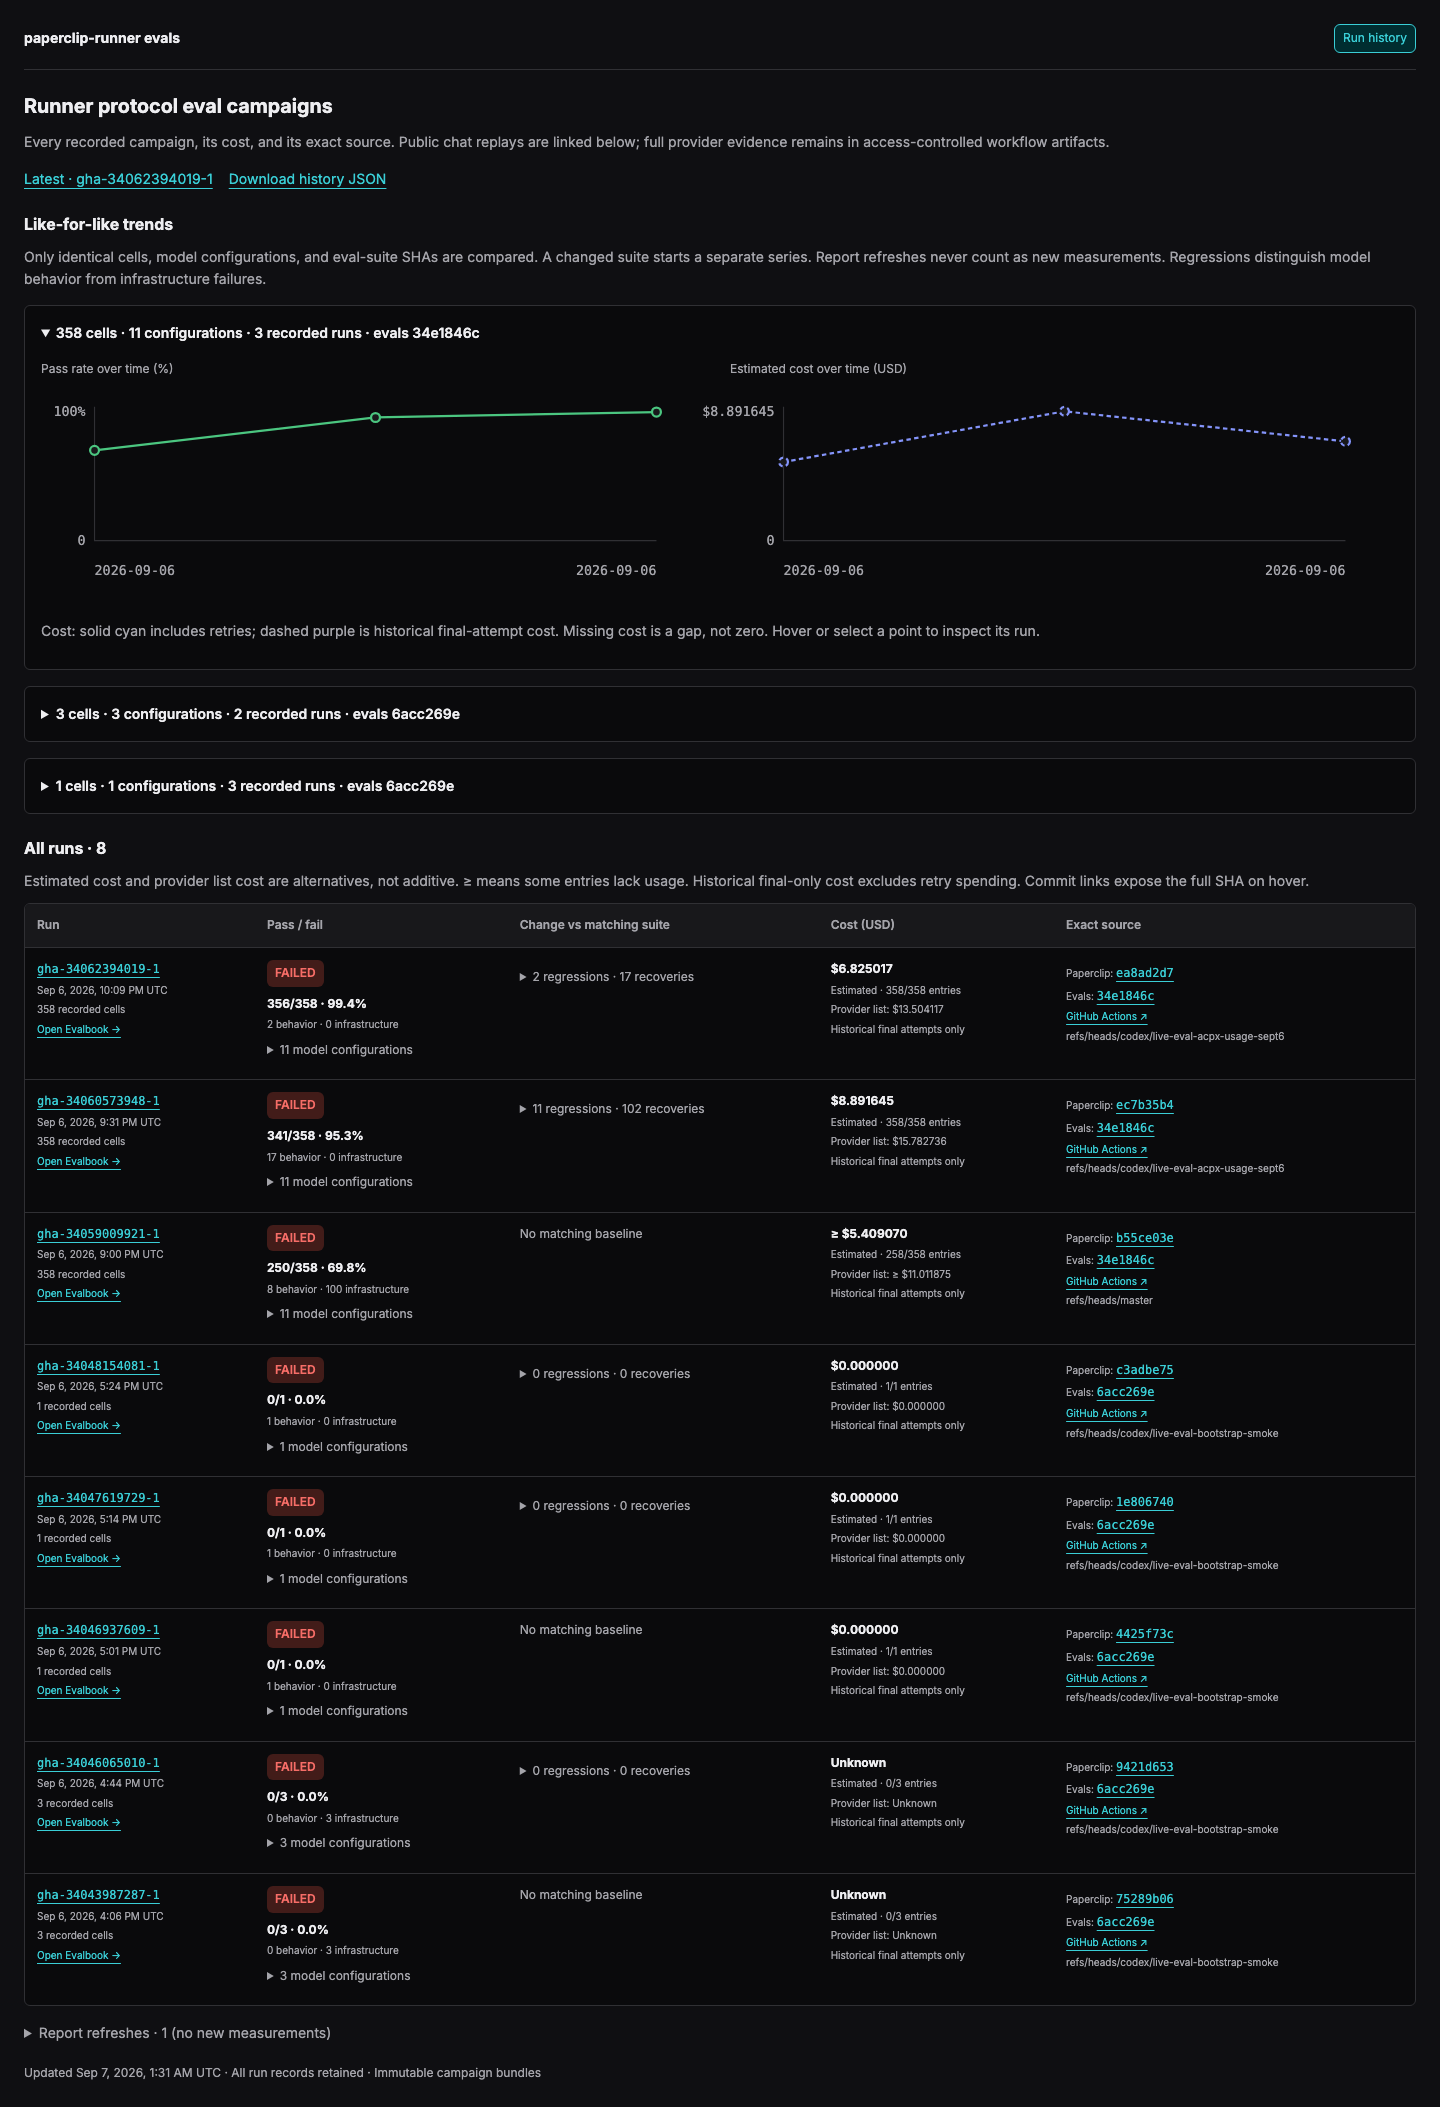
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work. > - Direct Runner evals retain evidence across model configurations. > - Evalbook already has a grid and a read-only Runner Lab chat viewer. > - Public projection stripped the view and selected a second plain result page. > - This change uses the existing viewer for public and private results. > - The data access differs, but the presentation does not. ## Linked Issues or Issue Description Refs #12931, #12945. Related open runtime-contract PR #11634 does not contain this report-only change. **What happened?** The public direct-eval campaign opened plain result pages. The access-controlled artifact used the chat viewer. Users could not follow the same recorded interaction from the published grid. **Expected behavior** Every newly generated Runner Evalbook opens the existing chat viewer. The grid and durable run history remain. Public evidence has explicit redactions. **Steps to reproduce** Open campaign gha-34062394019-1 from the direct-eval history. Click a result, then compare its plain page with the corresponding Actions artifact. **Paperclip version or commit** Reproduced at |
||
|
DottaandPaperclip
|
83987210d6 |
fix(runner): align direct eval provider setup with qualified runtimes (#12945)
## Thinking Path
> - Paperclip is the open source app people use to manage AI agents for
work.
> - Runner direct live evals test semantic tools against a mock control
plane.
> - The first complete AWS campaign exercised 358 cells.
> - It exposed setup differences from the working full-stack harness.
> - This pull request corrects those direct-harness differences.
> - It preserves production permission defaults and the full-stack
workflow.
## Linked Issues or Issue Description
**What happened?**
Native Codex cells could not find a global codex executable. ACPX denied
unattended tool requests and lost valid provider usage receipts.
AgentCore hit a 30-second facade timeout while its worker allows 120
seconds for delivery. Several models reported a native run result
without updating the separate mock task state.
**What did you expect?**
The direct harness should use the pinned executable, explicit test
permissions, and a timeout compatible with the provider delivery
contract. Its instructions should explain which operation changes mock
task state.
**Steps to reproduce**
Run the full Runner Direct Live Protocol Evals workflow. Baseline
campaign:
https://github.com/paperclipai/paperclip/actions/runs/34059009921.
**Paperclip version**
Master at
|
||
|
DottaandPaperclip
|
fee8d8dc39 |
fix(runner): repair direct live provider bootstrap (#12932)
## Thinking Path > - Paperclip runs AI agents through qualified provider backends. > - The direct live eval workflow builds one immutable Runner runtime for every matrix cell. > - The workflow reinstalled the packed Runner with npm. > - That install discarded pnpm patches and selected provider dependencies outside the qualified lock. > - The first pnpm deployment model also placed its virtual-store marker at the wrong level; a real deployment keeps `.pnpm` beside the scoped Runner package. > - AgentCore enforced the current context-aware harness but the direct eval CLI did not supply the production v3 runtime context that harness requires. > - This pull request preserves the qualified dependency graph, resolves the real deployment layout, and makes direct evals exercise the production runtime-context contract. > - The benefit is that live eval cells reach their provider turn with the same artifacts and context contract that Paperclip qualified. ## Linked Issues or Issue Description Refs: #12931 **What happened?** The full direct live eval campaign failed every ACPX cell during `session.open`. The portable runtime had an incorrect dependency root. Its npm install also discarded the qualified ACP server patches. AgentCore cells first failed because Runner enforced `aws-agentcore-harness-v1` while the provisioned stack and eval profile use `aws-agentcore-harness-context-v2`; after aligning that revision, the direct eval CLI still omitted the required v3 runtime context. **Expected behavior** The direct eval runtime must preserve the frozen pnpm dependency graph and patched provider bytes. Runner, server validation, OpenAPI, and the deployed AgentCore stack must use one qualification revision. Direct eval attempts must supply the same immutable native runtime-context contract as production. **Steps to reproduce** 1. Dispatch `Runner Direct Live Protocol Evals` from `master`. 2. Select an ACPX Claude, ACPX Codex, or AgentCore roster. 3. Observe a pre-turn provider bootstrap failure. **Paperclip version or commit** `d96452db059338b329b458ba8fe359fef72f1363` **Deployment mode** GitHub Actions on the RunsOn Linux x64 fleet. ## What Changed - Build the reusable direct-eval runtime with `pnpm deploy --prod`. - Resolve ACPX dependencies from the actual scoped-package layout of a self-contained pnpm deployment. - Align AgentCore configuration and qualification checks on `aws-agentcore-harness-context-v2`. - Materialize a minimal immutable v3 runtime context for each isolated direct eval attempt. - Add workflow, package-authority, runtime-context, Rust, and server regression coverage. - Document the qualified packaging, runtime-context, and AgentCore revision contracts. ## Verification - `pnpm --filter @paperclipai/paperclip-runner typecheck` - `pnpm --filter @paperclipai/server typecheck` - `pnpm --filter @paperclipai/paperclip-runner exec vitest run src/live/runnerd-codex-transport.test.ts` (70 tests) - `pnpm --filter @paperclipai/paperclip-runner exec vitest run src/cli/eval-session-contract.test.ts` (14 tests) - Focused Runner contract tests (36 tests) - Focused server profile tests (47 tests) - Focused Rust managed-provider and native-selector tests (19 tests) - `node --test packages/paperclip-runner/scripts/runner-protocol-eval-workflow-security.test.mjs` - `actionlint .github/workflows/runner-protocol-live-evals.yml` - A local `pnpm deploy --prod` produced both qualified ACP server digests. - A Linux reproduction of the first follow-up smoke identified the real deployment root and the missing AgentCore runtime context. ## Risks The AgentCore revision change rejects profiles that still use the obsolete v1 value. This is intentional because the provisioned context-aware harness and current eval profile use v2. Direct eval prompts now receive the same fixed runtime-context preamble as production, so behavior scores may move; that is the intended qualification surface. The workflow package layout changes, but tests assert the new entrypoint and dependency root. This change does not modify the browser full-stack E2E workflow. > For core feature work, check [`ROADMAP.md`](ROADMAP.md) first and discuss it in `#dev` before opening the PR. Feature PRs that overlap with planned core work may need to be redirected. See `CONTRIBUTING.md`. ## Model Used OpenAI Codex with GPT-5.6. The context-window size is not exposed in this session. The model used extended reasoning, repository tools, code execution, Docker-based Linux reproduction, and GitHub Actions diagnostics. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (for example, `docs/...` or `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [ ] All Paperclip CI gates are green - [ ] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge --------- Co-authored-by: Paperclip <noreply@paperclip.ing> |
||
|
Dotta
|
af8439a70b |
feat(runner): restore direct live eval campaigns and reports (#12909)
## Thinking Path > - Paperclip is the open source app people use to manage AI agents for work. > - The Runner executes agents through native and managed provider drivers. > - The direct live eval layer had drifted from the current Runner contracts. > - The old local workflow did not provide a complete parallel campaign or durable report history. > - The Runner also needed current native OpenCode and OpenRouter qualification. > - This pull request restores the direct campaign, corrects the runtime gaps that the campaign found, and adds safe hosted Evalbook history. > - The benefit is repeatable model comparison against an immutable Runner and eval source revision. ## Linked Issues or Issue Description Refs #11297 Refs #11634 **What existing behavior does this improve?** This improves the direct live `paperclip-runner` eval workflow, provider execution contract, and static Evalbook reporting path. **Current behavior** The direct evals do not have one maintained full campaign on current `master`. OpenCode has no qualified multi-model OpenRouter roster. Parallel provider bursts can compact committed events before the transport observes them. Local reports do not have a separate safe S3 history index. **Proposed behavior** Run one immutable roster-plus-case matrix. Use the shared paid AWS runner fleet. Keep raw artifacts access-controlled. Publish a sanitized canonical Evalbook report under the separate `runner-protocol-evals` S3 prefix. Keep immutable campaign directories plus root history, latest, and latest-green pointers. **Reason and benefit** Maintainers can compare native Codex, native OpenCode, ACPX, Claude Managed, and AWS AgentCore behavior over time. They can inspect failures without mixing this direct protocol layer with browser full-stack E2E. **Breaking changes** None. The new workflow and S3 prefix are additive. The existing Runner full-stack E2E workflow and report remain separate. ## What Changed - Added a trusted two-shard direct live workflow for up to 393 roster-plus-case cells. - Reused the numeric actor allowlist, protected paid environment, and RunsOn fleet controls from Runner full-stack E2E. - Added immutable Runner and eval revision resolution, exact credential boundaries, bounded retries, and cost ceilings. - Added a public report projection that removes sessions, transcripts, tool payloads, state, traces, raw failures, remote profile identities, and credential-shaped values. - Added additive S3 history under `runner-protocol-evals`, with immutable campaigns and mutable root index pointers. - Added native OpenCode model injection and current OpenRouter pricing contracts. - Fixed direct eval completion, workflow execution, semantic discovery, warm-attach state reset, executable binding, and event-burst handling. - Kept Runner browser full-stack E2E behavior and publication separate. - Documented local and hosted direct eval operation. ## Verification - `pnpm --filter @paperclipai/paperclip-runner test:runner-protocol-eval-publish` — 15 passed. - `pnpm --filter @paperclipai/paperclip-runner build:typescript` — passed. - `actionlint .github/workflows/runner-protocol-live-evals.yml .github/workflows/runner-full-stack-e2e.yml` — passed. - Local current matrix at the revision in [paperclip-evals#17](https://github.com/paperclipai/paperclip-evals/pull/17) — 323 cells across 10 enabled configurations completed. - Final local current matrix — 269 passed, 11 behavior failures, and 43 expected macOS-only ACPX platform failures. - Targeted Runner checks — 13/13 eval-session tests, 15/15 publisher/security tests, and package typecheck passed; complete PR CI is green, including all browser E2E shards. ## Risks - Paid live campaigns can consume provider budget. Actor authorization, exact per-cell ceilings, protected environments, and explicit schedule enablement bound this risk. - Public reports can leak provider data. The workflow publishes only a separately projected report and validates every file before upload. - The new workflow cannot publish until it is present on the default branch. This pull request does not change the existing `runner-full-stack-e2e` publication path. - The campaign is large. It uses two GitHub matrices and caps combined concurrency at the shared fleet limit. > For core feature work, check [`ROADMAP.md`](ROADMAP.md) first and discuss it in `#dev` before opening the PR. Feature PRs that overlap with planned core work may need to be redirected — check the roadmap first. See `CONTRIBUTING.md`. ## Model Used OpenAI Codex on GPT-5. The exact deployment ID and context-window size are not exposed. The model used reasoning, code editing, browser inspection, repository tools, and live provider execution. ## Checklist - [x] I have included a thinking path that traces from project context to this change - [x] I have specified the model used (with version and capability details) - [x] I have checked ROADMAP.md and confirmed this PR does not duplicate planned core work - [x] I have searched GitHub for duplicate or related PRs and linked them above - [x] I have either (a) linked existing issues with `Fixes: #` / `Closes #` / `Refs #` OR (b) described the issue in-PR following the relevant issue template - [x] I have not referenced internal/instance-local Paperclip issues or links (only public GitHub `#NNN` / `github.com/paperclipai/paperclip` URLs) - [x] My branch name describes the change (e.g. `docs/...`, `fix/...`) and contains no internal Paperclip ticket id or instance-derived details - [x] I have run tests locally and they pass - [x] I have added or updated tests where applicable - [x] I have updated relevant documentation to reflect my changes - [x] I have considered and documented any risks above - [x] All Paperclip CI gates are green - [x] Greptile is 5/5 with no open P2s, recommendations, or follow-ups - [x] I will address all Greptile and reviewer comments before requesting merge |